Speaker Diarization
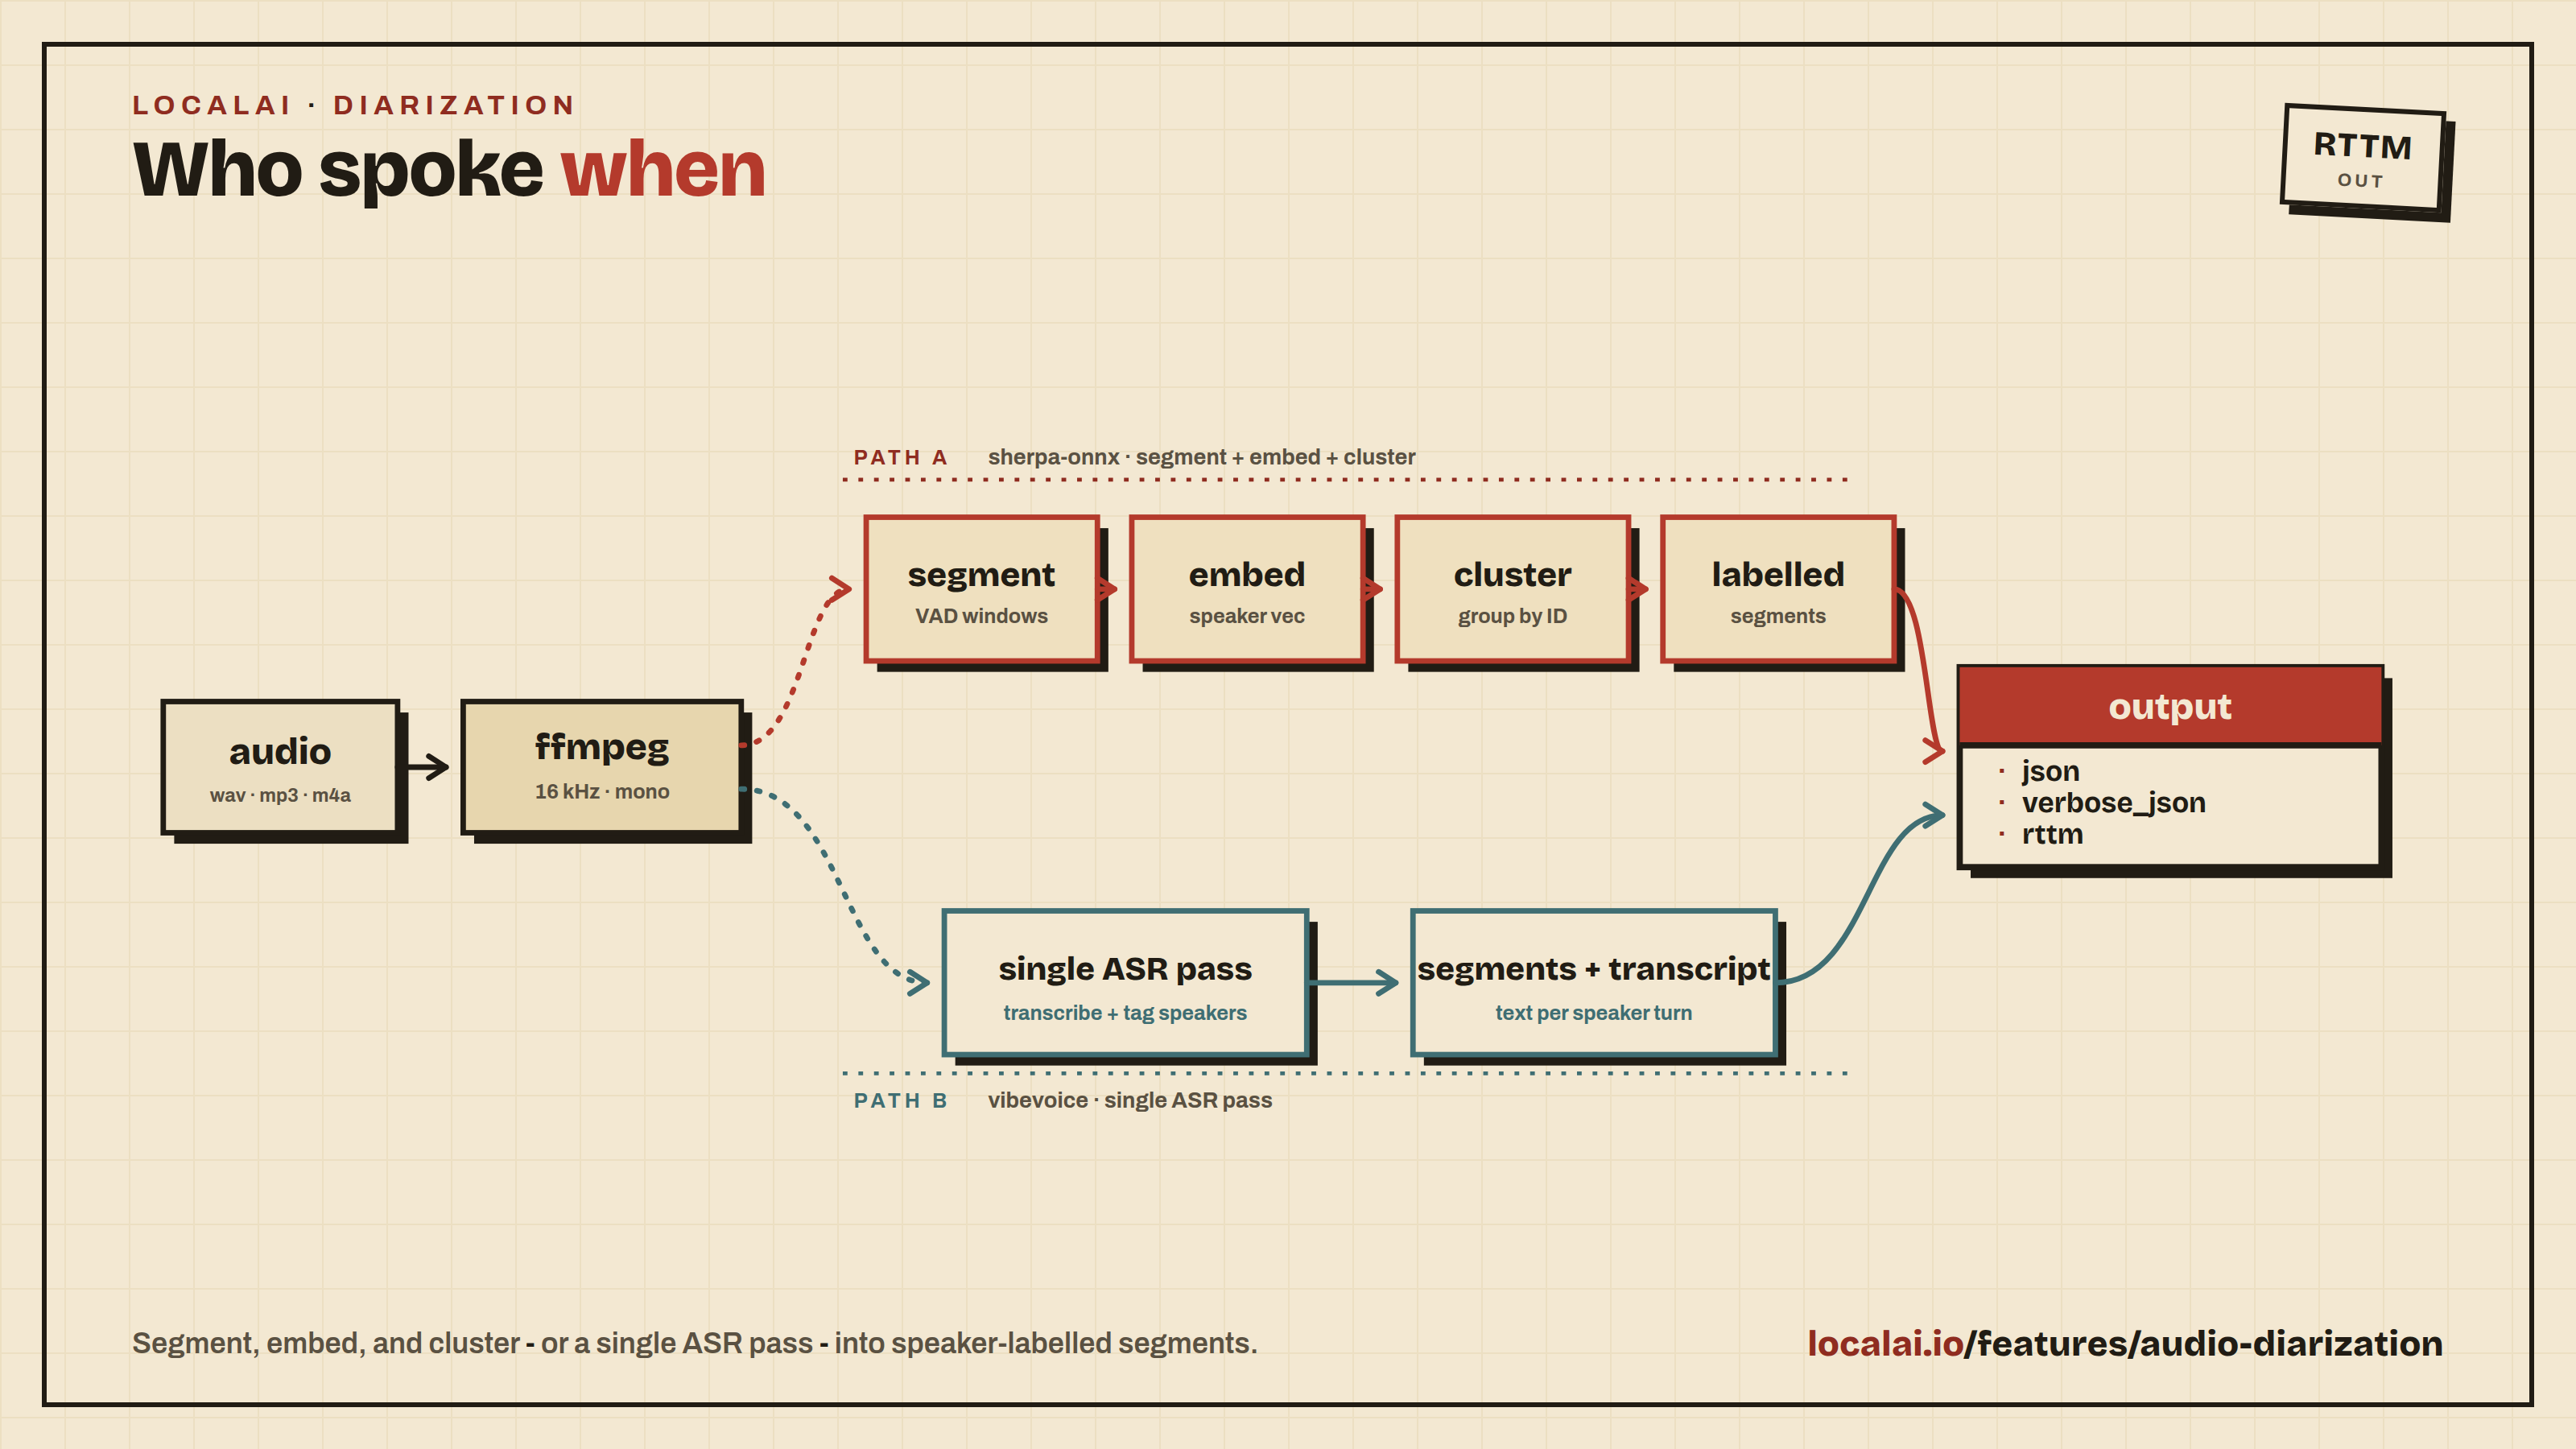
Speaker diarization answers the question “who spoke when?” - given an audio clip with multiple speakers, it returns time-stamped segments labelled with a stable speaker ID (SPEAKER_00, SPEAKER_01, …).
LocalAI exposes this through the /v1/audio/diarization endpoint, modelled after /v1/audio/transcriptions. Five backends are supported today:
- sherpa-onnx - pyannote-3.0 segmentation + a speaker-embedding extractor (3D-Speaker, NeMo, WeSpeaker) + fast clustering. Pure diarization - no transcription cost. Recommended when you only need speaker turns.
- vibevoice.cpp - produces speaker-labelled segments as a by-product of its long-form ASR pass, so you can optionally get a transcript per segment for free.
- NeMo-Speech.cpp - NVIDIA Sortformer, served standalone by the NeMo-Speech.cpp backend. It is end to end, so the speaker capacity is fixed by the checkpoint and the count hints are ignored. The same backend can instead put speaker tags on a transcript, by attaching a Sortformer model to an ASR one.
- audio.cpp - the
sortformer_diarfamily, served by the multi-modality audio.cpp backend. - parakeet.cpp - NVIDIA Nemotron-3-Diarization (Sortformer, up to 8 speakers), served standalone or paired with a Parakeet ASR model for per-segment text. See the Audio to Text page for the parakeet-cpp option reference.
Because diarization is exposed as a regular OpenAI-compatible endpoint, any HTTP client works. There is no Python dependency on pyannote or NeMo on the consumer side.
Endpoint
| Field | Type | Description |
|---|---|---|
file | file (required) | audio file in any format ffmpeg accepts |
model | string (required) | name of the diarization-capable model |
num_speakers | int | exact speaker count when known (>0 forces; 0 = auto) |
min_speakers | int | hint when auto-detecting |
max_speakers | int | hint when auto-detecting |
clustering_threshold | float | cosine distance threshold used when num_speakers is unknown |
min_duration_on | float | discard segments shorter than this many seconds |
min_duration_off | float | merge gaps shorter than this many seconds |
language | string | only meaningful for backends that bundle ASR (e.g. vibevoice) |
include_text | bool | when the backend can emit per-segment transcript for free, populate it |
response_format | string | json (default), verbose_json, or rttm |
Response - json (default)
Compact payload, no transcription, no per-speaker summary:
speaker is the normalized, zero-padded label clients should display. label preserves the raw backend-emitted ID for clients that maintain their own speaker dictionary.
Response - verbose_json
Adds per-speaker totals and (when the backend supports it and include_text=true) the per-segment transcript:
Response - rttm
NIST RTTM, the standard interchange format used by pyannote.metrics / dscore:
Returned as Content-Type: text/plain; charset=utf-8.
Quick start
First install a diarization-capable model from the gallery. The example below uses vibevoice-cpp-asr, which serves the vibevoice.cpp backend and returns speaker-labelled segments (and, optionally, a transcript):
The sections below show how to configure the two supported backends by hand when you want full control over the segmentation and embedding models.
Backend setup - sherpa-onnx (pure diarization)
Sherpa-onnx needs two ONNX models: pyannote segmentation and a speaker-embedding extractor. Place them under your LocalAI models directory and reference them from the YAML:
Both model: and diarize.embedding_model= are resolved relative to the LocalAI models directory.
Backend setup - vibevoice.cpp (diarization + ASR)
vibevoice.cpp’s ASR mode emits [{Start, End, Speaker, Content}] natively, so a single pass gives both diarization and transcription:
Pass include_text=true on the request to populate the text field on each diarization segment.
Backend setup - parakeet-cpp (Nemotron-3-Diarization)
Nemotron-3-Diarization is Sortformer, served standalone or paired with a Parakeet ASR model. Install parakeet-cpp-nemotron-3-diarization from the gallery for diarization only, or parakeet-cpp-nemotron-3-diarization-asr for the same model paired with parakeet-cpp-tdt_ctc-110m through the asr_model option:
Getting text on each segment needs both: an asr_model companion loaded on the model, and include_text=true on the request. With only one of the two, segments carry no text and no error is raised. Sortformer has a fixed speaker capacity and no clustering stage, so num_speakers, min_speakers, max_speakers and clustering_threshold are ignored (logged at debug); min_duration_on and min_duration_off are honored. Speaker labels are the decimal index the model assigned ("0", "1", …), or "unknown" when a segment has no diarized speaker.
Sortformer clusters on voice-like characteristics, not on “is this a human”. A loud non-speech sound with voice-like pitch and rhythm (a rooster crow, in one test clip) can come back as its own speaker segment alongside the real speakers. This is model behavior, not a bug in the LocalAI integration: treat an unexpected extra speaker as a hint the clip may contain a non-speech sound, and use Sound Classification to confirm what it is.
Notes
- Speaker identity across files: speaker IDs (
SPEAKER_00,SPEAKER_01, …) are local to each request. To track the same person across multiple recordings, combine/v1/audio/diarizationwith/v1/voice/embed(speaker embedding) and maintain your own embedding store. - Hints vs. forces:
num_speakersoverrides clustering when set;min_speakers/max_speakersare advisory and only honored by backends that expose a range hint. vibevoice.cpp and parakeet-cpp (Sortformer) ignore them - the model picks the count itself. - Sample rate: input is automatically converted to 16 kHz mono via ffmpeg before the backend sees it; sherpa-onnx pyannote-3.0 requires 16 kHz.
See also
- Sound Classification - tag non-speech sound events (alarms, glass breaking, baby cry) in a clip.