Fine-Tuning
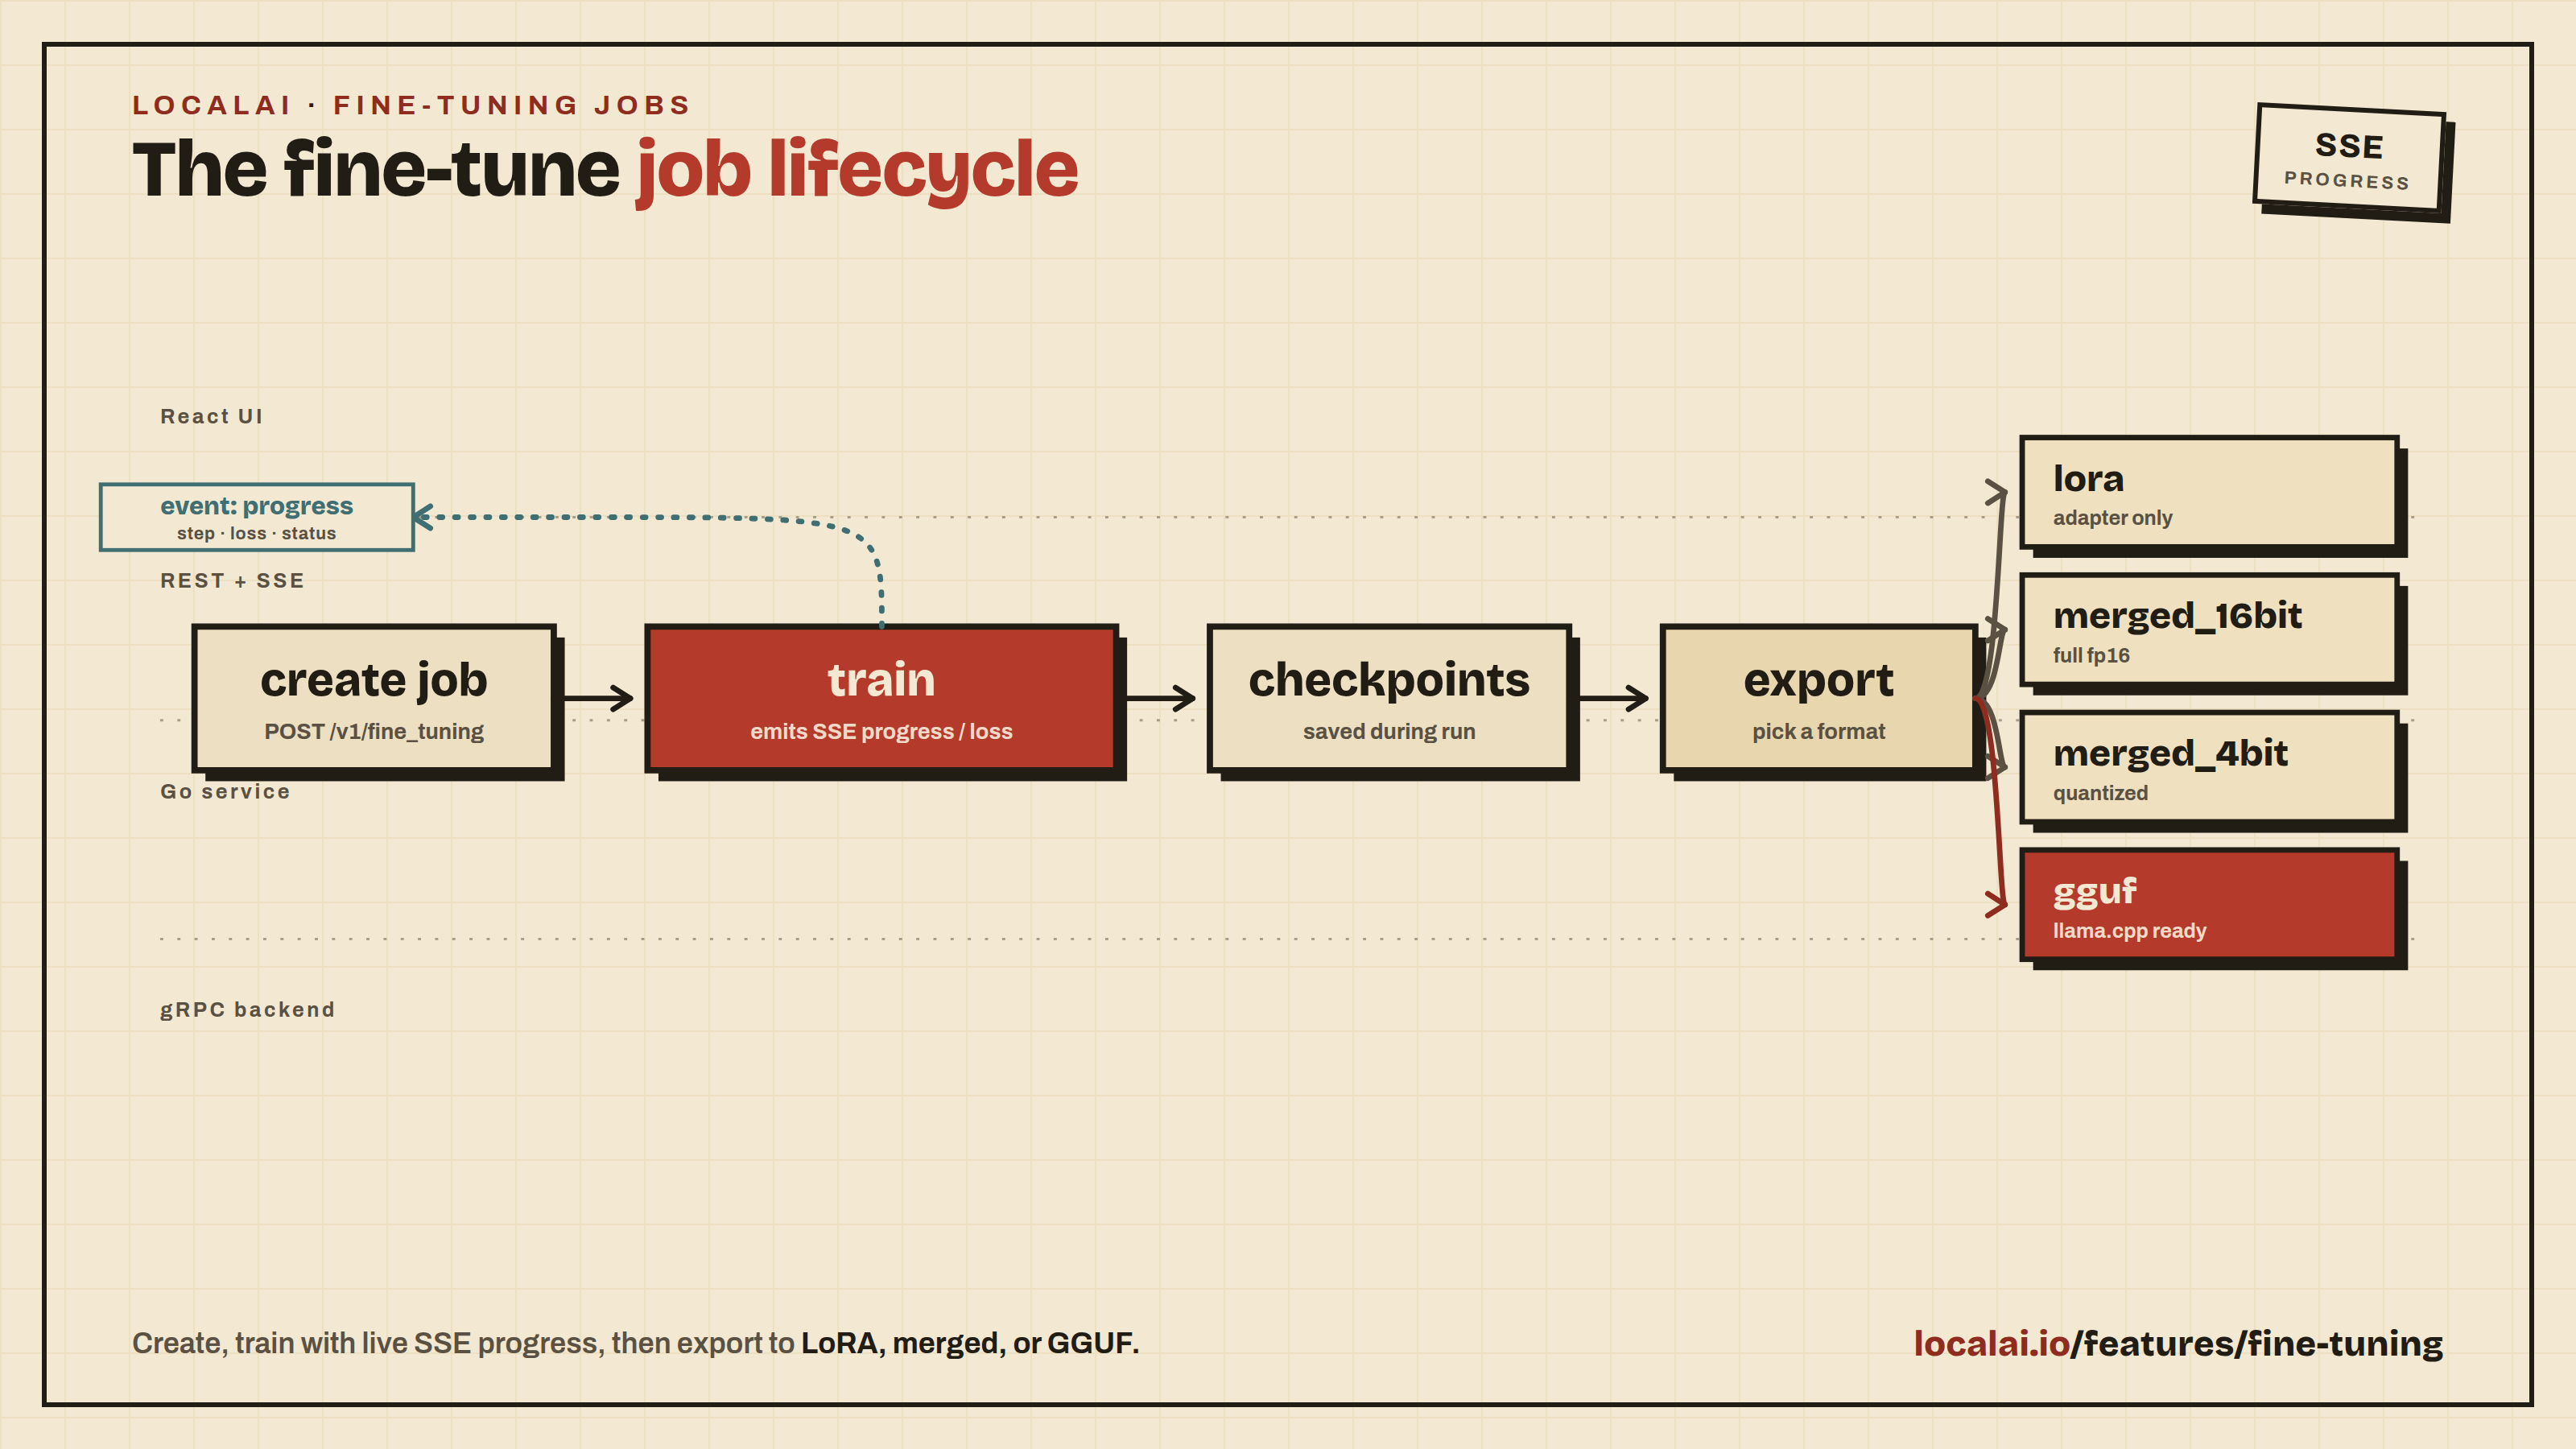
LocalAI supports fine-tuning LLMs directly through the API and Web UI. Fine-tuning is powered by pluggable backends that implement a generic gRPC interface, allowing support for different training frameworks and model types.
Supported Backends
| Backend | Domain | GPU Required | Training Methods | Adapter Types |
|---|---|---|---|---|
| trl | LLM fine-tuning | No (CPU or GPU) | SFT, DPO, GRPO, RLOO, Reward, KTO, ORPO | LoRA, Full |
Availability
Fine-tuning is always enabled. When authentication is enabled, fine-tuning is a per-user feature (default OFF). Admins can enable it for specific users via the user management API.
This feature is experimental and may change in future releases.
Quick Start
1. Start a fine-tuning job
2. Monitor progress (SSE stream)
3. List checkpoints
4. Export model
API Reference
Endpoints
| Method | Path | Description |
|---|---|---|
POST | /api/fine-tuning/jobs | Start a fine-tuning job |
GET | /api/fine-tuning/jobs | List all jobs |
GET | /api/fine-tuning/jobs/:id | Get job details |
DELETE | /api/fine-tuning/jobs/:id | Stop a running job |
GET | /api/fine-tuning/jobs/:id/progress | SSE progress stream |
GET | /api/fine-tuning/jobs/:id/checkpoints | List checkpoints |
POST | /api/fine-tuning/jobs/:id/export | Export model |
POST | /api/fine-tuning/datasets | Upload dataset file |
Job Request Fields
| Field | Type | Description |
|---|---|---|
model | string | HuggingFace model ID or local path (required) |
backend | string | Backend name (default: trl) |
training_method | string | sft, dpo, grpo, rloo, reward, kto, orpo |
training_type | string | lora or full |
dataset_source | string | HuggingFace dataset ID or local file path (required) |
adapter_rank | int | LoRA rank (default: 16) |
adapter_alpha | int | LoRA alpha (default: 16) |
num_epochs | int | Number of training epochs (default: 3) |
batch_size | int | Per-device batch size (default: 2) |
learning_rate | float | Learning rate (default: 2e-4) |
gradient_accumulation_steps | int | Gradient accumulation (default: 4) |
warmup_steps | int | Warmup steps (default: 5) |
optimizer | string | adamw_torch, adamw_8bit, sgd, adafactor, prodigy |
extra_options | map | Backend-specific options (see below) |
Backend-Specific Options (extra_options)
TRL
| Key | Description | Default |
|---|---|---|
max_seq_length | Maximum sequence length | 512 |
packing | Enable sequence packing | false |
trust_remote_code | Trust remote code in model | false |
load_in_4bit | Enable 4-bit quantization (GPU only) | false |
DPO-specific (training_method=dpo)
| Key | Description | Default |
|---|---|---|
beta | KL penalty coefficient | 0.1 |
loss_type | Loss type: sigmoid, hinge, ipo | sigmoid |
max_length | Maximum sequence length | 512 |
GRPO-specific (training_method=grpo)
| Key | Description | Default |
|---|---|---|
num_generations | Number of generations per prompt | 4 |
max_completion_length | Max completion token length | 256 |
GRPO Reward Functions
GRPO training requires reward functions to evaluate model completions. Specify them via the reward_functions field (a typed array) or via extra_options["reward_funcs"] (a JSON string).
Built-in Reward Functions
| Name | Description | Parameters |
|---|---|---|
format_reward | Checks <think>...</think> then answer format (1.0/0.0) | - |
reasoning_accuracy_reward | Extracts <answer> content, compares to dataset’s answer column | - |
length_reward | Score based on proximity to target length [0, 1] | target_length (default: 200) |
xml_tag_reward | Scores properly opened/closed <think> and <answer> tags | - |
no_repetition_reward | Penalizes n-gram repetition [0, 1] | - |
code_execution_reward | Checks Python code block syntax validity (1.0/0.0) | - |
Inline Custom Reward Functions
You can provide custom reward function code as a Python function body. The function receives completions (list of strings) and **kwargs, and must return list[float].
Inline reward code executes arbitrary Python and is disabled by default.
Inline code is compiled and run in the backend process. The restricted-builtins allowlist is not a security sandbox — trivial expressions can escape it to reach the host (arbitrary code execution). Because the fine-tuning endpoint is unauthenticated by default, inline reward functions are refused unless the operator explicitly opts in by setting LOCALAI_TRL_ALLOW_INLINE_REWARD=true on the backend.
Only enable it on a trusted, access-controlled instance where every caller of the fine-tuning API is authorized to run code on the host. Otherwise use the builtin reward functions above.
The function is given the reduced builtin set (len, int, float, str, list, dict, range, enumerate, zip, map, filter, sorted, min, max, sum, abs, round, any, all, isinstance, print) plus the re, math, json, and string modules, and is compiled and validated at job start (fail-fast on syntax errors). Treat these as ergonomics, not as an isolation boundary.
Example API Request
Export Formats
| Format | Description | Notes |
|---|---|---|
lora | LoRA adapter files | Smallest, requires base model |
merged_16bit | Full model in 16-bit | Large but standalone |
merged_4bit | Full model in 4-bit | Smaller, standalone |
gguf | GGUF format | For llama.cpp, requires quantization_method |
GGUF Quantization Methods
q4_k_m, q5_k_m, q8_0, f16, q4_0, q5_0
Web UI
Build → Fine-Tune is one page that follows the job from set-up to result. A line at the top shows where you are: set up, check, run, result.
- Set up - Choose the base model, the dataset (a Hugging Face id or an uploaded file), the kind of training (an adapter, or the full model) and the epochs, batch size and learning rate. Method, backend, adapter settings, optimizer, evaluation, reward functions (GRPO) and extra options are under More options.
- Check before you start - A list of what is known before the job starts, redrawn as you change the form: whether the model and dataset are set, whether a fine-tuning backend is installed, how much GPU memory (or RAM, when there is no GPU) is free, how much space is free on the models disk, and whether a token is set. LocalAI does not estimate how much memory a job needs or how long it takes, because the server cannot know that before the job starts, so the page says so. A missing model or dataset blocks the start. A warning, such as a missing backend or no GPU, does not.
- Run - Percent, step, epoch, the server’s time estimate and tokens per second, the stages the job passes through, a chart of loss (with the evaluation loss as hollow dots), learning rate and gradient norm, and a log of what the job reported since the page opened. Stop asks whether to keep a checkpoint.
- Result - A failed job shows the server’s message. When the message says memory ran out, the page offers two changes (a batch size of 1 and gradient checkpointing) that are applied to a copy of the setup and start nothing until you press Start. A finished job lists its checkpoints and exports the result as a model, then links to a chat with it and to Models.
Earlier jobs are listed below the form. Reuse puts a job’s setup back in the form.
A user needs the fine-tuning permission. Without it, the page says the account cannot fine-tune and who can change that.
Dataset Formats
Datasets should follow standard HuggingFace formats:
- SFT: Alpaca format (
instruction,input,outputfields) or ChatML/ShareGPT - DPO: Preference pairs (
prompt,chosen,rejectedfields) - GRPO: Prompts with reward signals
Supported file formats: .json, .jsonl, .csv
Architecture
Fine-tuning uses the same gRPC backend architecture as inference:
- Proto layer:
FineTuneRequest,FineTuneProgress(streaming),StopFineTune,ListCheckpoints,ExportModel - Python backends: Each backend implements the gRPC interface with its specific training framework
- Go service: Manages job lifecycle, routes API requests to backends
- REST API: HTTP endpoints with SSE progress streaming
- React UI: Configuration form, real-time training monitor, export panel