LocalAI runs models of many kinds. Each page here shows what a kind of model does, how to call it and which backends serve it. The API features are on by default for new users.
Overview The chat endpoint supports the grammar parameter, which allows users to specify a grammar in Backus-Naur Form (BNF). This feature enables the Large Language Model (LLM) to generate outputs adhering to a user-defined schema, such as JSON, YAML, or any other format that can be defined using BNF. For more details about BNF, see Backus-Naur Form on Wikipedia.
Reasoning models can “think” before they answer. When such a model also calls a tool, the useful behaviour is for the thinking and the tool call to travel together, and for that thinking to survive the tool-result round trip. LocalAI calls this interleaved thinking: a single assistant turn carries both reasoning and tool_calls, and the client hands the reasoning back on the next turn so the model’s chain of thought is not lost when the tool result is appended.
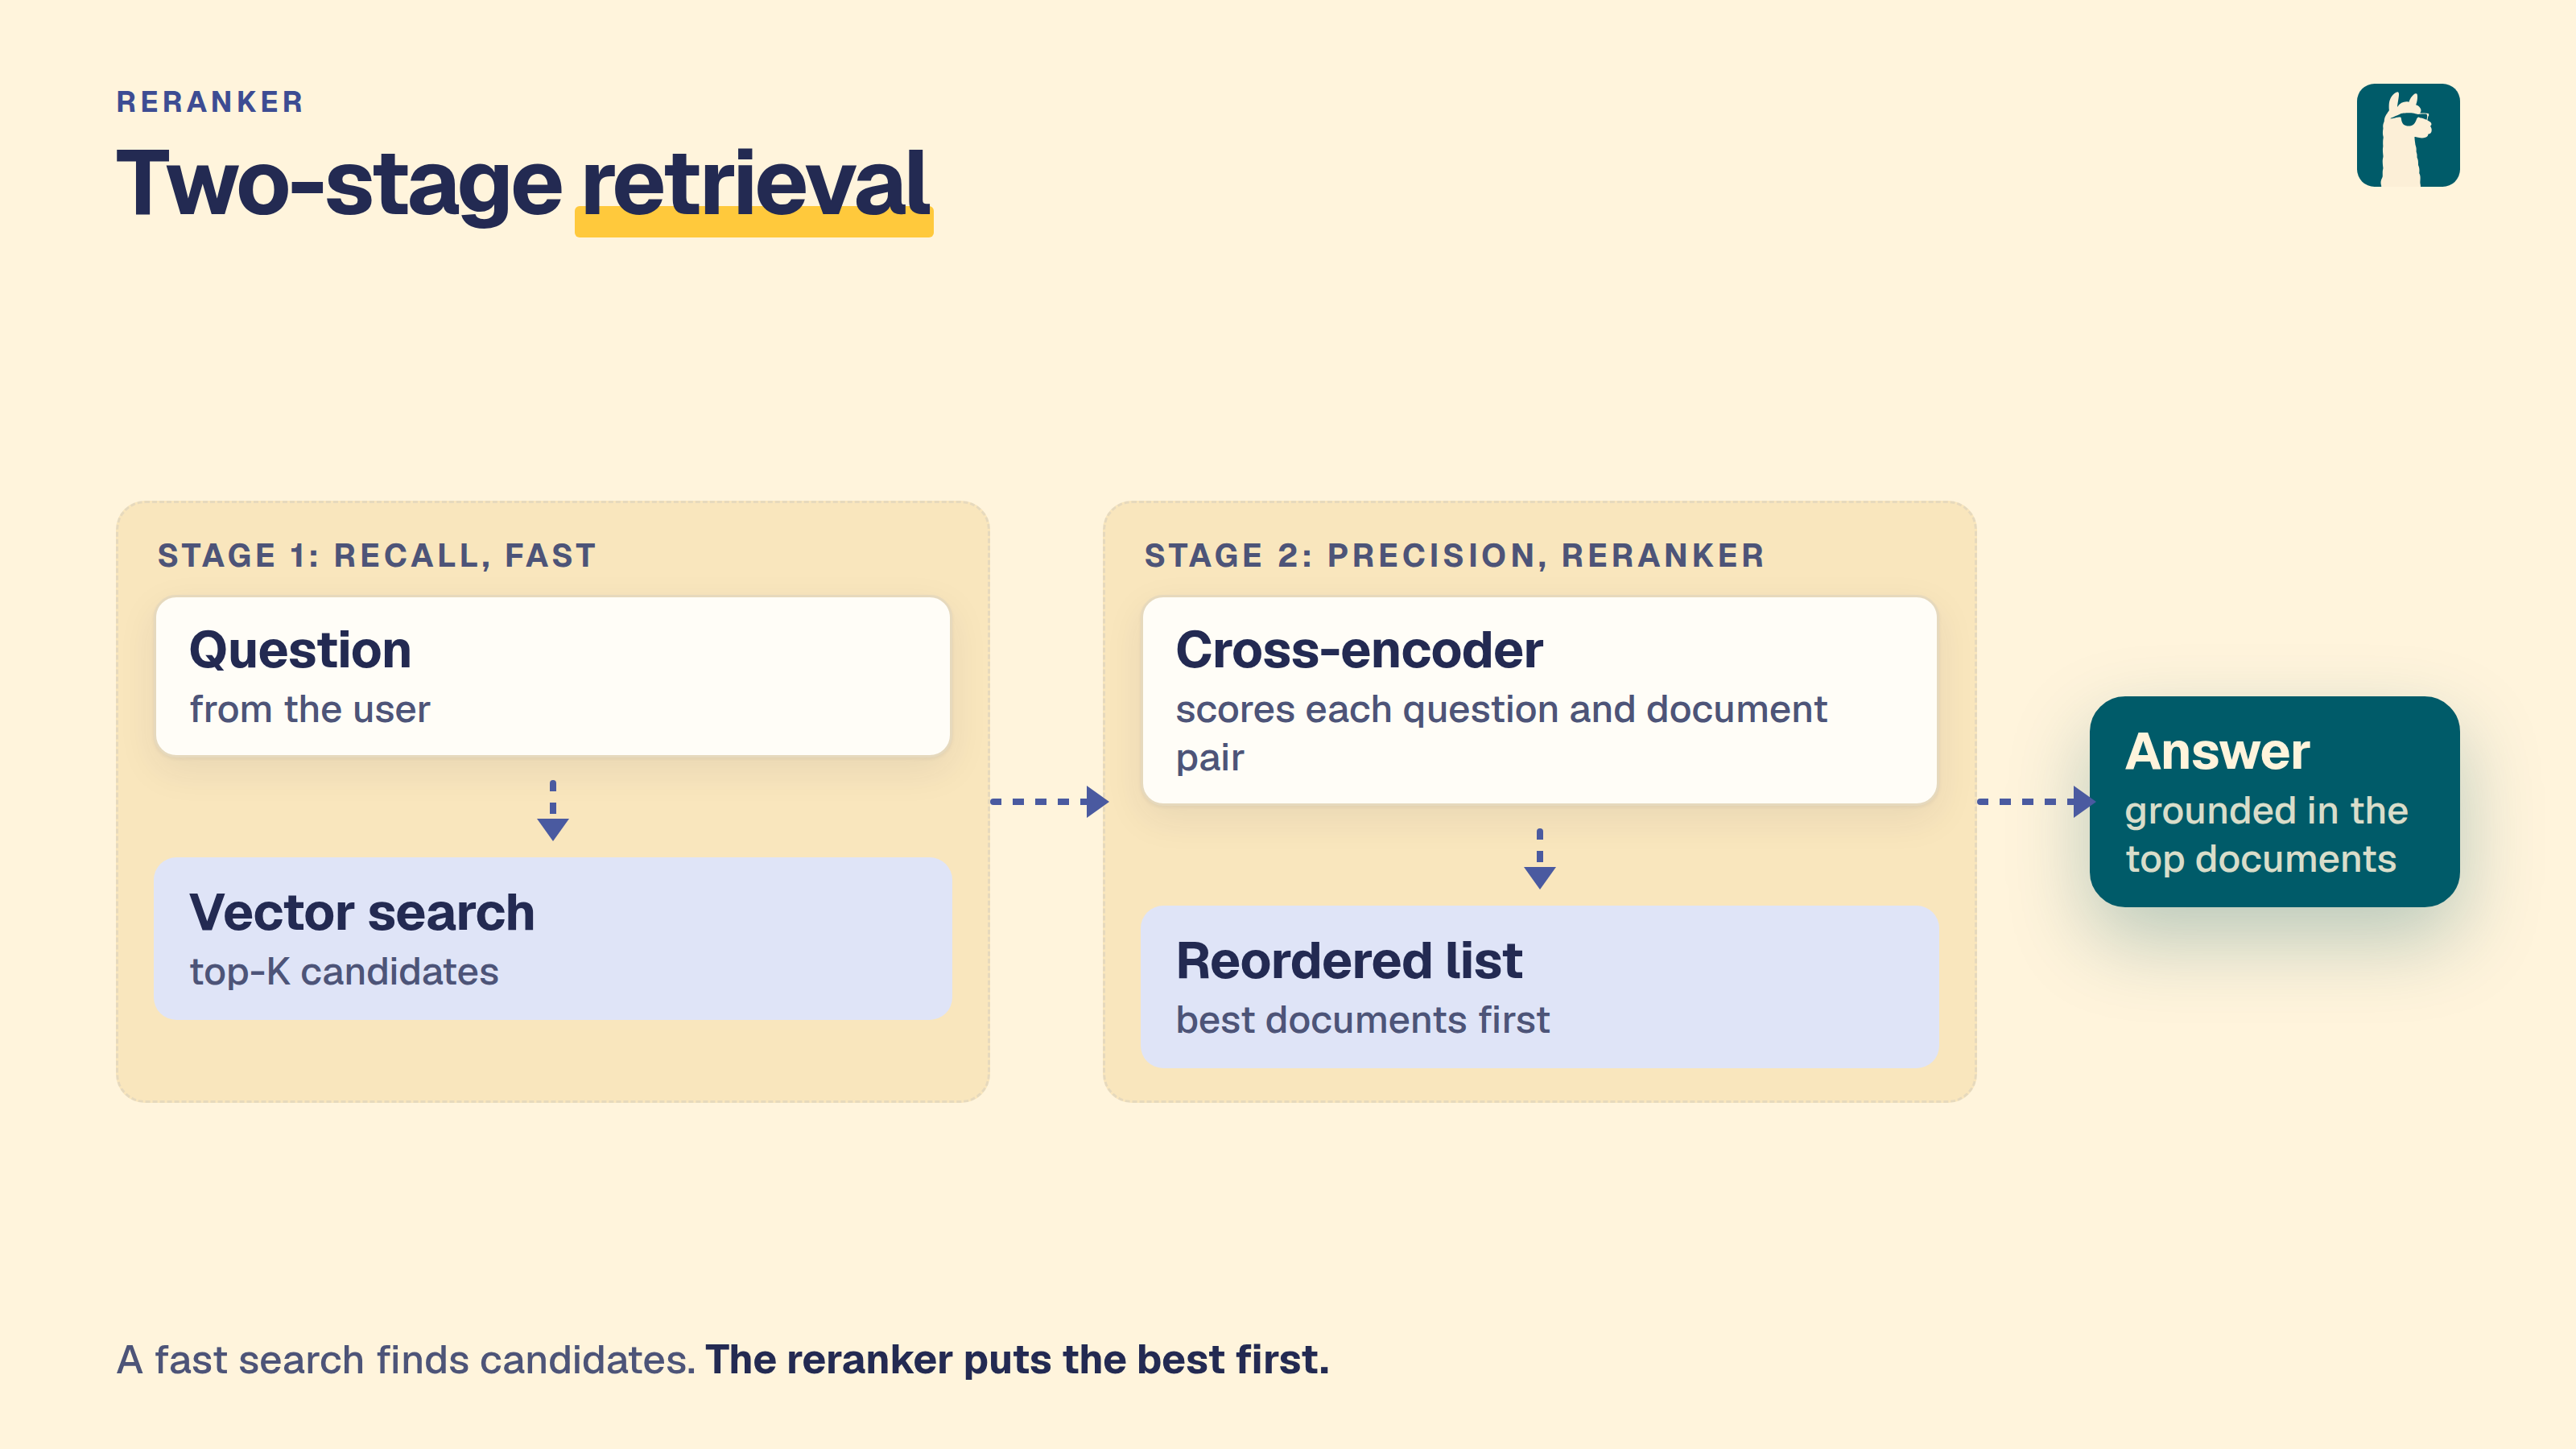
A reranking model, often referred to as a cross-encoder, is a core component in the two-stage retrieval systems used in information retrieval and natural language processing tasks. Given a query and a set of documents, it will output similarity scores.
We can use then the score to reorder the documents by relevance in our RAG system to increase its overall accuracy and filter out non-relevant results.
LocalAI exposes an OpenAI-compatible text moderation endpoint at POST /v1/moderations. It uses a local text-generation model with a constrained JSON grammar, so no separate moderation service or cloud API is required.
curl http://localhost:8080/v1/moderations \ -H "Content-Type: application/json" \ -d '{ "model": "your-instruct-model", "input": "Text to classify" }' input may be one string or an array of strings. The response contains one result per input with flagged, categories, category_scores, and category_applied_input_types fields. The category names match the OpenAI moderation API, including harassment, hate, illicit activity, self-harm, sexual content, and violence categories.
LocalAI forecasts numeric time series with timestral.cpp, a C++/ggml port of Mistral’s Timestral models. You send one or more series, with optional covariates, to POST /v1/forecast and get quantile trajectories for the next steps.
A forecast model is not a chat model. It has its own usecase, forecast, and does not appear in the chat model picker. It shows in the gallery filter and in the /v1/models capability list.
Licence. The Timestral weights use Mistral’s Modified MIT licence. You may not use them if the global consolidated monthly revenue of your company (or your employer) exceeded USD 20 million in the preceding month, unless you get a commercial licence from Mistral AI. The restriction covers derivatives, so it also applies to the GGUF conversions in the gallery. Each gallery entry installs the licence text next to the weights. The timestral.cpp code is MIT.
Use local-ai benchmark to compare text inference through a running LocalAI server. Install and configure the models first. The command sends sequential, non-streaming requests to /v1/chat/completions and reports full request latency and end-to-end completion tokens per second.
Pass one or more configured model names. To compare backends, configure separate model aliases with the desired backend, then pass those aliases. Backend names alone are not model names. The command does not install, discover, or unload models; the server’s normal loading and eviction settings still apply.
Subsections of Text and retrieval
Text generation
LocalAI generates text with the llama-cpp backend and with other backends, such as vllm and transformers. See also the Model compatibility for an up-to-date list of the supported model families.
Note:
You can also specify the model name as part of the OpenAI token.
If only one model is available, the API will use it for all the requests.
For example, to generate a chat completion, you can send a POST request to the /v1/chat/completions endpoint with the instruction as the request body:
curl http://localhost:8080/v1/chat/completions -H "Content-Type: application/json" -d '{
  "model": "ggml-koala-7b-model-q4_0-r2.bin",
  "messages": [{"role": "user", "content": "Say this is a test!"}],
  "temperature": 0.7
}'
Available additional parameters: top_p, top_k, max_tokens
When a request omits max_tokens, the vLLM and SGLang backends do not cap generation at 200 tokens. Generation is bounded only by the context window of the model.
Reasoning models return their thinking in the reasoning field. When a model reasons and calls a tool in the same turn, see Interleaved Thinking with Tool Calls.
When stream: true is set and the llama.cpp backend fails before the first chunk, for example because the prompt exceeds the context size, the request fails with an HTTP error. The error message is not streamed as assistant content. An error after streaming has started is reported inside the stream.
To generate a completion, you can send a POST request to the /v1/completions endpoint with the instruction as per the request body:
curl http://localhost:8080/v1/completions -H "Content-Type: application/json" -d '{
  "model": "ggml-koala-7b-model-q4_0-r2.bin",
  "prompt": "A long time ago in a galaxy far, far away",
  "temperature": 0.7
}'
Available additional parameters: top_p, top_k, max_tokens
List models
You can list all the models available with:
curl http://localhost:8080/v1/models
Anthropic Messages API
LocalAI supports the Anthropic Messages API, which is compatible with Claude clients. This endpoint provides a structured way to send messages and receive responses, with support for tools, streaming, and multimodal content.
curl http://localhost:8080/v1/messages \
-H "Content-Type: application/json"\
-H "anthropic-version: 2023-06-01"\
-d '{
"model": "ggml-koala-7b-model-q4_0-r2.bin",
"max_tokens": 1024,
"messages": [
{"role": "user", "content": "Say this is a test!"}
]
}'
Request Parameters
Parameter
Type
Required
Description
model
string
Yes
The model identifier
messages
array
Yes
Array of message objects with role and content
max_tokens
integer
Yes
Maximum number of tokens to generate (must be > 0)
system
string
No
System message to set the assistant’s behavior
temperature
float
No
Sampling temperature (0.0 to 1.0)
top_p
float
No
Nucleus sampling parameter
top_k
integer
No
Top-k sampling parameter
stop_sequences
array
No
Array of strings that will stop generation
stream
boolean
No
Enable streaming responses
tools
array
No
Array of tool definitions for function calling
tool_choice
object
No
Tool choice strategy: {"type": "auto"}, {"type": "any"}, {"type": "none"}, or {"type": "tool", "name": "..."}. The bare strings “auto”, “any” and “none” are accepted too
metadata
object
No
Per-request metadata passed to the backend (e.g., {"enable_thinking": "true"})
Message Format
Messages can contain text or structured content blocks:
Streaming responses use Server-Sent Events (SSE) format with event types: message_start, content_block_start, content_block_delta, content_block_stop, message_delta, and message_stop.
Response Format
{"id":"msg_abc123","type":"message","role":"assistant","content":[{"type":"text","text":"This is a test!"}],"model":"ggml-koala-7b-model-q4_0-r2.bin","stop_reason":"end_turn","usage":{"input_tokens":10,"output_tokens":5}}
stop_reason is end_turn, tool_use, or max_tokens when the reply used up max_tokens.
Open Responses API
LocalAI supports the Open Responses API specification, which provides a standardized interface for AI model interactions with support for background processing, streaming, tool calling, and advanced features like reasoning.
curl http://localhost:8080/v1/responses \
-H "Content-Type: application/json"\
-d '{
"model": "ggml-koala-7b-model-q4_0-r2.bin",
"input": "Say this is a test!",
"max_output_tokens": 1024
}'
Reuse assistant messages
When you manage conversation history in your client, append assistant messages from a response’s output array to the next request’s input.
Keep their content type as output_text. Use input_text for new user messages.
Include earlier conversation items that the model still needs.
For example, submit this body to POST /v1/responses:
{"model":"ggml-koala-7b-model-q4_0-r2.bin","input":[{"type":"message","role":"user","content":[{"type":"input_text","text":"What is the capital of France?"}]},{"type":"message","role":"assistant","content":[{"type":"output_text","text":"Paris is the capital of France."}]},{"type":"message","role":"user","content":[{"type":"input_text","text":"Which river flows through it?"}]}]}
WebSocket Responses
Connect to ws://localhost:8080/v1/responses (or wss:// when TLS is
enabled) and send response.create messages over the WebSocket. Only one
response may be in progress on a connection. Wait for response.completed or
response.failed for the active response before sending the next
response.create. An error that rejects an invalid or additional
response.create applies only to that rejected message; it does not terminate
a response that is already in progress.
Set the WebSocket-only generate field to false to prepare a request without
running inference:
{"type":"response.create","model":"ggml-koala-7b-model-q4_0-r2.bin","generate":false,"store":false,"input":"Say this is a test!"}
LocalAI emits response.created followed by response.completed with no
generated output. The completed response still has an ID that can continue the
prepared request:
Response IDs created with store: false are available only on the WebSocket
connection that created them and are removed when that connection closes. A
previous_response_id chain can contain multiple responses; LocalAI replays the
complete conversation from the oldest response through the referenced response
before appending the new input. The replay includes server-side MCP tool calls
and their results, which are stored as function_call and
function_call_output output items. Keep store: false for every descendant of a
connection-local response. LocalAI rejects a store: true response that depends
on connection-local history because the resulting stored chain would be broken
after the WebSocket closes.
After delivery, LocalAI discards buffered stream events for store: false
responses but retains their request and final response for continuation. A
connection admits at most 128 local responses and accepts a new local request
only while its current serialized history plus that request is at most 64 MiB.
When either admission threshold is reached, LocalAI returns
connection_store_limit_reached; reconnect to start a new local history. With
authentication enabled, globally stored response IDs can be continued only by
the identity that created them.
Request Parameters
Parameter
Type
Required
Description
model
string
Yes
The model identifier
input
string/array
Yes
Input text or array of input items
max_output_tokens
integer
No
Maximum number of tokens to generate
temperature
float
No
Sampling temperature
top_p
float
No
Nucleus sampling parameter
instructions
string
No
System instructions
tools
array
No
Array of tool definitions
tool_choice
string/object
No
Tool choice: “auto”, “required”, “none”, or specific tool
stream
boolean
No
Enable streaming responses
background
boolean
No
Run request in background (returns immediately)
store
boolean
No
Whether to store the response
reasoning
object
No
Reasoning configuration with effort and summary
parallel_tool_calls
boolean
No
Allow parallel tool calls
max_tool_calls
integer
No
Maximum number of tool calls
presence_penalty
float
No
Presence penalty (-2.0 to 2.0)
frequency_penalty
float
No
Frequency penalty (-2.0 to 2.0)
top_logprobs
integer
No
Number of top logprobs to return
truncation
string
No
Truncation mode: “auto” or “disabled”
text_format
object
No
Text format configuration
metadata
object
No
Custom metadata
Input Format
Input can be a simple string or an array of structured items:
Set "stream": true to receive Server-Sent Events. Each response.output_item.added event assigns an output_index to an item.
Use that index and the item ID to associate later deltas and completion events with the same item.
If a request without explicit tools produces reasoning, the stream uses separate items for reasoning and answer text.
Each item keeps its original index throughout the stream.
The response.completed event includes both items in the same index order, followed by any automatically parsed tool calls.
Background Processing
Run requests in the background for long-running tasks:
curl http://localhost:8080/v1/responses \
-H "Content-Type: application/json"\
-d '{
"model": "ggml-koala-7b-model-q4_0-r2.bin",
"input": "Generate a long story",
"max_output_tokens": 4096,
"background": true
}'
The response will include a response ID that can be used to poll for completion:
Use the GET endpoint to retrieve background responses:
# Get response by IDcurl http://localhost:8080/v1/responses/resp_abc123
# Resume streaming with query parameterscurl "http://localhost:8080/v1/responses/resp_abc123?stream=true&starting_after=10"
Canceling Background Responses
Cancel a background response that’s still in progress:
curl -X POST http://localhost:8080/v1/responses/resp_abc123/cancel
Multiple Replicas (Distributed Mode)
In distributed mode LocalAI replicates response metadata across frontend
replicas, so retrieval, previous_response_id chaining and cancellation work
regardless of which replica the load balancer picks:
GET /v1/responses/{id} returns the response from any replica.
POST /v1/responses/{id}/cancel is delegated over NATS to the replica that is
actually generating, so generation really stops. If that replica is gone, the
response is reported as cancelled without blocking.
Streaming resume (?stream=true&starting_after=N) works on any replica,
because the event buffer is read from the database (see Durable Storage
below). Without a database (it always exists in distributed mode, so this only
concerns a build that cannot reach it) the buffer is in the memory of the
replica that generates, and a resume that reaches another replica returns
HTTP 409 naming the owning replica.
State mode (see the distributed-state rules): the response metadata is
shared state, a SyncedMap with a database Store. The table is the source
of truth, a replica that starts later loads the newest rows (up to 10000), and
changes reach the other replicas as deltas over NATS. The events are not sent
over NATS: every replica reads them from the table. The generation itself, and
its cancel function, live on one replica, the owner of the response; a cancel
reaches it over NATS and through the cancel_requested flag.
Durable Storage
When LocalAI has a database (authentication enabled, or distributed mode),
stored responses and the events of a background run are kept in two tables,
open_responses and open_response_events. Without a database the store stays
in memory, as before, and ends with the process.
With the tables:
A response and its event buffer outlive a restart. GET /v1/responses/{id},
previous_response_id chaining and ?stream=true&starting_after=N read the
tables, so any replica serves them and they work after a restart.
The owner writes events in batches: at once for any event that is not a
.delta event, and for deltas every 250 ms or 64 events. If the process dies,
the deltas of the last 250 ms are lost.
The buffer keeps the same caps as the memory store (8192 events and 64 MiB per
response, oldest first). A resume below the oldest kept event returns HTTP 409
(ErrOffsetLost).
Every read still checks the owner of the response: a caller who did not create
it gets 404. An item_reference finds only an item of a response the caller
created; the item of another user’s response is “not found”.
Rows expire after OPEN_RESPONSES_STORE_TTL. With the TTL at 0 a database
store applies a default of 7 days, because a table does not end with the
process.
A running background response holds a lease in its row, which its owner renews
every 15 seconds (the lease lasts 45 seconds). When the owner dies, for example
because the pod is replaced, the lease runs out and the response is ended as
failed with the error code server_restarted. A final response.failed event
is added, so a client that resumes the stream gets every kept event and then
the end. LocalAI does not run the request again: a generation cannot continue
from a cut point, and tools may have had effects. Send the request again, with
previous_response_id to keep the context. A standalone server ends the runs a
previous process left when it starts. In distributed mode one frontend at a time
runs the sweep.
POST /v1/responses/{id}/cancel sets a cancel_requested flag in the row. The
owner checks it on every lease renewal, so a cancel works even if the bus message
is lost. If the owner died before it could stop, the response ends as cancelled.
Tool Calling
Open Responses API supports function calling with tools:
curl http://localhost:8080/v1/responses \
-H "Content-Type: application/json"\
-d '{
"model": "ggml-koala-7b-model-q4_0-r2.bin",
"input": "What is the weather in San Francisco?",
"tools": [
{
"type": "function",
"name": "get_weather",
"description": "Get the current weather",
"parameters": {
"type": "object",
"properties": {
"location": {
"type": "string",
"description": "The city and state"
}
},
"required": ["location"]
}
}
],
"tool_choice": "auto",
"max_output_tokens": 1024
}'
For streaming requests with JSON tool output, LocalAI waits for the complete JSON
object before emitting a completed function_call item. Arguments can span
multiple tokens. Read the arguments from the response.output_item.done event
before executing the tool.
Reasoning Configuration
Configure reasoning effort and summary style:
curl http://localhost:8080/v1/responses \
-H "Content-Type: application/json"\
-d '{
"model": "ggml-koala-7b-model-q4_0-r2.bin",
"input": "Solve this complex problem step by step",
"reasoning": {
"effort": "high",
"summary": "detailed"
},
"max_output_tokens": 2048
}'
Response Format
{"id":"resp_abc123","object":"response","created_at":1234567890,"completed_at":1234567895,"status":"completed","model":"ggml-koala-7b-model-q4_0-r2.bin","output":[{"type":"message","id":"msg_001","role":"assistant","content":[{"type":"output_text","text":"This is a test!","annotations":[],"logprobs":[]}],"status":"completed"}],"error":null,"incomplete_details":null,"temperature":0.7,"top_p":1.0,"presence_penalty":0.0,"frequency_penalty":0.0,"usage":{"input_tokens":10,"output_tokens":5,"total_tokens":15,"input_tokens_details":{"cached_tokens":0},"output_tokens_details":{"reasoning_tokens":0}}}
Backends
RWKV
RWKV support is available through llama.cpp (see below)
llama.cpp
llama.cpp is a popular port of Facebook’s LLaMA model in C/C++.
Note
The ggml file format has been deprecated. If you are using ggml models and you are configuring your model with a YAML file, specify, use a LocalAI version older than v2.25.0. For gguf models, use the llama backend. The go backend is deprecated as well but still available as go-llama.
Features
The llama.cpp model supports the following features:
Prompt templates are useful for models that are fine-tuned towards a specific prompt.
With the llama.cpp backend, streaming and non-streaming chat requests preserve
the template’s grammar, stop strings, and message boundaries.
Automatic setup
LocalAI supports model galleries which are indexes of models. For instance, the huggingface gallery contains a large curated index of models from the huggingface model hub for ggml or gguf models.
For instance, if you have the galleries enabled and LocalAI already running, you can just start chatting with models in huggingface by running:
curl http://localhost:8080/v1/chat/completions -H "Content-Type: application/json" -d '{
     "model": "TheBloke/WizardLM-13B-V1.2-GGML/wizardlm-13b-v1.2.ggmlv3.q2_K.bin",
     "messages": [{"role": "user", "content": "Say this is a test!"}],
     "temperature": 0.1
   }'
LocalAI will automatically download and configure the model in the model directory.
Models can be also preloaded or downloaded on demand. To learn about model galleries, check out the model gallery documentation.
YAML configuration
To use the llama.cpp backend, specify llama-cpp as the backend in the YAML file:
name:llamabackend:llama-cppparameters:# Relative to the models pathmodel:file.gguf
Backend Options
The llama.cpp backend supports additional configuration options that can be specified in the options field of your model YAML configuration. These options allow fine-tuning of the backend behavior:
Option
Type
Description
Example
use_jinja or jinja
boolean
Enable Jinja2 template processing for chat templates. When enabled, the backend uses Jinja2-based chat templates from the model for formatting messages.
use_jinja:true
context_shift
boolean
Enable context shifting, which allows the model to dynamically adjust context window usage.
context_shift:true
cache_ram
integer
Size budget in MiB for the server-side prompt cache (a host-RAM store of idle slot KV states that’s reloaded on a prompt-prefix hit, see upstream PR #16391). Default: 8192 MiB (llama.cpp default). -1 removes the limit. 0 disables the prompt cache entirely. Together with kv_unified and cache_idle_slots this is what makes a repeated system prompt skip prefill on subsequent calls.
cache_ram:4096
slot_save_path
string
Directory where the slot save and restore API writes and reads prompt-cache files. Save and restore are off unless this is set. LocalAI creates the directory with mode 0700 if it is missing. See Saving and restoring a prompt cache.
slot_save_path:/var/lib/localai/slots
parallel or n_parallel
integer
Enable parallel request processing. When set to a value greater than 1, enables continuous batching for handling multiple requests concurrently.
parallel:4
grpc_servers or rpc_servers
string
Comma-separated list of gRPC server addresses for distributed inference. Allows distributing workload across multiple llama.cpp workers.
grpc_servers:localhost:50051,localhost:50052
fit_params or fit
boolean
Enable auto-adjustment of model/context parameters to fit available device memory. Default: true.
fit_params:true
fit_params_target or fit_target
integer
Target margin per device in MiB when using fit_params. Default: 1024 (1GB).
fit_target:2048
fit_params_min_ctx or fit_ctx
integer
Minimum context size that can be set by fit_params. Default: 4096.
fit_ctx:2048
n_cpu_ffn
integer
Keep the dense FFN weights of the first N layers on the CPU (upstream --n-cpu-ffn), the counterpart of n_cpu_moe for dense models. Default: 0.
n_cpu_ffn:12
yarn_orig_ctx
integer
Original context size of the model for YaRN scaling (upstream --yarn-orig-ctx). 0 uses the model’s training context size.
yarn_orig_ctx:32768
moe_cache_mib
integer
Size in MiB of a GPU cache for MoE expert weights that stay in host memory (upstream --moe-cache-mib). Off by default (0). It helps only when experts are in host memory, with cpu_moe, n_cpu_moe or a fit_params spill. The cache uses GPU memory, so lower gpu_layers or the fit result may change. Experimental upstream. A cache that is too small can thrash, because every token evicts its own experts. A rough starting point is about 10% of the total expert size.
moe_cache_mib:4096
moe_cache_cpu_share
float
Share of the MoE cache misses that the CPU computes from the host experts instead of uploading them to the GPU once the cache is full, from 0 to 1 (upstream --moe-cache-cpu-share). Default 0: every miss is uploaded. It applies only when the cache is on (moe_cache_mib > 0). Values outside 0 to 1 are ignored with a warning. The best value depends on the hardware. In the upstream tests a small cache did best with a high share and a large cache with a low one. Upstream ships scripts/moe-cache-tune.py, which wraps a plain llama-server command, to find both values.
moe_cache_cpu_share:0.5
n_cache_reuse or cache_reuse
integer
Minimum chunk size to attempt reusing from the cache via KV shifting. Default: 0 (disabled).
cache_reuse:256
slot_prompt_similarity or sps
float
How much the prompt of a request must match the prompt of a slot to use that slot. Default: 0.1. Set to 0 to disable.
sps:0.5
swa_full
boolean
Use full-size SWA (Sliding Window Attention) cache. Default: false.
swa_full:true
cont_batching or continuous_batching
boolean
Enable continuous batching for handling multiple sequences. Default: true.
cont_batching:true
check_tensors
boolean
Validate tensor data for invalid values during model loading. Default: false.
check_tensors:true
warmup
boolean
Enable warmup run after model loading. Default: true.
warmup:false
no_op_offload
boolean
Disable offloading host tensor operations to device. Default: false.
no_op_offload:true
device or devices
string
Select the llama.cpp backend devices to use. Repeat the option or pass a comma-separated list; unlisted devices are excluded. Use the names reported by llama-server --list-devices / --list-devices.
devices:CUDA1,CUDA2,CUDA3
kv_unified or unified_kv
boolean
Use a single unified KV buffer shared across all sequences. Default: true (LocalAI override; upstream defaults to false but auto-enables it when slot count is auto). Required for cache_idle_slots and scoring: without it the server force-disables idle-slot saving at init, and score-enabled models are rejected at load time.
kv_unified:false
kv_unified_per_slot
integer
Context limit per parallel slot (upstream --kv-unified-per-slot). When context_size is not set, the shared KV cache is sized to parallel times this value. Default: unset.
kv_unified_per_slot:8192
cache_idle_slots or idle_slots_cache
boolean
On a new task, save the previous slot’s KV state into the prompt cache (and clear the slot) so a later request with the same prefix can warm-load it. Default: true. Auto-disabled by the server if kv_unified=false or cache_ram=0.
cache_idle_slots:false
n_ctx_checkpoints or ctx_checkpoints
integer
Maximum number of context checkpoints per slot (used for partial-prefix recovery, e.g. SWA). Default: 32.
ctx_checkpoints:16
checkpoint_min_step or checkpoint_min_spacing (aliases: checkpoint_every_nt, checkpoint_every_n_tokens)
integer
Minimum spacing in tokens between context checkpoints. 0 disables the minimum-spacing gate. Default: 256. (Renamed upstream from checkpoint_every_nt; semantics shifted from a fixed cadence to a minimum spacing.)
checkpoint_min_step:1024
split_mode or sm
string
How to split the model across multiple GPUs: none (single GPU only), layer (default - split layers and KV across GPUs), row (split rows across GPUs), tensor (experimental tensor parallelism, requires flash_attention: true, manually set context_size, and a llama.cpp build that includes #19378; it historically also required KV-cache quantization to be disabled, but #23792 lifts that restriction so cache_type_k/cache_type_v quantization can be combined with tensor parallelism on builds that include it).
Note: The parallel option can also be set via the LLAMACPP_PARALLEL environment variable, and grpc_servers can be set via the LLAMACPP_GRPC_SERVERS environment variable. Options specified in the YAML file take precedence over environment variables.
An explicit parallel: 1 (or n_parallel: 1) in the model options takes precedence over LLAMACPP_PARALLEL, like any other value. The environment variable is only used when neither option is set; if it is missing or not a number, the backend uses one slot.
Hardware auto-tuning (and how to override it)
On a detected GPU, LocalAI fills a few performance-relevant defaults the model config leaves unset - a larger physical batch on NVIDIA Blackwell, and a VRAM-scaled parallel slot count for concurrent serving. Both are gated on per-device VRAM at the model’s context: when a large context already fills a single card (e.g. a 27B model with a 200k context across 2×16 GiB), the batch boost and the extra parallel slots are suppressed so they can’t tip the tighter GPU into CUDA out-of-memory.
Anything you set explicitly in the model YAML always wins, so to pin a value just set it (e.g. batch: 512 or options: ["parallel:1"]). The effective values are logged at INFO when a model loads (effective runtime tuning …). To turn the hardware auto-tuning off entirely and run llama.cpp’s stock behavior, set:
LOCALAI_DISABLE_HARDWARE_DEFAULTS=true
Server-side prompt cache (repeated system prompts)
Agents, coding assistants, and Anthropic/OpenAI-compatible CLIs typically resend the same large system prompt on every turn. The llama.cpp server can short-circuit prefill for the matching prefix by stashing idle slot KV states in host RAM and reloading them on a hit. Three settings interact:
Setting
Default
Role
cache_ram:N
8192 (llama.cpp default)
Allocates the host-side prompt cache. 0 disables it.
kv_unified:true
true
Single unified KV buffer (prerequisite for idle-slot saving).
cache_idle_slots:true
true
Persists the idle slot’s KV into the prompt cache on task switch.
All three are on by default since LocalAI v4.3, so the prompt cache works out of the box for the common single-slot setup. If you’re on an older release, or you’ve explicitly disabled one of them, add the following to recover the behaviour:
options:- cache_ram:4096 # or -1 for no limit- kv_unified:true- cache_idle_slots:true
Set cache_ram:0 to opt out of the prompt cache entirely (saves host RAM at the cost of re-prefilling repeated prompts).
cache_ram:-1 removes the limit. With idle-slot saving on, every distinct prompt then leaves its slot state in host RAM, so a workload with many different prompts (classification, ingestion) grows the backend by roughly the KV size of each prompt until the host runs out of memory.
Saving and restoring a prompt cache
The server-side prompt cache lives in RAM and is lost when the model unloads. To keep the prompt state of one slot on disk, set slot_save_path and use the slot API. A typical use is a voice assistant with a long system prompt: save the state once, then restore it when the wake word fires, so the first request does not wait for prefill.
options:- slot_save_path:/var/lib/localai/slots
Both calls need an admin API key when authentication is on. Without slot_save_path they return 400.
The server chooses the name of every saved file. A save returns an id, and a restore takes that id. A client cannot pick a file name or a path.
# Save slot 0 of the model. The reply contains the id.curl http://localhost:8080/v1/slots/save \
-H "Content-Type: application/json"\
-d '{"model": "my-model", "slot": 0}'# Load that state back into slot 0curl http://localhost:8080/v1/slots/restore \
-H "Content-Type: application/json"\
-d '{"model": "my-model", "slot": 0, "id": "0123456789abcdef0123456789abcdef"}'
Field
Description
model
Name of a llama-cpp model.
slot
Slot id. Default 0. With parallel:N the ids are 0 to N-1.
id
Restore only. The id that a save returned for this model: 32 lowercase hex characters. Do not send it on save.
The save reply gives the id, the slot, the number of tokens and bytes, and the time taken in duration_ms. The message field lists the IDs of any older saves that were deleted to make room. The restore reply has the same fields. Neither reply contains a path on the host.
Keep these points in mind:
A client cannot choose names. The backend creates a directory for each model under slot_save_path (mode 0700) and writes a manifest.json in it. A restore works only for an id in the manifest of that model. Any other id returns 404 with no saved state with this id for this model.
The backend keeps at most 32 saves for each model. When a save would go over that, it deletes the oldest one and lists its id in message. A save larger than 8 GiB is deleted and fails.
A restore also checks that the file is a plain file and has the size that was recorded at save time. A file that was replaced or cut short is refused.
Keep slot_save_path private to the user that runs LocalAI. LocalAI creates it with mode 0700 when it is missing, and writes a warning to the log when an existing directory is open to other users. The checks above cannot stop a local user who can write to the directory.
A saved state is only as fresh as its save. To change the cached prompt, save again and use the new id.
A saved state holds the prompt state for the model and quantisation it came from. Do not restore it into a different model, quantisation or context size. The restore call fails if the state does not fit, but a state from another model is not always detected.
A slot that is busy with a request is served after that request ends.
The API is for llama-cpp only. Other backends return 501.
ik_llama.cpp is a hard fork of llama.cpp by Iwan Kawrakow that focuses on superior CPU and hybrid GPU/CPU performance. It ships additional quantization types (IQK quants), custom quantization mixes, Multi-head Latent Attention (MLA) for DeepSeek models, and fine-grained tensor offload controls - particularly useful for running very large models on commodity CPU hardware.
Note
The ik-llama-cpp backend requires a CPU with AVX2 support. The IQK kernels are not compatible with older CPUs.
Features
The ik-llama-cpp backend supports the following features:
IQK quantization types for better CPU inference performance
Multimodal models (via clip/llava)
Setup
The backend is distributed as a separate container image and can be installed from the LocalAI backend gallery, or specified directly in a model configuration. GGUF models loaded with this backend benefit from ik_llama.cpp’s optimized CPU kernels - especially useful for MoE models and large quantized models that would otherwise be GPU-bound.
YAML configuration
To use the ik-llama-cpp backend, specify it as the backend in the YAML file:
name:my-modelbackend:ik-llama-cppparameters:# Relative to the models pathmodel:file.gguf
The aliases ik-llama and ik_llama are also accepted.
turboquant (llama.cpp fork with TurboQuant KV-cache)
llama-cpp-turboquant is a llama.cpp fork that adds the TurboQuant KV-cache quantization scheme. It reuses the upstream llama.cpp codebase and ships as a drop-in alternative backend inside LocalAI, sharing the same gRPC server sources as the stock llama-cpp backend - so any GGUF model that runs on llama-cpp also runs on turboquant.
You would pick turboquant when you want smaller KV-cache memory pressure (longer contexts on the same VRAM) or to experiment with the fork’s quantized KV representations on top of the standard cache_type_k / cache_type_v knobs already supported by upstream llama.cpp.
Features
Drop-in GGUF compatibility with upstream llama.cpp.
TurboQuant KV-cache quantization (see fork README for the current set of accepted cache_type_k / cache_type_v values).
Same feature surface as the llama-cpp backend: text generation, embeddings, tool calls, multimodal via mmproj.
Available on CPU (AVX/AVX2/AVX512/fallback), NVIDIA CUDA 12/13, AMD ROCm/HIP, Intel SYCL f32/f16, Vulkan, and NVIDIA L4T.
Setup
turboquant ships as a separate container image in the LocalAI backend gallery. Install it like any other backend:
local-ai backends install turboquant
Or pick a specific flavor for your hardware (example tags: cpu-turboquant, cuda12-turboquant, cuda13-turboquant, rocm-turboquant, intel-sycl-f16-turboquant, vulkan-turboquant).
YAML configuration
To run a model with turboquant, set the backend in your model YAML and optionally pick quantized KV-cache types:
name:my-modelbackend:turboquantparameters:# Relative to the models pathmodel:file.gguf# Use TurboQuant's own KV-cache quantization schemes. The fork accepts# the standard llama.cpp types (f16, f32, q8_0, q4_0, q4_1, q5_0, q5_1)# and adds three TurboQuant-specific ones: turbo2, turbo3, turbo4.# turbo3 / turbo4 auto-enable flash_attention (required for turbo K/V)# and offer progressively more aggressive compression.cache_type_k:turbo3cache_type_v:turbo3context_size:8192
The cache_type_k / cache_type_v fields map to llama.cpp’s -ctk / -ctv flags. The stock llama-cpp backend only accepts the standard llama.cpp types - to use turbo2 / turbo3 / turbo4 you need this turboquant backend, which is where the fork’s TurboQuant code paths actually take effect. Pick q8_0 here and you’re just running stock llama.cpp KV quantization; pick turbo* and you’re running TurboQuant.
The backend will automatically download the required files in order to run the model.
Usage
Use the completions endpoint by specifying the vllm backend:
curl http://localhost:8080/v1/completions -H "Content-Type: application/json" -d '{
   "model": "vllm",
   "prompt": "Hello, my name is",
   "temperature": 0.1, "top_p": 0.1
 }'
Passing arbitrary vLLM options with engine_args
A subset of AsyncEngineArgs is exposed as typed YAML fields
(tensor_parallel_size, gpu_memory_utilization, quantization,
max_model_len, dtype, trust_remote_code, enforce_eager, …).
Anything else can be passed through the generic engine_args: map.
Keys are forwarded verbatim to vLLM’s engine; unknown keys fail at load
time with the closest valid name as a hint. Nested maps materialise
into vLLM’s nested config dataclasses (SpeculativeConfig,
KVTransferConfig, CompilationConfig, …).
Speculative decoding (DFlash, ngram, eagle, deepseek_mtp, …) is
configured this way:
method picks the algorithm, the remaining keys are method-specific.
Drafters from z-lab are paired with
specific target models; pick the one that matches your target. The
drafter loads in its native precision regardless of the target’s
quantization: setting.
Another example - picking a non-default attention backend (e.g. on
hardware where the default cutlass kernels aren’t supported):
engine_args:attention_backend:TRITON_ATTN
CLI-style engine flags in options
Engine arguments can also be written in options: with vLLM’s own CLI
spelling, which is handy when copying a command line out of vLLM’s
documentation:
Only -- prefixed entries are treated as engine flags; everything
else in options: (tool_parser:, reasoning_parser:, …) keeps its
existing meaning. Both --flag:value and --flag=value are accepted.
Dashes become underscores (--enable-prefix-caching →
enable_prefix_caching) and the value is coerced to the target
field’s type. A bare --flag sets a boolean field to true.
Unknown or uncoercible flags are logged on the backend’s stderr and
skipped rather than failing the load. engine_args: stays strict and
is applied last, so it wins on conflict.
engine_args: remains the form to use for anything structured (nested
configs, maps); options: is a convenience for flat flags.
Multi-node data parallelism
engine_args.data_parallel_size > 1 combined with the
local-ai p2p-worker vllm follower lets a single model span multiple
GPU nodes. See vLLM Multi-Node (Data-Parallel)
for the head/follower configuration and a worked Kimi-K2.6 example.
SGLang
SGLang is a fast serving
framework for LLMs and VLMs with a focus on prefix caching, speculative
decoding, and multi-modal generation. LocalAI ships a gRPC backend that
wraps SGLang’s async Engine, including its native function-call and
reasoning parsers.
The backend will pull the model from HuggingFace on first load.
Passing arbitrary SGLang options with engine_args
The same engine_args: map that the vLLM backend accepts is also
honoured by the SGLang backend. Keys are validated against
ServerArgs
SGLang’s central configuration dataclass - and forwarded verbatim to
Engine(**kwargs). Unknown keys fail at load time with the closest
valid name as a hint. Unlike vLLM, ServerArgs is flat: speculative
decoding fields are top-level (speculative_algorithm,
speculative_draft_model_path, etc.) rather than nested under a
speculative_config: dict.
The typed YAML fields shared with vLLM are mapped to their SGLang
equivalents (gpu_memory_utilization → mem_fraction_static,
enforce_eager → disable_cuda_graph, tensor_parallel_size →
tp_size, max_model_len → context_length). Anything else,
including all speculative-decoding flags, goes under engine_args:.
Speculative decoding: Gemma 4 with Multi-Token Prediction
Google publishes paired “assistant” drafters for every Gemma 4 size.
The drafters use Multi-Token Prediction (MTP) to propose several
candidate tokens per target step, which SGLang then verifies in
parallel. Flags below are transcribed verbatim from the
SGLang Gemma 4 cookbook.
For consumer GPUs in the 16-24 GB range, use E4B (8 B total /
4 B effective parameters):
For smaller cards (8-12 GB), drop to E2B (5 B total / 2 B effective)
by swapping the model paths to google/gemma-4-E2B-it and
google/gemma-4-E2B-it-assistant; the rest of the flags stay the same.
NEXTN is normalised to EAGLE inside ServerArgs.__post_init__, so
either value works - the cookbook uses NEXTN. mem_fraction_static
is the share of GPU memory SGLang reserves for the model + KV pool;
0.85 is the cookbook’s default and adapts to whatever single GPU the
backend is running on.
The 31 B dense and 26 B-A4B MoE Gemma 4 variants exist in the same
cookbook but require --tp-size 2, so they’re not in the gallery as
single-GPU recipes.
SGLang version requirement. Gemma 4 support landed in SGLang via
PR #21952. The
LocalAI sglang backend pins a release that includes it; if you’ve
overridden the pin to an older version, this recipe will fail with a
“model architecture not recognised” error at load time.
Other speculative algorithms
speculative_algorithm: also accepts EAGLE/EAGLE3 (paired with an
EAGLE-style draft head), DFLASH (block-diffusion drafters from
z-lab for the Qwen3 family), STANDALONE
(a smaller draft LLM verifying a larger target), and NGRAM (no draft
model - pure prefix-history speculation). See SGLang’s
speculative-decoding docs
for the full algorithm matrix.
Tool calling and reasoning parsers
SGLang’s native parsers stream tool_calls and reasoning_content
inside ChatDelta - the LocalAI Python backend wires them up
per-request rather than via engine_args:. Pick a parser by name:
thinking_budget sets a positive integer token budget for reasoning on each request.
Invalid, zero, and negative values produce a warning and leave the budget unset.
SGLang requires engine_args.enable_strict_thinking: true to enforce the budget.
LocalAI warns if you configure a budget without that engine option.
Keep the budget well below the max_tokens of your requests: if max_tokens is reached first,
the budget never triggers and the whole reply can be spent on reasoning, leaving the answer empty.
effort_budgets maps the request’s reasoning_effort to its own budget, so the levels differ in how long the model may think:
options:- thinking_budget:256 # fallback: no effort, or a level not listed below- effort_budgets:low=256;medium=1024;high=4096;xhigh=16384;max=16384
Entries are separated by ; and use the same parsing rules as thinking_budget (invalid entries are skipped with a warning).
A request whose effort is not listed falls back to thinking_budget; without either, no budget is sent.
A level listed here also turns reasoning on for that request, even when reasoning_default:off is set; an explicit enable_thinking: "false" in the request metadata (also sent when the model sets reasoning.disable: true) still wins.
The budget is an upper bound, not a target: the model may stop thinking earlier.
reasoning_default:on or reasoning_default:off sets the default for LocalAI’s tokenizer chat template.
Request metadata enable_thinking set to "true" or "false" overrides this default.
An explicit prompt bypasses tokenizer template rendering.
When no default or request override is set, the template keeps its own behavior.
LocalAI signals required reasoning when the rendered prompt ends with the configured parser’s opening reasoning token.
An explicit output grammar disables this detection.
Configure a reasoning parser that matches your model.
The backend reads these options when it loads the model.
POST /models/reload rereads model configuration files but does not update options in an already loaded backend.
Restarting only the backend does not reread configuration files.
Restart LocalAI after changing these options to reload both the configuration and the backend.
vllm.cpp
vllm.cpp is the LocalAI team’s C++ port of
vLLM: the same continuous-batching scheduler, paged KV cache and prefix caching,
with no Python at inference time. It consumes either a HuggingFace safetensors
model directory or a .gguf file, and applies the model’s chat template,
tool-call parsing and reasoning split engine-side.
This section is the configuration reference. For installing the backend and the
ready-made models the gallery ships for it, see the
vllm.cpp backend page.
The same engine_args: map the vLLM and SGLang backends accept is honoured
here, with keys spelled exactly as vLLM’s own CLI flags - so a speculative_config
or kv_transfer_config block written for vLLM works verbatim. Unknown keys are
ignored rather than fatal; the engine validates the documents it is handed and
reports a precise error at load.
name:qwen35-a3bbackend:vllm-cppparameters:model:"Qwen/Qwen3.5-A3B"context_size:16384template:use_tokenizer_template:trueengine_args:# KV cache sizing: num_blocks * block_size tokens of cache.block_size:32num_blocks:1024# Concurrency and the per-step chunked-prefill token budget.max_num_seqs:32max_num_batched_tokens:8192# Automatic prefix caching. Omit to keep the model's own default# (on for dense models, off for hybrid / attention-free ones).enable_prefix_caching:true# Scheduler admission order: fcfs (default), priority, or lpm# (cache-aware longest-prefix-match; needs prefix caching to have any effect).scheduling_policy:lpm
Key
Meaning
Default
block_size
KV-cache block size, in tokens per block
32
num_blocks
KV-cache blocks to allocate
256
max_model_len
Max sequence length; also settable as context_size / max_model_len
model config
max_num_seqs
Max concurrent sequences the scheduler admits
8
max_num_batched_tokens
Per-step chunked-prefill token budget
per-arch (2048 dense, 4096/8192 MoE)
enable_prefix_caching
Automatic prefix caching; enable_radix_attention is an accepted alias
model default
enable_jump_forward
Jump-forward decoding, which emits grammar-forced tokens without a model step. Only affects constrained requests (grammar, JSON schema)
off
scheduling_policy
fcfs, priority, or lpm
fcfs
tool_parser / reasoning_parser
Force a parser instead of chat-template auto-detection
auto
tokenizer_config
Override the tokenizer_config.json the chat template is read from
<model_dir>/tokenizer_config.json
speculative_config
Speculative decoding (see below)
disabled
kv_transfer_config
External KV connector / LMCache (see below)
none
hf_overrides
JSON object of config.json keys merged over the model directory’s own, as vLLM’s --hf-overrides (see the vllm.cpp backend page)
none
Raising max_num_batched_tokens lets more prefill land in a single step, at the
cost of decode latency for requests queued behind it. The default deliberately
does not scale with max_num_seqs, which is what keeps a large concurrent
prefill from blowing up the per-step activation on the hybrid architectures.
enable_prefix_caching and enable_jump_forward are tri-state at the engine
boundary: omitting the key defers to a default (the model’s own capability for
prefix caching, an environment variable for jump forward), while an explicit
false forces the feature off. Those are genuinely different - prefix caching
defaults on for dense models - so write the key only when you mean to override.
Speculative decoding
speculative_config: takes the same JSON object as vLLM’s
--speculative-config. Three methods are supported.
Architecture limit. At the current engine pin, mtp and dflash are
Qwen3.5 / Qwen3.6 only. The engine builds a widened speculative KV cache
directly for those families rather than through the model registry, so a
speculative config on any other architecture (Llama, GLM, Gemma, Mistral, …)
will not work regardless of checkpoint format. ngram needs no draft weights
and is not subject to this limit.
Format support.mtp and dflash now work from a .gguf target as well
as safetensors. An MTP head is read from the GGUF’s nextn.* tensors when the
file declares <arch>.nextn_predict_layers; a GGUF exported WITHOUT the head
(converted with --no-mtp, or predating llama.cpp’s Qwen3.5 MTP support) is
refused at load naming that as the reason. A DFlash draft may itself be a
dflash-arch GGUF, and the target may be a GGUF too. ngram needs no draft
weights and works on any format.
MTP (Multi-Token Prediction) uses a draft head shipped inside the target
checkpoint’s own mtp.* tensors, so there is no second model to download. It
requires a safetensors checkpoint - the mtp.* tensors do not survive GGUF
conversion, and an MTP config over a .gguf model is rejected at load.
engine_args:speculative_config:method:mtp# Optional; defaults to the checkpoint's own head depth, which is# usually the right value. Must be a multiple of that depth.num_speculative_tokens:1
DFlash uses a separate block-diffusion drafter that proposes a whole block
of tokens in one non-autoregressive forward pass. Unlike MTP, the draft is its
own checkpoint, so model: is required:
The draft shares the target’sembed_tokens and lm_head, so both must come
from the same model family and the target must be safetensors.
The engine does not download the draft.model: is resolved, in order,
as a path as given, then as the last path segment under LocalAI’s models
directory (z-lab/Qwen3.6-27B-DFlash → <models>/Qwen3.6-27B-DFlash, which is
what LocalAI’s own downloader produces), then as the whole reference under the
models directory. Install the draft into LocalAI first, or give an absolute path
to a directory containing config.json. If none of those resolve, the load
fails immediately naming every location that was tried, rather than reporting a
missing checkpoint from inside the engine.
N-gram needs no draft model at all - it proposes from the prompt’s own
suffix history. num_speculative_tokens is required:
Auto-configuration on import. When you import a safetensors repository
with backend: vllm-cpp, LocalAI reads the checkpoint’s config.json and, if
it declares an MTP head (mtp_num_hidden_layers), writes
speculative_config: {method: mtp} into the generated engine_args for you.
An explicit speculative_config in your own config is never overwritten.
Importing a DFlash draft repository is refused with a warning: a drafter
cannot serve on its own, so import the target model and point
speculative_config.model at the draft.
External KV cache with LMCache
kv_transfer_config: takes vLLM’s --kv-transfer-config JSON and selects an
external KV-cache connector. The lm:// LMCache client lets prefill KV be
stored to and reloaded from a shared lmcache.v1.server, so a prefix computed
by one replica does not have to be recomputed by the next:
engine_args:kv_transfer_config:kv_connector:LMCacheConnectorkv_role:kv_both # required whenever kv_connector is setkv_connector_extra_config:host:127.0.0.1port:65432
kv_role is one of kv_producer (store only), kv_consumer (load only), or
kv_both. An unregistered connector name, a missing role, or a malformed
document fails the load with an explicit error rather than silently running
without the cache.
Legacy options: list
Earlier versions configured this backend through the flat options: list, and
those configs keep working. Every key in the table above is still read from
there in key:value form, and engine_args wins on any key set in both:
New configs should prefer engine_args:, which is the only place the nested
speculative_config / kv_transfer_config documents can be written naturally
rather than as a single-line JSON string.
Transformers
Transformers is a State-of-the-art Machine Learning library for PyTorch, TensorFlow, and JAX.
LocalAI has a built-in integration with Transformers, and it can be used to run models.
This is an extra backend - in the container images (the extra images already contains python dependencies for Transformers) is already available and there is nothing to do for the setup.
Setup
Create a YAML file for the model you want to use with transformers.
To setup a model, you need to just specify the model name in the YAML config file:
name:transformersbackend:transformersparameters:model:"facebook/opt-125m"type:AutoModelForCausalLMquantization:bnb_4bit# One of: bnb_8bit, bnb_4bit, xpu_4bit, xpu_8bit (optional)
The backend will automatically download the required files in order to run the model.
Parameters
Type
Type
Description
AutoModelForCausalLM
AutoModelForCausalLM is a model that can be used to generate sequences. Use it for NVIDIA CUDA and Intel GPU with Intel Extensions for Pytorch acceleration
OVModelForCausalLM
for Intel CPU/GPU/NPU OpenVINO Text Generation models
OVModelForFeatureExtraction
for Intel CPU/GPU/NPU OpenVINO Embedding acceleration
N/A
Defaults to AutoModel
OVModelForCausalLM requires OpenVINO IR Text Generation models from Hugging face
OVModelForFeatureExtraction works with any Safetensors Transformer Feature Extraction model from Huggingface (Embedding Model)
Please note that streaming is currently not implemented in AutoModelForCausalLM for Intel GPU.
AMD GPU support is not implemented.
Although AMD CPU is not officially supported by OpenVINO there are reports that it works: YMMV.
Embeddings
Use embeddings: true if the model is an embedding model
Inference device selection
Transformer backend tries to automatically select the best device for inference, anyway you can override the decision manually overriding with the main_gpu parameter.
Inference Engine
Applicable Values
CUDA
cuda, cuda.X where X is the GPU device like in nvidia-smi -L output
OpenVINO
Any applicable value from Inference Modes like AUTO,CPU,GPU,NPU,MULTI,HETERO
Example for CUDA:
main_gpu: cuda.0
Example for OpenVINO:
main_gpu: AUTO:-CPU
This parameter applies to both Text Generation and Feature Extraction (i.e. Embeddings) models.
Inference Precision
Transformer backend automatically select the fastest applicable inference precision according to the device support.
CUDA backend can manually enable bfloat16 if your hardware support it with the following parameter:
f16: true
Quantization
Quantization
Description
bnb_8bit
8-bit quantization
bnb_4bit
4-bit quantization
xpu_8bit
8-bit quantization for Intel XPUs
xpu_4bit
4-bit quantization for Intel XPUs
Trust Remote Code
Some models like Microsoft Phi-3 requires external code than what is provided by the transformer library.
By default it is disabled for security.
It can be manually enabled with:
trust_remote_code: true
Maximum Context Size
Maximum context size in bytes can be specified with the parameter: context_size. Do not use values higher than what your model support.
Usage example:
context_size: 8192
Auto Prompt Template
Usually chat template is defined by the model author in the tokenizer_config.json file.
To enable it use the use_tokenizer_template: true parameter in the template section.
Usage example:
template:
  use_tokenizer_template: true
Custom Stop Words
Stopwords are usually defined in tokenizer_config.json file.
They can be overridden with the stopwords parameter in case of need like in llama3-Instruct model.
Usage example:
stopwords:
- "<|eot_id|>"
- "<|end_of_text|>"
Usage
Use the completions endpoint by specifying the transformers model:
curl http://localhost:8080/v1/completions -H "Content-Type: application/json" -d '{
   "model": "transformers",
   "prompt": "Hello, my name is",
   "temperature": 0.1, "top_p": 0.1
 }'
Examples
OpenVINO
A model configuration file for openvion and starling model:
The chat endpoint supports the grammar parameter, which allows users to specify a grammar in Backus-Naur Form (BNF). This feature enables the Large Language Model (LLM) to generate outputs adhering to a user-defined schema, such as JSON, YAML, or any other format that can be defined using BNF. For more details about BNF, see Backus-Naur Form on Wikipedia.
Note
Compatibility Notice: This feature is only supported by models that use the llama.cpp backend. For a complete list of compatible models, refer to the Model Compatibility page. For technical details, see the related pull requests: PR #1773 and PR #1887.
Setup
To use this feature, follow the installation and setup instructions on the LocalAI Functions page. Ensure that your local setup meets all the prerequisites specified for the llama.cpp backend.
💡 Usage Example
The following example demonstrates how to use the grammar parameter to constrain the model’s output to either “yes” or “no”. This can be particularly useful in scenarios where the response format needs to be strictly controlled.
In this example, the grammar parameter is set to a simple choice between “yes” and “no”, ensuring that the model’s response adheres strictly to one of these options regardless of the context.
Example: JSON Output Constraint
You can also use grammars to enforce JSON output format:
curl http://localhost:8080/v1/chat/completions -H "Content-Type: application/json" -d '{
  "model": "gpt-4",
  "messages": [{"role": "user", "content": "Generate a person object with name and age"}],
  "grammar": "root ::= \"{\" \"\\\"name\\\":\" string \",\\\"age\\\":\" number \"}\"\nstring ::= \"\\\"\" [a-z]+ \"\\\"\"\nnumber ::= [0-9]+"
}'
Moderation - OpenAI-compatible safety classification whose response is constrained to the moderation schema
Interleaved Thinking with Tool Calls
Reasoning models can “think” before they answer. When such a model also calls a tool, the useful behaviour is for the thinking and the tool call to travel together, and for that thinking to survive the tool-result round trip. LocalAI calls this interleaved thinking: a single assistant turn carries both reasoning and tool_calls, and the client hands the reasoning back on the next turn so the model’s chain of thought is not lost when the tool result is appended.
This matters because a tool-calling loop is multi-turn. The model reasons, asks for a tool, your client runs the tool, and then you call the model again with the tool result. Without interleaved thinking the reasoning produced in the first turn is discarded, and the model has to reconstruct its plan from scratch. With it, the reasoning is echoed back and the model continues where it left off.
An assistant turn that both reasons and calls a tool returns the two fields side by side:
reasoning holds the model’s thinking.
tool_calls holds the structured calls.
finish_reason is tool_calls.
Your client runs the tool, then sends the conversation back with:
the original assistant message (including its reasoning and tool_calls), and
a tool role message carrying the tool result.
LocalAI reads the returned reasoning back into the model’s context so the chain is continuous.
Field naming
OpenAI chat completions (/v1/chat/completions): the response carries reasoning alongside tool_calls. On inbound assistant messages LocalAI now also accepts reasoning_content as an alias for reasoning. This alias exists because several clients (vLLM, DeepSeek, and cogito) emit the field under the name reasoning_content; either name is accepted and mapped to the same internal field.
Anthropic Messages (/v1/messages): reasoning is carried as thinking content blocks. On the local path LocalAI emits a thinking block before the tool_use block, and reads inbound thinking blocks back into reasoning. Because local models produce no cryptographic signature, LocalAI attaches a synthetic opaque signature to the emitted block, and does not validate the signature on inbound blocks. The thinking block is only emitted when the request opts in with the thinking parameter:
{"model":"your-reasoning-model","max_tokens":1024,"thinking":{"type":"enabled"},"messages":[{"role":"user","content":"What is the weather in Rome?"}]}
Enabling reasoning per backend
Interleaved thinking requires the backend to separate the model’s thinking from its final answer. How you turn that on depends on the backend.
llama.cpp
Set the reasoning_format model option. Accepted values: none, auto, deepseek, deepseek-legacy. auto lets the backend pick based on the model’s chat template; deepseek and deepseek-legacy force the DeepSeek-style <think>...</think> extraction.
Set the reasoning_parser model option to vLLM’s native reasoning parser for the model family. LocalAI also ships an auto-configuration hook (core/config/hooks_vllm.go) that sets the reasoning parser and the tool-call parser together for known families, so for gallery-imported vLLM models this is often configured for you.
Request a chat completion with a tool defined and a prompt that requires the model to reason before acting:
curl http://localhost:8080/v1/chat/completions -H "Content-Type: application/json" -d '{
  "model": "your-reasoning-model",
  "messages": [
    { "role": "user", "content": "What is the weather in Rome?" }
  ],
  "tools": [
    {
      "type": "function",
      "function": {
        "name": "get_weather",
        "description": "Get the current weather for a city",
        "parameters": {
          "type": "object",
          "properties": {
            "city": { "type": "string" }
          },
          "required": ["city"]
        }
      }
    }
  ]
}'
The response message carries both the reasoning and the tool call, and finish_reason is tool_calls:
{"choices":[{"finish_reason":"tool_calls","message":{"role":"assistant","content":"","reasoning":"Okay, the user is asking about the weather in Rome... I need to call get_weather with city Rome.","tool_calls":[{"id":"call_abc123","type":"function","function":{"name":"get_weather","arguments":"{\"city\":\"Rome\"}"}}]}}]}
To continue, run get_weather, then send the conversation back with the assistant message (keeping its reasoning and tool_calls) followed by a tool message holding the result. LocalAI feeds the returned reasoning back into context so the model resumes its chain of thought.
Known limitations
Streaming Anthropic thinking blocks. In streaming mode, a thinking block is currently emitted only on the tool-call path that goes through the llama.cpp C++ autoparser. A plain streaming text-only turn, or a tool turn resolved through the inline token path, does not stream a thinking block. The equivalent non-streaming request does return one. Non-streaming emits thinking on all branches; only the streaming path has this gap.
Upstream llama.cpp leak on newest hybrid models. On the newest hybrid reasoning models (Qwen3.5 / Qwen3.6) there is an upstream llama.cpp bug where tool calls can leak into reasoning_content instead of being parsed into tool_calls. This is tracked upstream at ggml-org/llama.cpp discussion #23351.
Reasoning budget vs the tool call. If a reasoning model’s thinking exhausts the output budget (max_tokens) before it emits the tool call, no tool call is produced. Give the model enough max_tokens to cover both the reasoning and the call. In this case LocalAI reports finish_reason: "length".
Embeddings
LocalAI supports generating embeddings for text or list of tokens.
For face embeddings specifically, see the
Face Recognition feature - it produces
512-d L2-normalized vectors tuned for face similarity.
The embedding endpoint is compatible with llama.cpp models, bert.cpp models and sentence-transformers models available in huggingface.
Choosing the model
Send the model name in the request body. If the body has no model, LocalAI uses the configured embeddings model whose name comes first alphabetically. If no embeddings model is configured, the request returns 400 Bad Request. A model name is never taken from the bearer token unless it matches a configured model name exactly.
Using Gallery Models
LocalAI provides a model gallery with pre-configured embedding models. To use a gallery model:
Ensure the model is available in the gallery (check Model Gallery)
Use the model name directly in your API calls
Example gallery models:
qwen3-embedding-4b - Qwen3 Embedding 4B model
qwen3-embedding-8b - Qwen3 Embedding 8B model
qwen3-embedding-0.6b - Qwen3 Embedding 0.6B model
Example: Using Qwen3-Embedding-4B from Gallery
curl http://localhost:8080/embeddings -X POST -H "Content-Type: application/json" -d '{
  "input": "My text to embed",
  "model": "qwen3-embedding-4b",
  "dimensions": 2560
}'
Manual Setup
Create a YAML config file in the models directory. Specify the backend and the model file.
name:text-embedding-ada-002# The model name used in the APIparameters:model:<model_file>backend:"<backend>"embeddings:true
Hugging Face embeddings
To use sentence-transformers models from Hugging Face, set backend: transformers and type: SentenceTransformer.
curl http://localhost:8080/embeddings -X POST -H "Content-Type: application/json" -d '{
"input": "My text",
"model": "my-awesome-model"
}'| jq "."
Embedding chat conversations and Go-side pooling
/v1/embeddings also accepts a chat conversation via messages (a LocalAI
extension), plus a per-request pooling scheme that LocalAI applies itself to
the backend’s raw per-token vectors:
curl http://localhost:8080/v1/embeddings -X POST -H "Content-Type: application/json" -d '{
  "model": "my-awesome-model",
  "messages": [
    {"role": "system", "content": "You are a support agent."},
    {"role": "user", "content": "My invoice is wrong."}
  ],
  "pooling": "decayed_mean",
  "pooling_half_life_tokens": 256
}'
One conversation per request; the response is the standard OpenAI embeddings
shape with a single data[0].embedding item.
input and messages are mutually exclusive (400 otherwise); an unknown
pooling value is also a 400.
If the model config carries both template.chat and template.chat_message,
the conversation renders exactly like a chat prompt, so the embedding matches
what a chat model would actually see. Otherwise a frozen role-prefixed
fallback is used (<role>: <content> lines joined by newlines, empty-content
messages skipped). Non-text content parts (images, audio, video) are ignored.
pooling selects how the per-token vectors are reduced to one embedding:
Value
Meaning
(empty) / backend
The backend pools by itself — the default, today’s exact behavior.
mean
Average of all token vectors.
last
The last token’s vector.
decayed_mean
Recency-weighted mean: token i of T weighs 2^(-(T-1-i)/H) with half-life H = pooling_half_life_tokens (default 256) — recent turns dominate without erasing earlier context.
Go-side schemes need raw per-token vectors from the backend. Each backend
declares whether an embedding result is final or per-token; LocalAI rejects a
Go-side scheme for a final vector and rejects backend pass-through for a
per-token matrix instead of guessing from its shape. Older backends that do
not declare a layout remain compatible with backend pooling only.
llama.cpp chooses this layout when the model is loaded. LocalAI automatically
adds the pooling:none backend option when a llama.cpp model sets a Go-side
parameters.pooling scheme. That raw-loaded instance can switch between
mean, last, and decayed_mean per request, but it cannot switch back to
backend pooling without reloading. Conversely, a backend-pooled llama.cpp
instance rejects per-request Go pooling. Other backends may support Go-side
pooling when they explicitly return per-token vectors.
After Go-side pooling, the vector is normalized with llama.cpp’s
embd_normalize rule (default L2; configurable through
options: ["embd_normalize:<n>"]).
Go-side pooling requires an up-to-date backend that reports its embedding
layout. A legacy backend fails closed for Go-side schemes with an error asking
you to rebuild or update it.
💡 Examples
Example that uses LLamaIndex and LocalAI as embedding: here.
⚠️ Common Issues and Troubleshooting
Issue: Embedding model not returning correct results
Symptoms:
Model returns empty or incorrect embeddings
API returns errors when calling embedding endpoint
Common Causes:
Incorrect model filename: Ensure you’re using the correct filename from the gallery or your model file location.
Gallery models use specific filenames (e.g., Qwen3-Embedding-4B-Q4_K_M.gguf)
Returned embedding dimensions don’t match expected dimensions
Solution:
Use the dimensions parameter in your API request to specify the output dimension
Qwen3-Embedding models support dimensions from 32 to 2560 (4B) or 4096 (8B)
curl http://localhost:8080/embeddings -X POST -H "Content-Type: application/json" -d '{
  "input": "My text",
  "model": "qwen3-embedding-4b",
  "dimensions": 1024
}'
Issue: Model not found
Symptoms:
API returns 404 or “model not found” error
Solution:
Ensure the model is properly configured in the models directory
Check that the model name in your API request matches the name field in the configuration
For gallery models, ensure the gallery is properly loaded
Qwen3 Embedding Models Specifics
The Qwen3 Embedding series models have these characteristics:
Model
Parameters
Max Context
Max Dimensions
Supported Languages
qwen3-embedding-0.6b
0.6B
32k
1024
100+
qwen3-embedding-4b
4B
32k
2560
100+
qwen3-embedding-8b
8B
32k
4096
100+
All models support:
User-defined output dimensions (32 to max dimensions)
Multilingual text embedding (100+ languages)
Instruction-tuned embedding with custom instructions
Reranker
A reranking model, often referred to as a cross-encoder, is a core component in the two-stage retrieval systems used in information retrieval and natural language processing tasks.
Given a query and a set of documents, it will output similarity scores.
We can use then the score to reorder the documents by relevance in our RAG system to increase its overall accuracy and filter out non-relevant results.
LocalAI supports reranker models, and you can use them by using the rerankers backend, which uses rerankers.
Usage
You can test rerankers by using container images with python (this does NOT work with core images) and a model config file like this, or by installing cross-encoder from the gallery in the UI:
curl http://localhost:8080/v1/rerank \
-H "Content-Type: application/json"\
-d '{
"model": "jina-reranker-v1-base-en",
"query": "Organic skincare products for sensitive skin",
"documents": [
"Eco-friendly kitchenware for modern homes",
"Biodegradable cleaning supplies for eco-conscious consumers",
"Organic cotton baby clothes for sensitive skin",
"Natural organic skincare range for sensitive skin",
"Tech gadgets for smart homes: 2024 edition",
"Sustainable gardening tools and compost solutions",
"Sensitive skin-friendly facial cleansers and toners",
"Organic food wraps and storage solutions",
"All-natural pet food for dogs with allergies",
"Yoga mats made from recycled materials"
],
"top_n": 3
}'
Moderation
LocalAI exposes an OpenAI-compatible text moderation endpoint at
POST /v1/moderations. It uses a local text-generation model with a constrained
JSON grammar, so no separate moderation service or cloud API is required.
input may be one string or an array of strings. The response contains one
result per input with flagged, categories, category_scores, and
category_applied_input_types fields. The category names match the OpenAI
moderation API, including harassment, hate, illicit activity, self-harm,
sexual content, and violence categories.
The selected model must support text completion. For consistent results, use
an instruction-tuned model that follows safety-classification prompts well.
LocalAI constrains the output shape, but the model determines the classification
quality and confidence scores.
Note
This first implementation supports text only. OpenAI-style multimodal input
objects containing images return a validation error.
Time-Series Forecasting
LocalAI forecasts numeric time series with timestral.cpp, a C++/ggml port of Mistral’s Timestral models. You send one or more series, with optional covariates, to POST /v1/forecast and get quantile trajectories for the next steps.
A forecast model is not a chat model. It has its own usecase, forecast, and does not appear in the chat model picker. It shows in the gallery filter and in the /v1/models capability list.
Licence. The Timestral weights use Mistral’s Modified MIT licence. You may not use them if the global consolidated monthly revenue of your company (or your employer) exceeded USD 20 million in the preceding month, unless you get a commercial licence from Mistral AI. The restriction covers derivatives, so it also applies to the GGUF conversions in the gallery. Each gallery entry installs the licence text next to the weights. The timestral.cpp code is MIT.
Models
Gallery entry
Parameters
Builds
timestral-5m
5 million
F32 (default), F16
timestral-28m
28 million
F32 (default), F16
timestral-123m
123 million
F32 (default), F16
timestral-209m
209 million
F32 (default), F16
local-ai models install timestral-28m
The default build is F32. Install the F16 entry, for example timestral-28m-f16, for a build of about half the size. Quantized builds below F16 are not offered yet.
The engine runs on the CPU only. It is slower than the PyTorch reference at long context lengths, so keep the context short where you can and allow a long request timeout.
How much memory each build needs has not been measured yet, so the gallery sets no size.
Levels to return. Each must be a level the model was trained on. Default: 0.1, 0.5, 0.9.
max_context
integer
Most history steps the model uses. 0 or absent keeps the model default.
symmetric_averaging, clip_nonnegative
boolean or null
null or absent keeps the model default.
series
list
The series to forecast.
Each entry of series has these fields:
Field
Shape
Meaning
id
string
Optional. Returned with the result.
target
[variates][steps], or [steps] for one variate
History, oldest step first. null marks a missing value.
past_covariates
[covariates][steps]
Numeric covariates known only for the history.
known_covariates
[covariates][steps + prediction_length]
Numeric covariates that are also known for the future.
past_categorical
[covariates][steps]
Integer category codes for the history. null marks a missing code.
known_categorical
[covariates][steps + prediction_length]
Integer category codes that are also known for the future.
Series in one request can have different lengths and different numbers of variates or covariates. LocalAI groups them by shape, runs one forecast for each group, and returns the results in the order you sent the series.
values[q][h] is the value of level quantile_levels[q] at step h. Step 0 is the first step after the last step of the history. The numbers above are an example of the shape, not real output.
Errors
The endpoint returns 400 when:
prediction_length is less than 1, or series is empty.
A row has the wrong number of steps, for example a known covariate that stops at the end of the history.
A value is not a finite number, or a categorical code is not an integer. NaN and infinity are not valid JSON; use null for a missing value.
A requested quantile is not a level of the model. The error lists the valid levels.
The request is larger than the model limits.
Model options
Set these under options: in the model configuration:
History cap used when a request sets none. 0 keeps the model default.
max_series
256
Most series in one request.
max_total_points
2000000
Most input values in one request.
threads sets the number of CPU threads for each forecast.
The library is not reentrant, so LocalAI runs one forecast at a time for each loaded model.
Platforms
The backend image is built for Linux on amd64 and arm64. A build for Apple silicon is wired into the build matrix, but it has not been built or tested yet.
Benchmark text models
Use local-ai benchmark to compare text inference through a running LocalAI
server. Install and configure the models first. The command sends sequential,
non-streaming requests to /v1/chat/completions and reports full request latency
and end-to-end completion tokens per second.
Pass one or more configured model names. To compare backends, configure separate
model aliases with the desired backend, then pass those aliases. Backend names
alone are not model names. The command does not install, discover, or unload
models; the server’s normal loading and eviction settings still apply.
For example, with models named text-llama-cpp and text-vllm configured:
local-ai benchmark text-llama-cpp text-vllm --runs 5 --warmup 1\
--prompt 'Explain how a rainbow forms.' --max-tokens 128
To save settings, per-model summaries, and every measured sample:
For an authenticated server, set LOCALAI_API_KEY or API_KEY in the environment.
The API key is excluded from the JSON report. Use --endpoint for a remote server
or reverse proxy:
The endpoint accepts a server root, an optional /v1 suffix, and trailing
slashes. A reverse proxy path prefix is preserved. Redirects are refused.
Credentials in the URL, query strings, and fragments are rejected.
Arguments and flags
Argument or flag
Default
Description
MODEL ...
Required
One or more configured text model names.
--endpoint
http://127.0.0.1:8080
Server URL, optionally ending in /v1.
--api-key
Unset
API key; also reads LOCALAI_API_KEY, then API_KEY.
--prompt
Explain why the sky is blue.
Nonblank user message repeated for every request.
--max-tokens
128
Positive maximum number of completion tokens per request.
--runs
3
Positive number of measured requests per model.
--warmup
1
Unmeasured requests before each model; zero disables warmups.
--timeout
5m
Positive timeout per request, including reading its response.
--json
false
Write JSON instead of a table.
-h, --help
Show command help.
Every request sets temperature to 0 and streaming to false. Interrupting the
command cancels the active request. A failed request stops the benchmark with a
model and run error; results are written only after every model succeeds.
Reading the results
Each model has minimum, mean, and maximum latency across measured requests.
Latency runs from sending the request through parsing the complete response.
It includes transport, queueing, prompt processing, generation, and response
parsing. This command does not measure time to first token.
End-to-end completion tokens per second is the sum of server-reported completion
tokens divided by the sum of full request durations. It is not decode-only speed
or a substitute for llama-bench kernel measurements. If any measured response
omits completion token usage, throughput is null in JSON and N/A in the table.
Reported zero tokens remain zero. Missing prompt or completion counts remain
null in each JSON sample; the command never estimates tokens from text length.
Warmups run separately for each model and do not appear in measurements. They can
absorb model loading time, but repeated prompts can also benefit from prompt
caching. With --warmup 0, measured requests can include model loading. Other
clients and server queueing can affect results; compare under similar load.
Keep hardware, quantization, context size, backend settings, and prompt consistent
when comparing engines. Different model tokenizers can report different token
counts for the same text, and models can stop before --max-tokens. Temperature
zero does not guarantee identical output across models or engines. The JSON
settings describe the benchmark requests, not the server’s full model
configuration; record that configuration alongside the report.
Audio and speech
Speech to text, text to speech, sound classification, speakers and voice activity. The Voice add-on is a page for voice recognition and the voice library, and the Talk add-on is a page for a spoken conversation.
API Compatibility The LocalAI TTS API is compatible with the OpenAI TTS API and the Elevenlabs API.
LocalAI API The /tts endpoint can also be used to generate speech from text.
Usage Input: input, model
Sound-event classification (audio tagging) answers the question “what am I hearing?” - given an audio clip, it returns a list of scored AudioSet labels (e.g. Baby cry, infant cry, Glass breaking, Dog bark, Alarm).
LocalAI exposes this through the /v1/audio/classification endpoint, modelled after /v1/audio/transcriptions. The reference backend is ced.cpp (CED, a 527-class AudioSet tagger), a small ViT over a log-mel spectrogram ported to ggml with full PyTorch parity. Apache-2.0 weights are redistributable as GGUF.
Speaker diarization answers the question “who spoke when?” - given an audio clip with multiple speakers, it returns time-stamped segments labelled with a stable speaker ID (SPEAKER_00, SPEAKER_01, …).
LocalAI exposes this through the /v1/audio/diarization endpoint, modelled after /v1/audio/transcriptions. Five backends are supported today:
sherpa-onnx - pyannote-3.0 segmentation + a speaker-embedding extractor (3D-Speaker, NeMo, WeSpeaker) + fast clustering. Pure diarization - no transcription cost. Recommended when you only need speaker turns. vibevoice.cpp - produces speaker-labelled segments as a by-product of its long-form ASR pass, so you can optionally get a transcript per segment for free. NeMo-Speech.cpp - NVIDIA Sortformer, served standalone by the NeMo-Speech.cpp backend. It is end to end, so the speaker capacity is fixed by the checkpoint and the count hints are ignored. The same backend can instead put speaker tags on a transcript, by attaching a Sortformer model to an ASR one. audio.cpp - the sortformer_diar family, served by the multi-modality audio.cpp backend. parakeet.cpp - NVIDIA Nemotron-3-Diarization (Sortformer, up to 8 speakers), served standalone or paired with a Parakeet ASR model for per-segment text. See the Audio to Text page for the parakeet-cpp option reference. Because diarization is exposed as a regular OpenAI-compatible endpoint, any HTTP client works. There is no Python dependency on pyannote or NeMo on the consumer side.
The audio-transform endpoints take audio in and emit audio out, optionally conditioned on a second reference audio signal. The category is generic by design - concrete operations include joint acoustic echo cancellation + noise suppression + dereverberation (LocalVQE), voice conversion (reference = target speaker), pitch shifting, audio super-resolution, and so on.
Voice Activity Detection (VAD) identifies segments of speech in audio data. LocalAI provides a /v1/vad endpoint powered by the Silero VAD backend.
The audio.cpp backend also serves this endpoint, and ships the silero_vad and marblenet_vad assets inside its own package, so VAD works there with nothing to download (model: bundled:silero_vad plus the family:silero_vad option).
API Method: POST Endpoints: /v1/vad, /vad Request The request body is JSON with the following fields:
LocalAI supports voice (speaker) recognition: speaker verification (1:1), speaker identification (1:N) against a built-in vector store, speaker embedding, and demographic analysis (age / gender / emotion from voice).
The audio analog to Face Recognition, served over the same /v1/voice/* HTTP API by two backends:
Subsections of Audio and speech
Audio to Text
Audio to text models are models that can generate text from an audio file.
The transcription endpoint allows to convert audio files to text. The endpoint supports multiple backends:
whisper.cpp: A C++ library for audio transcription (default)
moonshine: Ultra-fast transcription engine optimized for low-end devices
faster-whisper: Fast Whisper implementation with CTranslate2
WhisperX: Whisper transcription with word alignment and optional speaker diarization. Set HF_TOKEN and pass diarize=true to load WhisperX’s gated pyannote diarization pipeline.
parakeet-cpp: A C++/ggml port of NVIDIA NeMo Parakeet (FastConformer TDT/CTC/RNNT/hybrid). Runs quantized GGUFs on CPU or GPU, emits word-level timestamps, and supports cache-aware streaming (the realtime_eou model surfaces end-of-utterance events). The same backend also loads Nemotron-3-Diarization (/v1/audio/diarization) and CED sound models (/v1/audio/classification), and can attach either as a companion to a transcription model.
llama-cpp: Route transcription to any multimodal-audio GGUF model served by the llama-cpp backend (e.g. Qwen3-ASR, Voxtral, Qwen2-Audio). Under the hood the request is converted into a chat completion with the audio attached via the model’s audio encoder - the same path the upstream llama.cpp server uses. Set backend: llama-cpp in the model YAML and point mmproj at the matching audio encoder.
voxtral: Voxtral-family models served by a dedicated backend
NeMo-Speech.cpp: NVIDIA’s C++/ggml runtime for the Nemotron Speech models. Serves offline, streaming and live transcription, with VAD, punctuation, inverse text normalization and Sortformer speaker tags attached through model options, and covers diarization, speech synthesis and translation from the same backend. See the NeMo-Speech.cpp backend page for the model options.
audio.cpp: Multi-family GGML audio engine. Serves transcription and forced alignment from families such as nemotron_asr, qwen3_asr, citrinet_asr, higgs_audio_stt and voxtral_realtime, and covers diarization, VAD, TTS and source separation from the same backend. See the audio.cpp backend page for the model options.
The endpoint input supports all the audio formats supported by ffmpeg.
Looking for “who spoke when” instead of a flat transcript? See Speaker Diarization - /v1/audio/diarization returns time-stamped speaker segments and supports the rttm format used by pyannote.metrics.
Usage
Once LocalAI is started and whisper models are installed, you can use the /v1/audio/transcriptions API endpoint.
When usage statistics are enabled, successful requests to /v1/audio/transcriptions
and /audio/transcriptions contribute request counts and elapsed time for the
requested model name, including an alias. This includes streaming responses. Token counts remain zero
because transcription results do not provide canonical token usage. Failed
transcriptions, including errors reported within a stream, do not count as
successful usage.
When API tracing is enabled, multipart transcription requests appear in Traces
with the model name, response, status, and elapsed time. The captured request
body contains metadata marked multipart upload omitted; API traces do not
store the uploaded audio. Response capture follows the configured trace size
limit. Backend traces have their own payload capture behavior.
Example
Download one of the models from here in the models folder,
and create a YAML file for your model:
The transcriptions endpoint then can be tested like so:
## Get an example audio filewget --quiet --show-progress -O gb1.ogg https://upload.wikimedia.org/wikipedia/commons/1/1f/George_W_Bush_Columbia_FINAL.ogg
## Send the example audio file to the transcriptions endpointcurl http://localhost:8080/v1/audio/transcriptions -H "Content-Type: multipart/form-data" -F file="@$PWD/gb1.ogg" -F model="whisper-1"
Result:
{"segments":[{"id":0,"start":0,"end":9640000000,"text":" My fellow Americans, this day has brought terrible news and great sadness to our country.","tokens":[50364,1222,7177,6280,11,341,786,575,3038,6237,2583,293,869,22462,281,527,1941,13,50846]},{"id":1,"start":9640000000,"end":15960000000,"text":" At 9 o'clock this morning, Mission Control and Houston lost contact with our Space Shuttle","tokens":[1711,1722,277,6,9023,341,2446,11,20170,12912,293,18717,2731,3385,365,527,8705,13870,10972,51162]},{"id":2,"start":15960000000,"end":16960000000,"text":" Columbia.","tokens":[17339,13,51212]},{"id":3,"start":16960000000,"end":24640000000,"text":" A short time later, debris was seen falling from the skies above Texas.","tokens":[316,2099,565,1780,11,21942,390,1612,7440,490,264,25861,3673,7885,13,51596]},{"id":4,"start":24640000000,"end":27200000000,"text":" The Columbia's lost.","tokens":[440,17339,311,2731,13,51724]},{"id":5,"start":27200000000,"end":29920000000,"text":" There are no survivors.","tokens":[821,366,572,18369,13,51860]},{"id":6,"start":29920000000,"end":32920000000,"text":" And board was a crew of seven.","tokens":[50364,400,3150,390,257,7260,295,3407,13,50514]},{"id":7,"start":32920000000,"end":39780000000,"text":" Colonel Rick Husband, Lieutenant Colonel Michael Anderson, Commander Laurel Clark, Captain","tokens":[28478,11224,21282,4235,11,28412,28478,5116,18768,11,20857,27270,75,18572,11,10873,50857]},{"id":8,"start":39780000000,"end":50020000000,"text":" David Brown, Commander William McCool, Dr. Cooltna Chavla, and Elon Ramon, a Colonel","tokens":[4389,8030,11,20857,6740,4050,34,1092,11,2491,13,8561,83,629,761,706,875,11,293,28498,9078,266,11,257,28478,51369]},{"id":9,"start":50020000000,"end":52800000000,"text":" in the Israeli Air Force.","tokens":[294,264,19974,5774,10580,13,51508]},{"id":10,"start":52800000000,"end":58480000000,"text":" These men and women assumed great risk in the service to all humanity.","tokens":[1981,1706,293,2266,15895,869,3148,294,264,2643,281,439,10243,13,51792]},{"id":11,"start":58480000000,"end":63120000000,"text":" And an age when Space Flight has come to seem almost routine.","tokens":[50364,400,364,3205,562,8705,28954,575,808,281,1643,1920,9927,13,50596]},{"id":12,"start":63120000000,"end":68800000000,"text":" It is easy to overlook the dangers of travel by rocket and the difficulties of navigating","tokens":[467,307,1858,281,37826,264,27701,295,3147,538,13012,293,264,14399,295,32054,50880]},{"id":13,"start":68800000000,"end":72640000000,"text":" the fierce outer atmosphere of the Earth.","tokens":[264,25341,10847,8018,295,264,4755,13,51072]},{"id":14,"start":72640000000,"end":78040000000,"text":" These astronauts knew the dangers and they faced them willingly.","tokens":[1981,28273,2586,264,27701,293,436,11446,552,44675,13,51342]},{"id":15,"start":78040000000,"end":83040000000,"text":" Knowing they had a high and noble purpose in life.","tokens":[25499,436,632,257,1090,293,20171,4334,294,993,13,51592]},{"id":16,"start":83040000000,"end":90800000000,"text":" Because of their courage and daring and idealism, we will miss them all the more.","tokens":[50364,1436,295,641,9892,293,43128,293,7157,1434,11,321,486,1713,552,439,264,544,13,50752]},{"id":17,"start":90800000000,"end":96560000000,"text":" All Americans today are thinking as well of the families of these men and women who have","tokens":[1057,6280,965,366,1953,382,731,295,264,4466,295,613,1706,293,2266,567,362,51040]},{"id":18,"start":96560000000,"end":100440000000,"text":" been given this sudden shock in grief.","tokens":[668,2212,341,3990,5588,294,18998,13,51234]},{"id":19,"start":100440000000,"end":102400000000,"text":" You're not alone.","tokens":[509,434,406,3312,13,51332]},{"id":20,"start":102400000000,"end":105440000000,"text":" Our entire nation agrees with you.","tokens":[2621,2302,4790,26383,365,291,13,51484]},{"id":21,"start":105440000000,"end":112360000000,"text":" And those you loved will always have the respect and gratitude of this country.","tokens":[400,729,291,4333,486,1009,362,264,3104,293,16935,295,341,1941,13,51830]},{"id":22,"start":112360000000,"end":116600000000,"text":" The cause in which they died will continue.","tokens":[50364,440,3082,294,597,436,4539,486,2354,13,50576]},{"id":23,"start":116600000000,"end":124240000000,"text":" Man kind is led into the darkness beyond our world by the inspiration of discovery and the","tokens":[2458,733,307,4684,666,264,11262,4399,527,1002,538,264,10249,295,12114,293,264,50958]},{"id":24,"start":124240000000,"end":127000000000,"text":" longing to understand.","tokens":[35050,281,1223,13,51096]},{"id":25,"start":127000000000,"end":131160000000,"text":" Our journey into space will go on.","tokens":[2621,4671,666,1901,486,352,322,13,51304]},{"id":26,"start":131160000000,"end":136480000000,"text":" In the skies today, we saw destruction and tragedy.","tokens":[682,264,25861,965,11,321,1866,13563,293,18563,13,51570]},{"id":27,"start":136480000000,"end":142080000000,"text":" As farther than we can see, there is comfort and hope.","tokens":[1018,20344,813,321,393,536,11,456,307,3400,293,1454,13,51850]},{"id":28,"start":142080000000,"end":149800000000,"text":" In the words of the prophet Isaiah, lift your eyes and look to the heavens who created","tokens":[50364,682,264,2283,295,264,18566,27263,11,5533,428,2575,293,574,281,264,26011,567,2942,50750]},{"id":29,"start":149800000000,"end":151640000000,"text":" all these.","tokens":[439,613,13,50842]},{"id":30,"start":151640000000,"end":159960000000,"text":" He who brings out the story hosts one by one and calls them each by name because of his great","tokens":[634,567,5607,484,264,1657,21573,472,538,472,293,5498,552,1184,538,1315,570,295,702,869,51258]},{"id":31,"start":159960000000,"end":163400000000,"text":" power and mighty strength.","tokens":[1347,293,21556,3800,13,51430]},{"id":32,"start":163400000000,"end":166400000000,"text":" Not one of them is missing.","tokens":[1726,472,295,552,307,5361,13,51580]},{"id":33,"start":166400000000,"end":173600000000,"text":" The same creator who names the stars also knows the names of the seven souls we mourn","tokens":[50364,440,912,14181,567,5288,264,6105,611,3255,264,5288,295,264,3407,16588,321,22235,77,50724]},{"id":34,"start":173600000000,"end":175600000000,"text":" today.","tokens":[965,13,50824]},{"id":35,"start":175600000000,"end":183160000000,"text":" The crew of the shuttle Columbia did not return safely to earth yet we can pray that all","tokens":[440,7260,295,264,26728,17339,630,406,2736,11750,281,4120,1939,321,393,3690,300,439,51202]},{"id":36,"start":183160000000,"end":185840000000,"text":" are safely home.","tokens":[366,11750,1280,13,51336]},{"id":37,"start":185840000000,"end":192600000000,"text":" May God bless the grieving families and may God continue to bless America.","tokens":[1891,1265,5227,264,48454,4466,293,815,1265,2354,281,5227,3374,13,51674]},{"id":38,"start":196400000000,"end":206400000000,"text":" [BLANK_AUDIO]","tokens":[50364,542,37592,62,29937,60,50864]}],"text":"My fellow Americans, this day has brought terrible news and great sadness to our country. At 9 o'clock this morning, Mission Control and Houston lost contact with our Space Shuttle Columbia. A short time later, debris was seen falling from the skies above Texas. The Columbia's lost. There are no survivors. And board was a crew of seven. Colonel Rick Husband, Lieutenant Colonel Michael Anderson, Commander Laurel Clark, Captain David Brown, Commander William McCool, Dr. Cooltna Chavla, and Elon Ramon, a Colonel in the Israeli Air Force. These men and women assumed great risk in the service to all humanity. And an age when Space Flight has come to seem almost routine. It is easy to overlook the dangers of travel by rocket and the difficulties of navigating the fierce outer atmosphere of the Earth. These astronauts knew the dangers and they faced them willingly. Knowing they had a high and noble purpose in life. Because of their courage and daring and idealism, we will miss them all the more. All Americans today are thinking as well of the families of these men and women who have been given this sudden shock in grief. You're not alone. Our entire nation agrees with you. And those you loved will always have the respect and gratitude of this country. The cause in which they died will continue. Man kind is led into the darkness beyond our world by the inspiration of discovery and the longing to understand. Our journey into space will go on. In the skies today, we saw destruction and tragedy. As farther than we can see, there is comfort and hope. In the words of the prophet Isaiah, lift your eyes and look to the heavens who created all these. He who brings out the story hosts one by one and calls them each by name because of his great power and mighty strength. Not one of them is missing. The same creator who names the stars also knows the names of the seven souls we mourn today. The crew of the shuttle Columbia did not return safely to earth yet we can pray that all are safely home. May God bless the grieving families and may God continue to bless America. [BLANK_AUDIO]"}
You can also specify the response_format parameter to be one of lrc, srt, vtt, text, json or verbose_json (default):
## Send the example audio file to the transcriptions endpointcurl http://localhost:8080/v1/audio/transcriptions -H "Content-Type: multipart/form-data" -F file="@$PWD/gb1.ogg" -F model="whisper-1" -F response_format="srt"
Result (first few lines):
1
00:00:00,000 --> 00:00:09,640
My fellow Americans, this day has brought terrible news and great sadness to our country.

2
00:00:09,640 --> 00:00:15,960
At 9 o'clock this morning, Mission Control and Houston lost contact with our Space Shuttle

3
00:00:15,960 --> 00:00:16,960
Columbia.

4
00:00:16,960 --> 00:00:24,640
A short time later, debris was seen falling from the skies above Texas.

5
00:00:24,640 --> 00:00:27,200
The Columbia's lost.

6
00:00:27,200 --> 00:00:29,920
There are no survivors.
Supported request parameters
In addition to file and model, the endpoint accepts the following multipart form fields, matching the OpenAI audio transcription API:
Field
Description
language
ISO-639-1 language hint (e.g. en). Passed through to the backend.
prompt
Optional context hint to bias the decoder.
temperature
Sampling temperature (float). Honored by backends that support it.
timestamp_granularities[]
Multi-value form field: word and/or segment. Honored when the backend produces the requested granularity.
response_format
One of json (default for backwards-compat), verbose_json, text, srt, vtt, lrc.
stream
When true, the endpoint emits an SSE stream of transcript.text.delta events followed by a final transcript.text.done event.
diarize
LocalAI extension - speaker diarization. WhisperX requires HF_TOKEN; requests fail with FailedPrecondition when it is missing.
If speaker diarization fails after transcription succeeded, the WhisperX backend logs the error and returns the transcript without speaker labels. Other transcription failures return an error instead of an empty transcript. Diarization still requires HF_TOKEN.
The response body for verbose_json includes text, language, duration, and segments[] (with speaker populated when diarization is enabled).
Streaming transcriptions
Set -F stream=true to receive token-by-token SSE events as the backend produces them. The event shape matches the OpenAI streaming transcription format:
data: {"type":"transcript.text.delta","delta":"And so, my"}

data: {"type":"transcript.text.delta","delta":" fellow Americans..."}

data: {"type":"transcript.text.done","text":"And so, my fellow Americans..."}

data: [DONE]
Backends that do not natively stream tokens fall back to emitting one delta plus a done event with the full text - the SSE contract is identical either way.
Using the llama-cpp backend with an audio-capable model
Any GGUF model whose mmproj contains an audio encoder can be used for transcription via the llama-cpp backend. This reuses the model’s own audio front-end rather than shelling out to whisper.cpp, which is useful when you want a single backend serving both chat-with-audio and transcription.
The gallery entries lfm3-audio-2b and lfm3-audio-2b-q8 also transcribe through the llama-cpp backend, using the same model as speech-to-speech and TTS. When a language is given, the request asks for transcription in that language with the system prompt Perform ASR in <Language>.. Without one, the model is asked to infer the language. Transcription uses the second slot (parallel:2), so it can run next to a realtime session. A realtime session does not use it for the input transcript by default; see Realtime. This needs a llama.cpp build with LFM3-Audio support.
Using the parakeet-cpp backend
parakeet.cpp is a C++/ggml port of NVIDIA NeMo Parakeet that matches the upstream PyTorch models on CPU. GGUF weights for every model and quant are published in a single repo, mudler/parakeet-cpp-gguf. F16 is the recommended default, and Q4_K stays near-lossless on the small models. The easiest path is to import directly (the GGUFs auto-detect to this backend):
For real-time use, load a cache-aware streaming model (e.g. realtime_eou_120m-v1-*.gguf) and pass -F stream=true. Deltas are emitted as the audio is decoded, with end-of-utterance events closing each segment.
Diarization and sound classification
The same backend also serves the /v1/audio/diarization and /v1/audio/classification endpoints, and can attach a diarization or sound model to a live transcription session. options: accepts paths relative to the models directory, or absolute:
Option
Allowed on
Used for
asr_model:<path>
a diarization model
include_text on /v1/audio/diarization
diarization_model:<path>
an ASR model
a speaker on transcript segments (and words), and speaker segments during realtime live transcription
sound_model:<path>
an ASR or diarization model
sound events during realtime live transcription, sounds on /v1/audio/diarization with include_sounds=true, and /v1/audio/classification on the loaded model
extra encoder tag for registered voices that carry only a file-name tag (see Voice Recognition)
speaker_threshold:<float>
a model with speaker_model
distance (1 minus cosine similarity) under which a speaker is named, in (0, 2); default 0.5
speaker_margin:<float>
a model with speaker_model
how much the best match must beat the runner-up, in [0, 1); default 0.05
speaker_strict:<bool>
a model with speaker_model
do not use registered voices that have no encoder fingerprint (see Voice Recognition); default false
With a diarization_model companion, /v1/audio/transcriptions labels each segment with its speaker ("0", "1", … in order of first appearance) and splits segments where the speaker changes; with timestamp_granularities[]=word each word carries its speaker too. With stream=true the closing transcript.text.done event lists the segments with their speakers. Pass -F diarize=false to skip diarization for one request. The diarization GGUF can also be imported directly: local-ai models import https://huggingface.co/mudler/parakeet-cpp-gguf/resolve/main/nemotron-3-diarization-f16.gguf.
speaker_model: needs libparakeet with C-API v10. A wrong setup fails at load time with one of these errors: parakeet-cpp: speaker_model needs libparakeet.so ABI 10 (parakeet_capi_speaker_registry_add_embedding); the loaded library is older, parakeet-cpp: speaker_model needs a diarization model (the primary or diarization_model:), parakeet-cpp: a speaker model cannot be the primary model; use it as speaker_model: next to a diarization model, parakeet-cpp: speaker_model "<path>" is a <kind> model, expected a speaker model (the file is not a speaker encoder GGUF), or parakeet-cpp: speaker_threshold "<value>" must be a distance in (0, 2) (1 minus cosine similarity) / parakeet-cpp: speaker_margin "<value>" must be a number in [0, 1) for a bad number.
The loader rejects a companion whose role duplicates the primary’s own (for example asr_model: on an already-ASR primary, or sound_model: on a CED primary), and rejects a companion GGUF that does not match the role its option names (for example sound_model: pointing at an ASR GGUF fails to load, naming the kind it expected). See Speaker Diarization for the Diarize RPC and Sound Classification for SoundDetection, and Realtime API for the live speaker/sound events emitted during a realtime session.
Segment timestamps
Transcriptions are split into segments the same way NVIDIA NeMo does: a new segment starts after sentence-ending punctuation (., ?, !), and each segment carries start/end times. This is the default (NeMo’s punctuation-only segmentation) and needs no configuration. While streaming, each end-of-utterance closes a segment, now with timestamps.
You can additionally split on silence by setting segment_gap_threshold (NeMo’s segment_gap_threshold, in encoder frames; off by default). When set, a gap between two words wider than the threshold also starts a new segment. The value is in frames to match NeMo exactly; the backend converts it to seconds using the model’s frame stride (frame_sec, reported by the engine):
The backend can coalesce concurrent transcription requests into a single batched engine call, which improves throughput on GPU when many requests arrive at once. Batching is off by default (batch_max_size:1, one request at a time); raise it to opt in. Two options: knobs control it:
name:parakeet-110mbackend:parakeet-cppparameters:model:tdt_ctc-110m-f16.ggufoptions:- batch_max_size:8 # max requests coalesced into one batch (default 1 = off)- batch_max_wait_ms:15 # how long to wait to fill a batch, in ms (default 15)
By default each request runs on its own. Raise batch_max_size (for example 4 to 16) to enable batching; it pays off on GPU under concurrent load, where coalescing the per-step decode GEMMs across requests is a large throughput win. Leave it at 1 on CPU and for low-concurrency setups, where batching only adds latency. Batching only affects concurrent unary requests; streaming sessions always run on their own.
Moondream Ultra and Redux
Moondream publishes two derivatives of NVIDIA parakeet-tdt-0.6b-v3, Ultra and Redux. Both have a voice-activity-detection (VAD) head. The gallery has five entries, built from the GGUFs in mudler/parakeet-cpp-gguf:
Gallery entry
File
Runs on
parakeet-cpp-moondream-ultra-f16
ultra-f16.gguf
CPU and GPU
parakeet-cpp-moondream-ultra-q8_0
ultra-q8_0.gguf
CPU and GPU
parakeet-cpp-moondream-redux-packed
redux-packed.gguf
CPU only, offline only
parakeet-cpp-moondream-redux-f16
redux-f16.gguf
any backend, can stream
parakeet-cpp-moondream-redux-q8_0
redux-q8_0.gguf
any backend
The packed Redux file stores the encoder as ternary weights (213 MB). It cannot load on a GPU backend and cannot stream. If a GPU build fails to load it, check the backend log for the library message and use the redux-f16 or redux-q8_0 entry instead. The weights are CC-BY-4.0: credit Moondream and NVIDIA.
VAD-only slices
If you only need the VAD head, for the VAD endpoint or to cut audio before transcription, the same repository has two small files with the head cut out of the full model. The weights are not retrained, and the files cannot transcribe:
Gallery entry
File
Size
Cut from
parakeet-cpp-vad-moondream-redux
redux-vad.gguf
9.9 MB
Redux (213 MB packed to 1.4 GB)
parakeet-cpp-vad-moondream-ultra
ultra-vad-q8_0.gguf
6.0 MB
Ultra Q8_0
Measured by the parakeet.cpp author against loading a whole Redux or Ultra model: the files are 6 to 10 MB instead of 213 MB to 1.4 GB, load in a few milliseconds instead of 0.1 to 0.7 s, and use about 245 MiB peak memory for a 33 s clip instead of 0.6 to 1.6 GiB. The output is byte-identical to the full parent model, and the speed is the same as the parent’s head. A transcription request on a slice fails with an error. The slices load only with a parakeet.cpp build that includes VAD-only GGUF support, so an older backend build fails to load them. The weights are CC-BY-4.0: credit Moondream and NVIDIA.
With vad:true, long audio is cut at pauses found by the model’s VAD head into pieces of at most 30 seconds, and each piece is transcribed in turn. Word timestamps stay relative to the whole file. Audio of 30 seconds or less gives the same result as without the option. The gallery entries set it. Add it to your own model YAML like this:
name:moondream-ultrabackend:parakeet-cppparameters:model:ultra-q8_0.ggufoptions:- vad:true # cut long audio at pauses (default false); needs a model with a VAD head
vad:true applies to offline transcription only and bypasses dynamic batching, because the batched entry point has no VAD variant. Streaming is not affected. A model without a VAD head fails each request with model has no VAD head, and a libparakeet.so that is too old to export the VAD entry point fails the load. Remove the option for models that have no VAD head.
Cutting long audio with Silero (vad_model)
A model without a VAD head, such as parakeet-cpp-tdt-0.6b-v3 or a Nemotron model, can cut long audio with Silero VAD instead. Name a Silero GGUF in the vad_model option. The path is resolved against the models directory, like the other companion files. vad_model implies vad:
name:parakeet-v3-silerobackend:parakeet-cppparameters:model:parakeet-cpp/tdt-0.6b-v3-f16.ggufoptions:- vad_model:parakeet-cpp/silero-vad-f16.gguf # Silero GGUF that cuts long audio at pauses- vad_min_pause:0.3 # optional, seconds
The gallery entry parakeet-cpp-tdt-0.6b-v3-silero-vad installs both files with this configuration. Audio of 30 seconds or less is transcribed whole and the VAD does not run. vad:true alone keeps meaning “use the model’s own head”. With vad_model set, the Silero model is used even if the ASR model has a head.
The segmenter options below apply to both vad:true and vad_model. Each is optional; an unset value keeps the default of the detector in use, and a bad value fails the load:
Option
Unit
Meaning
vad_threshold
0 to 1
A frame is speech when its probability is at least this
vad_min_pause
seconds
A silence this long separates two pieces
vad_min_speech
seconds
Shorter speech runs are dropped
vad_max_segment
seconds
Cap on the length of a piece (default 30)
vad_trim
seconds
Each piece shrinks to its first and last speech frame plus this much. Default 0.3; 0 keeps the whole cuts, as before this option existed
vad_speech_pad (seconds) pads each region and only affects the VAD endpoint. vad_model needs a libparakeet.so that exports parakeet_capi_transcribe_path_json_vad_with; an older library fails the load with a message that names it.
Dropping noise words (guard_*)
A decode of noise or silence can contain words that no one said. An opt-in filter removes the words that stand alone or sit among low-confidence words, and the words that are only punctuation. It runs on the finished decode. It is off unless one of these options is set, and a bad value fails the load:
Option
Unit
Meaning
guard_min_local_conf
0 to 1
A word is dropped when the mean confidence of the words that start within guard_local_radius seconds of it, itself included, is below this. 0 is off. 0.5 is a good start; higher values also drop real words on some models
guard_local_radius
seconds, above 0
The window of that mean. Default 5
guard_drop_punct_only
true or false
Drop words that are only punctuation. A CTC model can emit a lone . on noise. Default false
The filter applies to offline transcription, and with vad:true or vad_model to each piece on its own. It bypasses dynamic batching, like vad:true. Streaming is not affected. Speech with confident words comes out the same as without the filter. The number of dropped words is written to the backend log at debug level; the transcription response has no field for it. The options need a libparakeet.so that exports parakeet_capi_transcribe_path_json_with; an older library fails the load with a message that names it.
Bundle GGUF files (several models in one file)
A bundle is one GGUF file that holds several models, called components. Each component keeps its own licence. The backend opens the components it needs from the one file, so a single model YAML can serve transcription, VAD, diarization, speaker naming and sound events. A bundle needs a libparakeet.so from parakeet.cpp with bundle support (pin 781a973 or newer); the format is described in the parakeet.cpp bundle documentation. Single-model files and every existing option work as before.
Parakeet TDT 0.6B v3 (Q8_0), plus the same four components
the same, with the multilingual 0.6B model
parakeet-cpp-bundle-moondream-redux
215 MB
Moondream Redux (packed ternary), Silero VAD (F16)
transcription and VAD; CPU only and offline only
The component that each role uses, and the option that picks another one:
Role
Component used
Option
Transcription
the only asr component
bundle_asr:<name> picks one when the bundle has several
VAD (/v1/vad, and vad:true for long audio)
the vad (Silero) component, loaded with no option; without one the VAD head of the ASR model
vad_component:<name> picks one, and implies vad:true
Diarization
the diar component, only when asked for
diar_component:<name>
Sound events
the ced component, only when asked for
sound_component:<name>
Speaker naming
the voice component, only when asked for
speaker_component:<name> (needs a diarization component)
Voice embedding and verification (/v1/voice/*, the realtime voice_recognition stage)
the voice component, only when asked for
speaker_component:<name>; declare speaker_recognition in known_usecases. Needs a libparakeet.so with parakeet_capi_speaker_embed_pcm. See Voice Recognition
speaker_component: also names registered speakers: LocalAI sends the voices from /v1/voice/register to the bundle’s speaker component, as it does for speaker_model:. This works in /v1/audio/diarization and in realtime live transcription, and it needs no speaker_model:. speaker_threshold, speaker_margin and speaker_strict apply too. Only voices that carry an encoder fingerprint (voices enrolled from speaker_profiles) and voices with no tag at all are used by default. A voice registered with a tag only matches through speaker_tag:. See Voice Recognition.
A *_component option without the matching companion option takes the component from the model file itself. The companion options (diarization_model:, sound_model:, speaker_model:, vad_model:, asr_model:) can also name a bundle file, even the same file as the model: the only component of the wanted kind is used, and the *_component option picks one when there are several. This YAML loads the same file for four roles:
name:parakeet-bundlebackend:parakeet-cppparameters:model:parakeet-cpp/parakeet-bundle-small.ggufoptions:- vad:true # cut long audio at pauses, with the Silero component- diar_component:diar # same as diarization_model:parakeet-cpp/parakeet-bundle-small.gguf- sound_component:ced- speaker_component:voice
A role that the bundle cannot fill fails with a message that lists the components, for example parakeet-cpp: diarization_model needs a "diar" component, but the bundle "<path>" has none (components: asr (asr), vad (vad)). A request for a role the loaded model does not have (diarization from a bundle without a diar component) returns parakeet-cpp: model is not a diarization model (the model file is a bundle without a "diar" component; ...). A *_component option on a file that is not a bundle, or on a library without bundle support, fails the load.
Licences: a bundle has no single licence, so the gallery entries use license: other. The licence, source and credit of every component are in the file header, and the NOTICE file next to each bundle in the repository (NOTICE-<bundle>.txt) has the credits and the full licence texts. Keep it with any copy of the file you pass on.
Component
Licence
Credit
Parakeet TDT+CTC 110M, Parakeet TDT 0.6B v3
CC-BY-4.0
NVIDIA
Moondream Redux
CC-BY-4.0
Moondream, derived from Parakeet TDT 0.6B v3 by NVIDIA
Nemotron-3-Diarization
OpenMDW-1.1
NVIDIA
CED-Small
Apache-2.0, as stated on the model card
Heinrich Dinkel et al., Xiaomi (mispeech)
WeSpeaker ResNet34-LM
CC-BY-4.0
the WeSpeaker project
Silero VAD
MIT
Silero Team
The licence of the CED weights is not consistent upstream: the model card says Apache-2.0, the upstream code repository is GPL-3.0 and the original checkpoint records say CC-BY-4.0. The file here is converted, not trained, and follows the model card. The weights of all components were converted to GGUF, and quantised where the table shows it; nothing was retrained.
See also
Audio Transform - clean up the audio (echo cancellation, noise suppression, dereverberation) before passing it to a transcription model.
LocalAI returns 404 when the requested model is not installed. Models without
voice metadata do not appear in the unfiltered response.
The Instructions field in the Text to Speech studio maps to the optional
instructions property on /v1/audio/speech. Use it to describe delivery,
such as tone or pace:
Backend support for speech instructions varies. Backends that do not support
this control may ignore it.
Voice Library
Every user who may use speech can keep reusable voice-cloning references of their own, and administrators manage all of them. Use the Library tab of the Voice add-on (Add-ons → Voice) in the LocalAI WebUI. (Recognition, the first tab of that page, is a separate feature: voiceprints for recognising who is speaking. See Voice recognition.) The library replaces per-model filesystem and YAML setup for supported cloning backends:
Select Add a speech voice and upload or record a clear reference clip. A speech voice can also be made while enrolling a speaker, from the enrol sheet.
Enter the exact words spoken in the clip. Add more audio/transcript pairs when the personality needs more examples.
Confirm that you have permission to clone the voice, then save the profile.
Open Text to Speech, choose a model marked Cloning ready, and select the saved voice.
The browser converts uploads and recordings to mono, 24 kHz, 16-bit PCM WAV so the same profile works across compatible backends. A profile can contain up to ten ordered references. Each clip must be between 1 and 120 seconds and no larger than 50 MiB; 6-30 seconds of clean audio is recommended. Profile audio is private biometric source material: LocalAI stores it below its configured data path, serves previews only to authenticated TTS users who may see that profile, and never returns its filesystem path.
Voice profile API
The WebUI uses the following endpoints. Every route needs access to the audio speech feature (audio_speech).
Method
Endpoint
Purpose
GET
/api/voice-profiles
List the profiles you may use: your own and the instance-wide ones. An administrator sees all.
POST
/api/voice-profiles
Create a profile from multipart form data or JSON with base64 audio. The profile belongs to you.
GET
/api/voice-profiles/{id}/audio
Stream the authenticated WAV preview, including range requests.
DELETE
/api/voice-profiles/{id}
Permanently delete a profile of yours.
Who owns a profile
A profile has an owner: the user who created it. These rules apply to the endpoints above, to voice in /v1/audio/speech and /tts, and to the voice of a realtime session:
You see, preview and speak with your own profiles and with the instance-wide ones.
An instance-wide profile has no owner. Profiles an administrator creates are instance-wide, and so are profiles stored before ownership existed. Every user can use them; only an administrator can delete them (other users get 403).
You can delete your own profiles. An administrator can list, use and delete all profiles.
The profile of another user answers 404, never 403, in every endpoint and in speech requests, so nobody can learn that it exists.
A user who is not an administrator may own at most 20 profiles. A request over the limit answers 409. The limit is a constant, not a setting. Each clip is limited to 50 MiB, as before. The reference audio of one such user is also limited to 100 MiB in total; a request over it answers 409. Administrators have neither limit. A profile that an administrator creates is visible to all users.
A user who is not an administrator cannot set voice to a file path (a value with /, \ or ..): the request answers 400. They use a voice of the model or a localai://voice-profiles/<id> voice. Administrators, and servers without accounts, may still give a path.
A server without accounts (authentication off) has no owners: every profile is instance-wide, as before.
The profiles are files below the data path of the instance (voice-profiles/, one folder per profile; owner_id in its profile.json). They follow the data path: frontends that share a data path share the profiles, and frontends with separate data paths each have their own library, as before. The profile limit is counted on the files under a lock of one process, so two frontends that create profiles for the same user at the same moment can exceed it by a few.
For example, you can create a profile without the WebUI:
curl http://localhost:8080/api/voice-profiles \
-F 'name=Documentary narrator'\
-F 'language=en-US'\
-F 'transcript=The exact words spoken in this reference.'\
-F 'consent_confirmed=true'\
-F 'audio=@reference.wav;type=audio/wav'
Repeat transcript and audio in matching order to create a multi-reference personality:
The response includes an opaque voice reference such as localai://voice-profiles/550e8400-e29b-41d4-a716-446655440000. Pass that value as voice to either TTS-compatible endpoint:
curl http://localhost:8080/v1/audio/speech \
-H 'Content-Type: application/json'\
-d '{
"model": "qwen3-tts-base",
"input": "This sentence will use the saved voice.",
"voice": "localai://voice-profiles/550e8400-e29b-41d4-a716-446655440000"
}' --output speech.wav
LocalAI resolves the opaque reference only for models that advertise voice-cloning support. Existing named speakers, backend-specific voice IDs, and explicit model YAML voice configuration remain available for models and advanced workflows that do not use the library.
The Voice Library uses the same server-side capability resolver for installed models and gallery recommendations. Administrators can inspect the currently configured galleries without maintaining a separate backend list:
Each returned model includes a non-null voice_cloning contract. Variant checks are applied before the model is returned, so TTS-only CustomVoice, VoiceDesign, or preset-prompt variants are not offered as reference-audio models. When the WebUI detects that no compatible model is installed, it uses this response to offer direct installation.
Model configuration
Voice Library support is automatic for known backends and model variants. A custom model can override that detection with tts.voice_cloning:
name:private-qwen-basebackend:qwen3-tts-cppparameters:model:private/qwen-talker-checkpoint.ggufknown_usecases:- ttstts:# Optional: omit this for automatic backend and variant detection.voice_cloning:true# Optional model-wide fallback when a request does not select a saved profile.audio_path:voices/default-reference.wavoptions:- tokenizer:private/qwen-tokenizer.gguf
tts.voice_cloning has three states:
Value
Behavior
omitted
Detect support from the backend plus name, parameters.model, and compatibility options. This is recommended for gallery models.
true
Advertise Voice Library support for a custom-named variant of a backend that LocalAI already knows can clone voices. This cannot add cloning to an unsupported backend.
false
Hide the model from Voice Library compatibility results and reject localai://voice-profiles/... references for it. Backend-specific named voices and manual reference paths remain available.
The older options: ["voice_cloning:true"] and options: ["voice_cloning:false"] spellings remain accepted for compatibility. Prefer tts.voice_cloning; generic options may be forwarded to a backend, whereas the typed field is consumed only by LocalAI.
Reference selection follows this order:
A request voice, including a saved localai://voice-profiles/... URI.
The model’s tts.voice default.
The model’s tts.audio_path reference-audio fallback.
A backend-specific default voice or option.
When a saved profile is selected, LocalAI supplies its ordered private WAV and transcript pairs to Fish Speech and audio.cpp. Other cloning backends receive the first pair, which preserves their existing single-reference behavior. LocalAI does not rewrite the model YAML or copy recordings into the model directory.
Realtime pipeline default
Set tts.voice on a realtime pipeline model to use a saved Voice Library profile as the session default:
If the same update changes model, the explicit audio.output.voice value takes precedence over the new model’s tts.voice default. The selected model must support Voice Library cloning.
Reference-audio cloning models served by these dedicated backends.
qwen-tts, qwen3-tts-cpp, vllm-omni
Base or VoiceClone variants. CustomVoice and VoiceDesign variants are not raw reference-audio models.
llama-cpp
Models that declare known_usecases: [tts], which the Qwen3-TTS gallery entries (qwen3-tts-llamacpp, qwen3-tts-llamacpp-q4) do. A reference clip is required, since the Base checkpoints have no built-in speaker. Ordinary GGUF chat and vision models served by this backend are excluded.
vibevoice-cpp
1.5B reference-WAV variants. The realtime 0.5B preset-prompt model is excluded.
coqui
XTTS and YourTTS variants.
crispasr
F5-TTS variants. ASR, Piper, Orpheus, and other CrispASR model families are excluded.
This table describes the built-in resolver, not a frontend allowlist. Gallery entries and installed configs are evaluated by the server, and tts.voice_cloning can make a verified custom filename explicit.
Streaming TTS
LocalAI supports streaming TTS generation, allowing audio to be played as it’s generated. This is useful for real-time applications and reduces latency.
To enable streaming, add "stream": true to your request:
curl http://localhost:8080/tts -H "Content-Type: application/json" -d '{
"input": "Hello world, this is a streaming test",
"model": "voxcpm",
"stream": true
}'| aplay
The audio will be streamed chunk-by-chunk as it’s generated, allowing playback to start before generation completes. This is particularly useful for long texts or when you want to minimize perceived latency.
You can also pipe the streamed audio directly to audio players like aplay (Linux) or save it to a file:
# Stream to aplay (Linux)curl http://localhost:8080/tts -H "Content-Type: application/json" -d '{
"input": "This is a longer text that will be streamed as it is generated",
"model": "voxcpm",
"stream": true
}'| aplay
# Stream to a filecurl http://localhost:8080/tts -H "Content-Type: application/json" -d '{
"input": "Streaming audio to file",
"model": "voxcpm",
"stream": true
}' > output.wav
Note: Streaming TTS is implemented by the audio-cpp, crispasr, llama-cpp, magpie-tts-cpp, moss-tts-cpp, omnivoice-cpp, qwen3-tts-cpp, sherpa-onnx, supertonic, vibevoice-cpp and voxcpm backends. Other backends will fall back to non-streaming mode if streaming is not supported.
Backends
🐸 Coqui
Required: Don’t use LocalAI images ending with the -core tag,. Python dependencies are required in order to use this backend.
Coqui works without any configuration, to test it, you can run the following curl command:
    curl http://localhost:8080/tts -H "Content-Type: application/json" -d '{
        "backend": "coqui",
        "model": "tts_models/en/ljspeech/glow-tts",
        "input":"Hello, this is a test!"
        }'
You can use the env variable COQUI_LANGUAGE to set the language used by the coqui backend.
You can also use config files to configure tts models (see section below on how to use config files).
Fish Speech
Fish Speech models accept the compile backend option. Enabling it can improve
inference performance on CUDA hardware, but the first request after loading the
model includes the torch.compile warmup cost:
backend:fish-speechoptions:- compile:true
When compilation is enabled, the backend uses the CUDA toolkit’s executable
ptxas from $CUDA_HOME/bin (defaulting to /usr/local/cuda/bin) instead of
the copy bundled with Triton. This allows newer GPU architectures supported by
the installed CUDA toolkit to compile kernels. Set TRITON_PTXAS_PATH on the
backend explicitly to select a different assembler.
aplay is a Linux command. You can use other tools to play the audio file.
The model name is the filename with the extension.
The model name is case sensitive.
LocalAI must be compiled with the GO_TAGS=tts flag.
Transformers-musicgen
LocalAI also has experimental support for transformers-musicgen for the generation of short musical compositions. Currently, this is implemented via the same requests used for text to speech:
Future versions of LocalAI will expose additional control over audio generation beyond the text prompt.
ACE-Step
ACE-Step 1.5 is a music generation model that can create music from text descriptions, lyrics, or audio samples. It supports both simple text-to-music and advanced music generation with metadata like BPM, key scale, and time signature.
Setup
Install the ace-step-turbo model from the Model gallery or run local-ai models install ace-step-turbo.
Usage
ACE-Step supports two modes: Simple mode (text description + vocal language) and Advanced mode (caption, lyrics, BPM, key, and more).
Simple mode:
curl http://localhost:8080/v1/audio/speech -H "Content-Type: application/json" -d '{
  "model": "ace-step-turbo",
  "input": "A soft Bengali love song for a quiet evening",
  "vocal_language": "bn"
}' --output music.flac
Advanced mode (using the /v1/sound-generation endpoint):
curl http://localhost:8080/v1/sound-generation -H "Content-Type: application/json" -d '{
  "model": "ace-step-turbo",
  "caption": "A funky Japanese disco track",
  "lyrics": "[Verse 1]\n...",
  "bpm": 120,
  "keyscale": "Ab major",
  "language": "ja",
  "duration_seconds": 225
}' --output music.flac
Music and sound generation API (/v1/sound-generation)
The /v1/sound-generation endpoint is compatible with the ElevenLabs sound generation API and can produce music, sound effects, and other audio content. It responds with a binary audio file and the appropriate Content-Type header (for example audio/wav, audio/mpeg, audio/flac, or audio/ogg). The request body is JSON and supports two usage modes.
Each generated sound has a unique filename. The filename remains unique when
LocalAI changes its extension to match the audio format, so later generations
do not overwrite earlier recordings in the WebUI history.
Simple mode:
Parameter
Type
Required
Description
model_id
string
Yes
Model identifier (for example ace-step-turbo)
text
string
Yes
Audio description or prompt
instrumental
bool
No
Generate instrumental audio (no vocals)
vocal_language
string
No
Language code for vocals (for example bn, ja)
Advanced mode:
Parameter
Type
Required
Description
model_id
string
Yes
Model identifier (for example ace-step-turbo)
text
string
Yes
Text prompt or description
duration_seconds
float
No
Target duration in seconds
prompt_influence
float
No
Temperature / prompt influence parameter
do_sample
bool
No
Enable sampling
think
bool
No
Enable extended thinking for generation
caption
string
No
Caption describing the audio
lyrics
string
No
Lyrics for the generated audio
bpm
int
No
Beats per minute
keyscale
string
No
Musical key/scale (for example Ab major)
language
string
No
Language code
vocal_language
string
No
Vocal language (fallback if language is empty)
timesignature
string
No
Time signature (for example 4)
instrumental
bool
No
Generate instrumental audio (no vocals)
params
object
No
Backend-specific options with string keys and string values
Use params to pass backend-specific string options that do not have fixed request
fields. Every value in params must be a string. Existing fixed fields remain
authoritative when a fixed field and params contain the same option.
The audio-cpp backend uses a nonempty caption as the default style option.
An explicit params.style takes precedence, including an empty string. In
Studio → Sound, select Advanced mode and enter the musical style in Caption
and the song text in Lyrics to use YuE2.
Install the YuE2 gallery model and generate a song:
Error responses: 400 for a missing or invalid model or request parameters, and 500 for a backend error during sound generation.
AudioLDM 2
AudioLDM 2 generates sound effects,
music, and speech from a text description. Install the gallery model:
local-ai models install audioldm2
Generate a WAV file through the sound-generation endpoint:
curl http://localhost:8080/v1/sound-generation \
-H "Content-Type: application/json"\
-d '{
"model_id": "audioldm2",
"text": "Waves breaking on a rocky beach during a distant thunderstorm",
"duration_seconds": 10
}' --output storm.wav
AudioLDM 2 uses the AudioLDM2Pipeline from the diffusers backend. The
duration_seconds field maps to the pipeline’s audio_length_in_s option, and
prompt_influence maps to guidance_scale.
Configuration
You can configure ACE-Step models with various options:
name:ace-step-turbobackend:ace-stepparameters:model:acestep-v15-turboknown_usecases:- sound_generation- ttsoptions:- "device:auto"- "use_flash_attention:true"- "init_lm:true"# Enable LLM for enhanced generation- "lm_model_path:acestep-5Hz-lm-0.6B"# or acestep-5Hz-lm-4B- "lm_backend:pt"# or vllm- "temperature:0.85"- "top_p:0.9"- "inference_steps:8"- "guidance_scale:7.0"
VibeVoice
VibeVoice-Realtime is a real-time text-to-speech model that generates natural-sounding speech from precomputed voice presets.
Setup
Install the vibevoice model in the Model gallery or run local-ai models install vibevoice.
Usage
Use the tts endpoint by specifying the vibevoice backend:
The Python vibevoice realtime 0.5B model uses .pt voice preset files. You can configure a model with a specific preset:
name:vibevoicebackend:vibevoiceparameters:model:microsoft/VibeVoice-Realtime-0.5Btts:voice:"Frank"# or use audio_path to specify a .pt file path# Available English voices: Carter, Davis, Emma, Frank, Grace, Mike
Note
The realtime 0.5B preset model is not advertised to the Voice Library because it does not accept a raw reference WAV per request. For Voice Library profiles, use a vibevoice-cpp 1.5B reference-WAV model; LocalAI detects the 1.5B variant automatically, or a custom name can set tts.voice_cloning: true.
OmniVoice (omnivoice-cpp backend) is a native C++ / GGML text-to-speech engine. It supports voice cloning (from reference audio plus its transcript), voice design (steering the voice with attribute keywords such as gender, age, pitch, style, volume, and emotion), and streaming synthesis. Output is 24kHz mono audio and it covers 646 languages.
Setup
Install the omnivoice-cpp model in the Model gallery or run local-ai models install omnivoice-cpp. A higher-quality BF16 variant is available as omnivoice-cpp-hq (the default omnivoice-cpp ships Q8_0 GGUFs).
Usage
Use the speech endpoint by specifying the omnivoice-cpp backend:
curl http://localhost:8080/v1/audio/speech -H "Content-Type: application/json" -d '{
"model": "omnivoice-cpp",
"input": "Hello world, this is a test."
}'| aplay
Voice cloning
Pass a reference audio file via the voice parameter and its transcript via the ref_text generation parameter:
curl http://localhost:8080/v1/audio/speech -H "Content-Type: application/json" -d '{
"model": "omnivoice-cpp",
"input": "Hello world, this is a test.",
"voice": "path/to/reference_audio.wav",
"params": { "ref_text": "This is the transcript of the reference audio." }
}'| aplay
You can also pin a default cloned voice in the model config so callers do not have to pass it on every request. Both tts.voice and tts.audio_path are honored as the reference audio (a per-request voice overrides them); paths are resolved relative to the model directory:
name:omnivoice-cppbackend:omnivoice-cppparameters:model:omnivoice-cpp/omnivoice-base-Q8_0.gguftts:voice_cloning:true# optional explicit declaration; gallery models are auto-detectedaudio_path:"voices/my_reference.wav"# default cloning reference (or use tts.voice)options:- "tokenizer:omnivoice-cpp/omnivoice-tokenizer-Q8_0.gguf"
Voice design
Steer the synthesized voice with attribute keywords (gender, age, pitch, style, volume, emotion) by passing an instructions string per request:
curl http://localhost:8080/v1/audio/speech -H "Content-Type: application/json" -d '{
"model": "omnivoice-cpp",
"input": "Hello world, this is a test.",
"instructions": "female young high soft emotion:happy"
}'| aplay
Configuration
The backend loads the base GGUF from parameters.model and its tokenizer from the tokenizer: option. A few optional generation knobs are available as options:
name:omnivoice-cppbackend:omnivoice-cppparameters:model:omnivoice-cpp/omnivoice-base-Q8_0.ggufoptions:- "tokenizer:omnivoice-cpp/omnivoice-tokenizer-Q8_0.gguf"- "use_fa:true"# enable flash attention- "clamp_fp16:true"# clamp activations for fp16 stability- "seed:42"# deterministic generation- "denoise:true"# denoise the generated audio
A per-request seed can also be supplied through the params map alongside ref_text.
Duration and postprocessing
For omnivoice-cpp, set these request-local controls in params, not as top-level fields:
duration accepts a finite numeric string of seconds greater than zero and at most 30, inclusive. Whitespace, empty strings, and nonfinite values are invalid.
The backend uses max(1, floor(seconds * 25)) generation frames. Each frame represents 40 milliseconds at the bundled codec rate. Thus, 2.5 selects 62 frames; tiny positive values select one frame.
postprocess accepts only the exact strings "true" and "false". Buffered synthesis accepts either value, with or without duration.
A supplied duration forces single-shot generation and bypasses chunking. The 30-second cap is a conservative wrapper resource policy, aligned with the engine’s default chunk threshold. It is not an engine positional limit or a guarantee of available memory or successful synthesis.
Duration controls generation frames, not playback speed or guaranteed final WAV duration. Buffered postprocessing can trim or pad audio. With postprocess="false", buffered output preserves the raw decoded frame length; reference loudness matching remains active. Quantization does not guarantee perceptual accuracy.
Streaming accepts duration and explicit postprocess="true". It rejects postprocess="false" before reference reads, native synthesis, or audio output because the streaming engine always postprocesses audio.
Pocket TTS
Pocket TTS is a lightweight text-to-speech model designed to run efficiently on CPUs. It supports voice cloning through HuggingFace voice URLs or local audio files.
Setup
Install the pocket-tts model in the Model gallery or run local-ai models install pocket-tts.
Usage
Use the tts endpoint by specifying the pocket-tts backend:
curl http://localhost:8080/tts -H "Content-Type: application/json" -d '{
     "model": "pocket-tts",
     "input":"Hello world, this is a test."
   }' | aplay
Voice cloning
Pocket TTS supports voice cloning through built-in voice names, HuggingFace URLs, or local audio files. You can configure a model with a specific voice:
name:pocket-ttsbackend:pocket-ttstts:voice:"azelma"# Built-in voice name# Or use HuggingFace URL: "hf://kyutai/tts-voices/alba-mackenna/casual.wav"# Or use local file path: "path/to/voice.wav"# Available built-in voices: alba, marius, javert, jean, fantine, cosette, eponine, azelma
To make a reference recording the model-wide fallback, use tts.audio_path. The gallery model is detected automatically; tts.voice_cloning is only needed when you want an explicit declaration:
Supported values depend on the installed pocket-tts version; current releases accept english, french, german, italian, spanish, portuguese and dutch, plus variants such as french_24l and english_2026-04. The built-in voice names are resolved against the selected language model.
Qwen3-TTS
Qwen3-TTS is a high-quality text-to-speech model that supports three modes: custom voice (predefined speakers), voice design (natural language instructions), and voice cloning (from reference audio).
Setup
Install the qwen-tts model in the Model gallery or run local-ai models install qwen-tts.
C++ / GGML gallery variants
For a native backend, install one of the Base variants qwen3-tts-cpp, qwen3-tts-cpp-0.6b-base-q4, qwen3-tts-cpp-1.7b-base, or qwen3-tts-cpp-1.7b-base-q4. These variants accept saved Voice Library profiles and are advertised automatically. Gallery entries containing customvoice or voicedesign provide their respective Qwen modes but are intentionally excluded from raw reference-audio cloning.
A private Qwen C++ Base conversion with an opaque filename can declare the capability explicitly. The tokenizer GGUF can sit beside the talker GGUF for automatic discovery:
By default qwen3-tts-cpp synthesizes one request at a time. Set max_batch to let qwentts.cpp batch up to N concurrent /v1/audio/speech requests (streaming or not) into shared decode steps; further requests queue inside the engine:
options:- max_batch:4
The contributor measured four concurrent streaming requests through LocalAI on an RTX 5060 Ti (1.7B Base Q4_K_M): the first audio arrived after 0.31–0.33 seconds for all four with max_batch:4, compared with 0.30, 0.94, 1.48 and 2.02 seconds with max_batch:1. VRAM grows with max_batch (roughly 2.6 GB at 1, 6 GB at 4, 10.5 GB at 8 for that talker).
At load the backend attempts concurrent warmup to reduce graph initialization delays; this does not guarantee that every batch width is warmed. CustomVoice and VoiceDesign models reject these generic warmup requests because they require a speaker or instruction, so the backend logs a warning and continues loading. max_batch_warmup:false skips warmup.
Incremental synthesis (TTSLive, used by a realtime pipeline with streaming.tts: true) requires max_batch:1. On ROCm before 10.1 with RDNA4 (gfx1201), batched requests can hang the GPU in hipBLASLt (fixed in ROCm 10.1 by ROCm/rocm-libraries#8909); on those stacks add env: {ROCBLAS_USE_HIPBLASLT: "0"} to the model configuration.
llama.cpp gallery variants
llama.cpp gained native Qwen3-TTS support in ggml-org/llama.cpp#26254, so the llama-cpp backend can serve it on the same accelerator matrix it already uses for text generation: CUDA, ROCm, SYCL, Vulkan and Metal.
Install qwen3-tts-llamacpp (Q8_0 backbone) or qwen3-tts-llamacpp-q4 (Q4_K_M backbone) from the Model gallery, or run local-ai models install qwen3-tts-llamacpp-q4.
These models load two files: the backbone GGUF and a multimodal projector holding the speaker encoder and code predictor. A hand-written configuration must point at both:
known_usecases: [tts] is not optional here. It is how LocalAI tells a Qwen3-TTS checkpoint apart from the text and vision GGUFs the same backend serves: without it the model is treated as a chat model, its projector is read as a vision tower, and Voice Library profiles are refused.
Importing such a repo through the Models page or local-ai models import writes that declaration for you. The importer reads the projector’s header and recognises the speech-synthesis pipeline, so ggml-org/Qwen3-TTS-12Hz-1.7B-Base-GGUF imports as a TTS model rather than as a chat model with a vision projector.
The upstream checkpoints are Base variants with no built-in speaker, so voice is required on every request. Pass either a path to a reference clip or a saved Voice Library profile. A request without one is rejected rather than served in an arbitrary voice:
curl http://localhost:8080/tts -H "Content-Type: application/json" -d '{
  "model": "qwen3-tts-llamacpp",
  "input": "Hello world, this is a test.",
  "voice": "voices/my-reference.wav"
}' > output.wav
Output is always 24 kHz mono 16-bit WAV. Streaming works on this backend, so "stream": true returns audio chunk by chunk as it is generated.
Set language to an ISO 639-1 code to pin the output language. The supported codes are zh, en, de, it, pt, es, ja, ko, fr and ru.
Three optional knobs travel in params: top_k and top_p adjust sampling, and max_frames caps how much audio a single request may generate. The model runs at 12.5 frames per second, so one frame is 0.08 seconds and the maximum duration in seconds is max_frames / 12.5. Leave it unset for the engine default of 512 frames, which is 40.96 seconds.
max_frames exists because generation occasionally fails to stop on its own. The model normally ends an utterance by emitting its end-of-speech token, but once in a while it does not, and the request then runs to the cap and returns far more audio than the text called for. It is uncommon, and it happens more on short inputs than on long ones. If you are synthesising predictable text and want a hard bound, allow roughly 8 frames per word: about 100 frames (8 seconds) for a short sentence, about 300 frames (24 seconds) for a paragraph.
curl http://localhost:8080/tts -H "Content-Type: application/json" -d '{
  "model": "qwen3-tts-llamacpp",
  "input": "Hello world, this is a test.",
  "voice": "voices/my-reference.wav",
  "params": {"max_frames": "100"}
}' > output.wav
This backend accepts but ignores instructions, speed and sample_rate. The Base checkpoints have no expressive-style or rate control, and the output rate is fixed at 24 kHz.
Note that qwen3-tts-cpp (qwentts.cpp) remains available and is unaffected. It is a separate, independently maintained path to the same family of weights, not something this replaces.
Usage
Use the tts endpoint by specifying the qwen-tts backend:
curl http://localhost:8080/tts -H "Content-Type: application/json" -d '{
     "model": "qwen-tts",
     "input":"Hello world, this is a test."
   }' | aplay
Language
You can hint the synthesis language with the language request field:
Supported languages: en (English), zh (Chinese), ru (Russian), ja (Japanese), ko (Korean), de (German), fr (French), es (Spanish), it (Italian), pt (Portuguese).
The value is matched case-insensitively and accepts a few forms for convenience:
the two-letter code (fr, FR)
a locale/region form, whose region is ignored (fr-FR, pt_BR, zh-Hans → fr/pt/zh)
the English full name (french, Portuguese)
If the field is omitted or the value isn’t one of the supported languages, the backend defaults to English.
Custom Voice Mode
Qwen3-TTS supports predefined speakers. You can specify a speaker using the voice parameter:
curl http://localhost:8080/tts -H "Content-Type: application/json" -d '{
     "model": "qwen-tts-design",
     "input":"Hello world, this is a test."
   }' | aplay
Per-request instructions
Instead of (or in addition to) the static YAML instruct option, you can pass an
instructions string per request. It maps to the OpenAI
instructions field
and takes precedence over the YAML option when set, falling back to it when empty. This lets
a single model config serve a different emotion (CustomVoice) or a different designed voice
(VoiceDesign) on every request - useful for roleplay/narration clients that need many voices:
curl http://localhost:8080/v1/audio/speech -H "Content-Type: application/json" -d '{
     "model": "qwen-tts-design",
     "input": "Hello world, this is a test.",
     "instructions": "A calm, low-pitched elderly storyteller with a warm tone."
   }' | aplay
Backends that do not support style/voice instructions simply ignore the field.
You can also pass backend-specific generation parameters per request via the LocalAI
params extension (a string-to-string map; values are coerced to the backend’s expected
types). For example, with the Chatterbox backend:
curl http://localhost:8080/v1/audio/speech -H "Content-Type: application/json" -d '{
     "model": "chatterbox",
     "input": "Hello world, this is a test.",
     "params": { "exaggeration": "0.7", "cfg_weight": "0.3", "temperature": "0.8" }
   }' | aplay
Voice Clone Mode
Voice Clone allows you to clone a voice from reference audio. Configure the model with an AudioPath and optional ref_text:
name:qwen-tts-clonebackend:qwen-ttsparameters:model:Qwen/Qwen3-TTS-12Hz-1.7B-Basetts:voice_cloning:true# optional for this Base model; useful when a private checkpoint has an opaque nameaudio_path:"path/to/reference_audio.wav"# Reference audio fileoptions:- "ref_text:This is the transcript of the reference audio."- "x_vector_only_mode:false"# Set to true to use only speaker embedding (ref_text not required)
You can also use URLs or base64 strings for the reference audio. The backend automatically detects the mode based on available parameters (AudioPath → VoiceClone, instruct option → VoiceDesign, voice parameter → CustomVoice).
Then use the model:
curl http://localhost:8080/tts -H "Content-Type: application/json" -d '{
     "model": "qwen-tts-clone",
     "input":"Hello world, this is a test."
   }' | aplay
Multi-Voice Clone Mode
Qwen3-TTS also supports loading multiple voices for voice cloning, allowing you to select different voices at request time. Configure multiple voices using the voices option:
The voices option accepts a JSON array where each voice entry must have:
name: The voice identifier (used in API requests)
audio: Path to the reference audio file (relative to model directory or absolute)
ref_text: Path to the reference text file for the audio it is paired with
Then use the model with voice selection:
curl http://localhost:8080/tts -H "Content-Type: application/json" -d '{
"model": "qwen-tts-multi-voice",
"input":"Hello world, this is Jane speaking.",
"voice": "jane"
}'| aplay
# Switch to a different voicecurl http://localhost:8080/tts -H "Content-Type: application/json" -d '{
"model": "qwen-tts-multi-voice",
"input":"Hello world, this is John speaking.",
"voice": "john"
}'| aplay
Voice Selection Priority:
voice parameter in the API request (highest priority)
voice option in the model configuration
Error if voice is not found among configured voices
Error Handling:
If you request a voice that doesn’t exist in the voices list, the API will return an error with a list of available voices:
{"error":"Voice 'unknown' not found. Available voices: jane, john"}
Backward Compatibility:
The multi-voice mode is backward compatible with existing single-voice configurations. Models using audio_path in the tts section will continue to work as before.
You can also use a config-file to specify TTS models and their parameters.
In the following example, a custom config loads xtts_v2 with a default cloning reference and language.
For XTTS/YourTTS, tts.audio_path is the default cloning reference and a saved Voice Library profile overrides it per request. Other Coqui model families are not advertised as Voice Library-compatible unless they match the supported variant rules or are explicitly verified with tts.voice_cloning: true.
With this config, you can now use the following curl command to generate a text-to-speech audio file:
curl -L http://localhost:8080/tts \
-H "Content-Type: application/json"\
-d '{
"model": "xtts_v2",
"input": "Bonjour, je suis Ana Florence. Comment puis-je vous aider?"
}'| aplay
audio.cpp
audio.cpp is a multi-family GGML audio engine, so
one installed backend covers TTS (supertonic, vibevoice, voxcpm2, fish_audio,
pocket_tts, omnivoice, higgs_audio_tts), voice cloning (chatterbox, index_tts2,
irodori_tts, moss_tts_local, moss_tts_nano) and voice design (qwen3_tts, irodori_tts), alongside ASR, VAD,
diarization and separation.
Higgs Audio v3 is available directly from the model gallery as
audio-cpp-higgs-audio-v3. It uses the Q8_0 GGUF validated by audio.cpp and supports
expressive multilingual TTS and zero-shot voice cloning. For cloning, pass the path to a
server-local WAV file in the OpenAI voice field. Use only reference audio for which you
have the necessary rights and consent, and review the model’s research and non-commercial
license before deployment.
The family is read from the GGUF’s own metadata, so family: is only needed for a
safetensors file or a package directory. Sending a speaker reference clip routes the
request to the family’s voice-cloning task automatically, and supplying instructions routes
it to voice design, where the family supports them. Cloning-only families such as
chatterbox advertise no plain TTS task, so every request to them must carry a reference
clip. See the
audio.cpp backend page for the full option list,
including the load. and session. namespaces and the supertonic packaging caveat.
NeMo-Speech.cpp (MagpieTTS)
NeMo-Speech.cpp is NVIDIA’s C++/ggml runtime
for the Nemotron Speech models. Its magpietts family synthesizes speech through a
NanoCodec decoder, and the same installed backend also covers transcription, diarization
and translation.
The codec and the tokenizer directory are both required. Both are discovered from the
model’s own directory when left unset: a sibling file whose name contains nanocodec and
a sibling directory named extracted. MagpieTTS conditions on a speaker rather than on a
prose style, so voice selects a speaker index or a voice name and instructions has no
equivalent. See the NeMo-Speech.cpp backend
page for the full option list and the conversion steps.
LFM3-Audio (llama.cpp, experimental)
LFM3-Audio-2B synthesises speech through the llama-cpp backend. Install the gallery entry lfm3-audio-2b (or lfm3-audio-2b-q8). Its voices are female (the default) and male. The language field takes a language code, and the default is en. The model uses the sampling defaults stored in its GGUF files. This needs a llama.cpp build with LFM3-Audio support.
Response format
To provide some compatibility with OpenAI API regarding response_format, ffmpeg must be installed (or a docker image including ffmpeg used) to leverage converting the generated wav file before the api provide its response.
Warning regarding a change in behaviour. Before this addition, the parameter was ignored and a wav file was always returned, with potential codec errors later in the integration (like trying to decode a mp3 file from a wav, which is the default format used by OpenAI)
Supported format thanks to ffmpeg are wav, mp3, aac, flac, opus, defaulting to wav if an unknown or no format is provided.
If a response_format is added in the query (other than wav) and ffmpeg is not available, the call will fail.
Sound prompt expansion
POST /v1/sound-generation accepts optional expansion_model to expand a sound
description with an installed chat model before audio generation:
curl http://localhost:8080/v1/sound-generation \
-H 'Content-Type: application/json'\
-d '{
"model_id": "music",
"text": "A gentle piano instrumental with warm strings",
"expansion_model": "chat",
"instrumental": true
}' --output music.wav
Replace music and chat with your installed audio and chat model names.
The server requires non-empty text when you select expansion_model.
Select an installed llama-cpp chat model with use_tokenizer_template: true
and a tokenizer template that supports native tool calls. Expansion sends one
strict, schema-backed expand_sound function tool with tool_choice: required.
Other backends and configurations without tokenizer templates are rejected before
inference. An explicit grammar is cleared for this request only; the installed
model configuration is unchanged. The configuration flag alone does not guarantee
that the selected model and template support native tools.
The server validates the arguments and stops before audio generation if invalid.
If your account has a model allowlist, it must allow both the resolved audio
model and the selected expansion model. Sound permission covers this internal
expansion; separate Chat permission is not required.
Omit expansion_model to preserve the backend’s existing prompt behavior.
Python ACE-Step then keeps its native Simple-mode expansion.
Advanced requests can continue to send caption, lyrics, and metadata directly.
The chat model must return exactly one expand_sound tool call with required
caption and lyrics strings in its arguments. Assistant prose and reasoning
are never used as fallback arguments.
The server caps output at 2,048 tokens and accepts only these fields:
Field
Accepted value
caption
1–500 characters
lyrics
0–4000 characters
bpm
Integer from 1 through 400
keyscale
One of 504 musical key spellings, such as C, F# minor, or bb dorian (see below)
timesignature
N/D, with each integer from 1 through 32
language
String of at most 32 characters
duration_seconds
Number from 1 through 600
The keyscale tool schema enumerates the accepted spellings instead of using a
regular expression. Use a root from A–G or a–g, optionally followed by
# or b. The root can stand alone or have one space followed by major,
minor, maj, min, dorian, phrygian, lydian, mixolydian, locrian,
ionian, or aeolian. Mode names are lowercase; extra whitespace and other
spellings are not accepted. This preserves the server’s existing vocabulary.
Omit optional fields when unspecified; do not use an empty string or null
for an unknown key. Empty lyrics remains valid for instrumental sound.
Invalid-key errors quote and escape the rejected key, showing at most 64
characters and the total character count if truncated. They do not include
other generated arguments.
Explicit instrumental: true clears generated lyrics. Your selected language
(or vocal_language) takes precedence over generated language.
An explicit duration takes precedence over generated duration.
Conflicting caption, style, lyrics, and music metadata in params cannot replace
expanded fields. The audio backend receives structured fields and an expansion
marker, with the original text cleared. Backend support for expanded requests varies.
An unavailable model, a model without native tool support, a missing or wrong
tool call, multiple calls, or invalid arguments returns a request error. Expansion failures stop the request before audio generation.
Cancellation propagates to model loading, text inference, and audio generation.
In Studio → Sound → Simple, choose a Prompt expansion model before
submitting. Sound uses the same model picker as Home, with search for longer
model lists and keyboard navigation. The list contains installed, enabled chat
models. You must explicitly choose a model or Backend default; opening or
dismissing the picker does not select a model. Backend default
omits expansion_model and uses the audio backend’s existing prompt behavior.
Sound remembers either choice in this browser, separately from your chat model.
If a remembered model disappears or loses chat support, choose again.
Sound refreshes the list when you return to the browser tab.
Without an installed chat model, choose Backend default to continue.
Re-run with edits restores the expansion choice from that result.
Older results without a saved expansion choice use Backend default.
Advanced keeps its caption, lyrics, metadata, and thinking controls;
it never sends expansion_model.
Expanded requests support these audio families:
Backend family
Expanded input
audio-cpp YuE2
Caption as style, generated lyrics
audio-cpp HeartMuLa
Caption as tags, generated lyrics; instrumental requests are rejected because lyrics are required
audio-cpp ACE-Step
Caption as prompt, generated lyrics and supported metadata
audio-cpp Stable Audio
Caption as prompt
Python ACE-Step
Structured caption and lyrics, bypassing its native Simple expansion
Other audio-cpp families reject expanded requests before audio inference.
The chat expansion may already have run when the backend reports this error.
Choose Backend default to use that backend’s existing behavior.
The UI does not detect backend families or silently retry without expansion.
Sound Classification
Sound-event classification (audio tagging) answers the question “what am I hearing?” - given an audio clip, it returns a list of scored AudioSet labels (e.g. Baby cry, infant cry, Glass breaking, Dog bark, Alarm).
LocalAI exposes this through the /v1/audio/classification endpoint, modelled after /v1/audio/transcriptions. The reference backend is ced.cpp (CED, a 527-class AudioSet tagger), a small ViT over a log-mel spectrogram ported to ggml with full PyTorch parity. Apache-2.0 weights are redistributable as GGUF.
parakeet.cpp can also load a CED model (through third_party/ced.cpp) and serve /v1/audio/classification from the same backend used for ASR and diarization. It scores the clip in 10 s windows and averages each class’s score across the windows before sorting and applying top_k/threshold - CED’s own method for clips longer than one window. Install parakeet-cpp-ced-tiny or parakeet-cpp-ced-base from the gallery, or point parameters.model at a CED GGUF under backend: parakeet-cpp. A parakeet-cpp ASR model can also point sound_model at a CED GGUF to add live sound events during realtime transcription - see Realtime API - and to add timed sound events to an offline diarization call with include_sounds=true - see Speaker Diarization. Such a model also answers /v1/audio/classification itself when it declares the sound_classification usecase, as the gallery entry parakeet-cpp-multilingual-diarization-speakers-sounds does.
Because classification is exposed as a regular OpenAI-style endpoint, any HTTP client works - there is no Python dependency on the consumer side.
In distributed mode, LocalAI stages uploaded audio and realtime sound-detection
windows on the selected worker before classification. The API server and worker
do not need a shared temporary directory.
Endpoint
POST /v1/audio/classification
Content-Type: multipart/form-data
Field
Type
Description
file
file (required)
audio file in any format ffmpeg accepts
model
string (required)
name of the sound-classification-capable model (e.g. ced-base-f16)
top_k
int
number of top tags to return (0 = backend default)
The bundle entries parakeet-cpp-bundle-small and parakeet-cpp-bundle-standard also serve this endpoint: they hold CED-Small next to the transcription, VAD and diarization models (sound_component:ced). See Bundle GGUF files.
Speaker diarization answers the question “who spoke when?” - given an audio clip with multiple speakers, it returns time-stamped segments labelled with a stable speaker ID (SPEAKER_00, SPEAKER_01, …).
LocalAI exposes this through the /v1/audio/diarization endpoint, modelled after /v1/audio/transcriptions. Five backends are supported today:
sherpa-onnx - pyannote-3.0 segmentation + a speaker-embedding extractor (3D-Speaker, NeMo, WeSpeaker) + fast clustering. Pure diarization - no transcription cost. Recommended when you only need speaker turns.
vibevoice.cpp - produces speaker-labelled segments as a by-product of its long-form ASR pass, so you can optionally get a transcript per segment for free.
NeMo-Speech.cpp - NVIDIA Sortformer, served standalone by the NeMo-Speech.cpp backend. It is end to end, so the speaker capacity is fixed by the checkpoint and the count hints are ignored. The same backend can instead put speaker tags on a transcript, by attaching a Sortformer model to an ASR one.
parakeet.cpp - NVIDIA Nemotron-3-Diarization (Sortformer, up to 8 speakers), served standalone or paired with a Parakeet ASR model for per-segment text. See the Audio to Text page for the parakeet-cpp option reference.
Because diarization is exposed as a regular OpenAI-compatible endpoint, any HTTP client works. There is no Python dependency on pyannote or NeMo on the consumer side.
In distributed mode, LocalAI stages uploaded audio on the remote worker before
running dedicated diarization and releases the staged input after the request.
The worker does not need access to the frontend’s temporary upload directory.
Endpoint
POST /v1/audio/diarization
Content-Type: multipart/form-data
Field
Type
Description
file
file (required)
audio file in any format ffmpeg accepts
model
string (required)
name of the diarization-capable model
num_speakers
int
exact speaker count when known (>0 forces; 0 = auto)
min_speakers
int
hint when auto-detecting
max_speakers
int
hint when auto-detecting
clustering_threshold
float
cosine distance threshold used when num_speakers is unknown
min_duration_on
float
discard segments shorter than this many seconds
min_duration_off
float
merge gaps shorter than this many seconds
language
string
only meaningful for backends that bundle ASR (e.g. vibevoice)
include_text
bool
when the backend can emit per-segment transcript for free, populate it
include_sounds
bool
add the closed sound events of the clip as sounds. Needs a model with a sound companion; see Sound events. Default false
response_format
string
json (default), verbose_json, or rttm
Response - json (default)
Compact payload, no transcription, no per-speaker summary:
speaker is the normalized, zero-padded label clients should display. label preserves the raw backend-emitted ID for clients that maintain their own speaker dictionary.
Response - verbose_json
Adds per-speaker totals and (when the backend supports it and include_text=true) the per-segment transcript:
{"task":"diarize","duration":12.34,"language":"en","num_speakers":2,"segments":[{"id":0,"speaker":"SPEAKER_00","label":"0","start":0.00,"end":2.34,"text":"Hello, world."},{"id":1,"speaker":"SPEAKER_01","label":"1","start":2.34,"end":4.10,"text":"How are you?"}],"speakers":[{"id":"SPEAKER_00","label":"0","total_speech_duration":5.6,"segment_count":3},{"id":"SPEAKER_01","label":"1","total_speech_duration":1.76,"segment_count":1}]}
Speaker names
With a parakeet-cpp model that has a speaker_model: (or a speaker_component:, for a bundle file such as parakeet-cpp-bundle-standard) and voices registered through /v1/voice/register, segments whose speaker matches a registered voice gain name and name_score (the cosine similarity of the match), and the matching speakers entry gains name. Both fields are omitted for a speaker that was not identified, so an unnamed response looks exactly as before. speaker stays SPEAKER_NN, and RTTM output still uses SPEAKER_NN. See Voice Recognition for the setup and the limits.
{"task":"diarize","duration":12.34,"num_speakers":2,"segments":[{"id":0,"speaker":"SPEAKER_00","label":"0","start":0.00,"end":2.34,"text":"Hello, world.","name":"Alice","name_score":0.82},{"id":1,"speaker":"SPEAKER_01","label":"1","start":2.34,"end":4.10,"text":"How are you?"}],"speakers":[{"id":"SPEAKER_00","label":"0","name":"Alice","total_speech_duration":5.6,"segment_count":3},{"id":"SPEAKER_01","label":"1","total_speech_duration":1.76,"segment_count":1}]}
Sound events
With include_sounds=true the response gains a sounds array: the sound events (AudioSet labels such as Dog, Applause, Cough) found anywhere in the clip, in the same call that returns the speakers, the text and the voice prints. Each item is {start, end, label, confidence}: start and end are in seconds from the start of the audio, and confidence is the peak score the tagger reached while the event lasted (0 to 1). Items are sorted by start. Both json and verbose_json carry the array; rttm has no place for it and returns 400.
An empty sounds array means the sound model ran and found no event. The field is absent when include_sounds is not set. The events come from the same sound stream, with the same on and off thresholds, that a realtime session runs, so a clip gives the same events offline and live. The thresholds are not request fields.
The model needs a sound companion, a sound_model: option pointing at a CED GGUF (the gallery entry parakeet-cpp-multilingual-diarization-speakers-sounds has one). Without it the request fails with HTTP 501 and a message that starts with the stable code include_sounds_unsupported; the same happens for a backend that cannot report sound events. LocalAI never answers with an empty list in place of that error. The speaker segments, text and voice prints are independent of the sound model and cost nothing extra when include_sounds is off.
Response - rttm
NIST RTTM, the standard interchange format used by pyannote.metrics / dscore:
Returned as Content-Type: text/plain; charset=utf-8.
Quick start
First install a diarization-capable model from the gallery. The example below uses vibevoice-cpp-asr, which serves the vibevoice.cpp backend and returns speaker-labelled segments (and, optionally, a transcript):
The sections below show how to configure the two supported backends by hand when you want full control over the segmentation and embedding models.
Backend setup - sherpa-onnx (pure diarization)
Sherpa-onnx needs two ONNX models: pyannote segmentation and a speaker-embedding extractor. Place them under your LocalAI models directory and reference them from the YAML:
The complete -asr-speakers entry downloads Nemotron-3-Diarization, Parakeet TDT+CTC 110M ASR, and the WeSpeaker ResNet34 speaker encoder.
It configures both asr_model and speaker_model; no custom gallery configuration is needed.
See Remember speakers in the Web UI for installation and enrollment.
The parakeet-cpp-multilingual-diarization-speakers-sounds entry downloads Parakeet TDT 0.6B v3 (25 European languages), Nemotron-3-Diarization, the WeSpeaker ResNet34 speaker encoder and CED-Tiny, and sets diarization_model, speaker_model and sound_model. It answers the whole request above from one model name. See Sound events.
The entries parakeet-cpp-bundle-small and parakeet-cpp-bundle-standard hold Nemotron-3-Diarization, an ASR model and the WeSpeaker speaker encoder in one file (diar_component:diar and speaker_component:voice), so one install serves the transcript and the identification options above. See Bundle GGUF files.
For manual configuration, this example pairs Sortformer with ASR:
Getting text on each segment needs both: an asr_model companion loaded on the model, and include_text=true on the request. With only one of the two, segments carry no text and no error is raised. Sortformer has a fixed speaker capacity and no clustering stage, so num_speakers, min_speakers, max_speakers and clustering_threshold are ignored (logged at debug); min_duration_on and min_duration_off are honored. Speaker labels are the decimal index the model assigned ("0", "1", …), or "unknown" when a segment has no diarized speaker.
Sortformer clusters on voice-like characteristics, not on “is this a human”. A loud non-speech sound with voice-like pitch and rhythm (a rooster crow, in one test clip) can come back as its own speaker segment alongside the real speakers. This is model behavior, not a bug in the LocalAI integration: treat an unexpected extra speaker as a hint the clip may contain a non-speech sound, and use Sound Classification to confirm what it is.
Notes
Speaker identity across files: speaker IDs (SPEAKER_00, SPEAKER_01, …) are local to each request. To track the same person across multiple recordings, combine /v1/audio/diarization with /v1/voice/embed (speaker embedding) and maintain your own embedding store.
Hints vs. forces: num_speakers overrides clustering when set; min_speakers / max_speakers are advisory and only honored by backends that expose a range hint. vibevoice.cpp and parakeet-cpp (Sortformer) ignore them - the model picks the count itself.
Sample rate: input is automatically converted to 16 kHz mono via ffmpeg before the backend sees it; sherpa-onnx pyannote-3.0 requires 16 kHz.
See also
Sound Classification - tag non-speech sound events (alarms, glass breaking, baby cry) in a clip.
Backend profile transport
The parakeet backend supports opt-in speaker profile export through the internal
DiarizeRequest.include_speaker_profiles field. This native transport underpins
HTTP profile export and explicit enrollment through POST /v1/voice/register,
as described in Portable speaker enrollment below.
It requires a configured speaker_model and a library
with parakeet_capi_diarize_profiles_pcm_json; an empty recognition registry
is supported. Export does not register anyone. With include_text and a loaded
ASR companion, one profile-capable diarization supplies all speaker slots,
profiles, names, and intervals. Timestamped ASR words are assigned to those
same slots; the backend does not run a second diarization. Either inference
failure fails the request. If no ASR companion is loaded, the existing fallback
applies: the response includes profiles and diarization segments without text.
A loaded ASR companion without the timestamped PCM API returns an explicit error.
DiarizeResponse.speaker_profiles_json carries the native version-1
speaker_profiles object, including original clean preview intervals and one
embedding per usable speaker. Normal requests retain their existing output.
Profile speaker values are raw native slot IDs. Match their decimal string to
segment label or speaker-summary label, not to normalized SPEAKER_NN,
array position, or display name. Slots can be sparse, and profile order can
differ from transcript order. Profiles retain their original clean intervals
even when transcript segments use word boundaries or duration filters.
These vectors are sensitive biometric data: callers must authorize export and
explicit enrollment separately.
The internal backend Status response supplies speaker_encoder, derived from
the loaded encoder’s SHA-256 identity and dimension. Enrollment code must use
backend.ModelSpeakerEncoder with server-selected model configuration and
validate profiles against that result, never against caller-provided metadata.
Unavailable metadata or unsupported export fails closed. Renaming a GGUF does
not change its identity; modifying or quantizing its bytes does.
Recognition replay carries registration IDs separately from display names.
Distinct IDs with the same display name remain independent native entries,
and both offline and realtime matches are translated back to display names.
Legacy transport clients without IDs retain name-keyed behavior. The native
registry’s aggregation defaults are unchanged. LocalAI’s recognition registry
remains global and in-memory; this adds neither persistence nor automatic
registration and is unrelated to persistent TTS voice cloning.
Portable speaker enrollment
Profile-capable parakeet models can export one biometric embedding per discovered
speaker, including when the recognition registry is empty. Export is opt-in:
The /audio/diarization alias has the same protection. With user authentication,
export additionally requires the voice-recognition permission. Existing model
access controls still apply. Without opt-in, speaker_profiles is omitted.
Both json and verbose_json support profiles; rttm with profiles returns 400.
include_text=true retains supported transcripts in either JSON format.
Unsupported profile backends return 501 rather than silently omitting profiles.
The speaker_profiles response object contains version: 1,
encoder: {"identity": "sha256:<64 lowercase hex digits>", "dimension": N},
and speakers. Each speaker contains:
speaker: the raw numeric speaker slot;
clean_duration: retained clean speech in seconds;
intervals: {start, end} ranges in seconds in the original recording;
unavailable_reason: null for usable profiles, otherwise a reason string;
embedding: one vector for a usable speaker, omitted when unavailable.
UI association: convert each profile’s numeric speaker to a decimal string
and match segment/summary label. Do not use SPEAKER_NN, array position, or
human name. Slots may be sparse and out of order; display names may repeat.
Preview intervals against the original audio, not separated audio. Disable
saving unavailable profiles. Enrollment is explicit, never automatic; only
relabel after a successful registration response. See
portable voice registration.
Profiles are sensitive, unsigned biometric data, not proof of identity or consent.
Do not log their vectors. Obtain the speaker’s consent before enrollment.
API tracing excludes the entire exchange for /v1/audio/diarization, its
/audio/diarization alias, and /v1/voice/register before capturing bodies.
This also protects JSON base64 audio when profile export is off. These routes
produce no in-memory or persisted API trace; other routes keep their existing
tracing behavior. External proxies and client logs must apply the same privacy
policy. Existing trace files from older versions are not retroactively scrubbed.
Remember speakers in the Web UI
Use a LocalAI build with portable enrollment support and a profile-capable parakeet-cpp backend.
The backend needs the profile APIs from merged upstream commit
bee7c14 or a compatible later build.
Installing the model weights alone does not update an older backend.
Open Models → Explore and search for parakeet-cpp-nemotron-3-diarization-asr-speakers.
Select Install and wait for installation to complete. Check Operate → Activity for progress or errors.
Open Studio → Diarization (or /app/diarization). Select that model and upload your recording.
Obtain the speaker’s consent before enrollment. To remember a speaker from that recording:
Select Prepare speakers to remember, then select Diarize. This
requests profiles, transcript text, and speaker summaries. Use a
profile-capable parakeet-cpp model configured with a speaker encoder.
In Speakers, select Preview 1, Preview 2, or another available
interval to listen to clean speech from the original recording. Playback
stops at the end of that interval. Stop preview stops it earlier.
Your browser must support the recording’s audio format.
For an unknown speaker, select Name and remember. Enter a name and
select Remember. No second recording or audio upload is needed.
After the server confirms registration, the name appears on all turns for
that speaker. A failed save keeps the entered name so you can retry.
Upload another recording and select Diarize to match remembered voices.
You can turn off Prepare speakers to remember; recognition does not require another profile export.
Matches show their names; unmatched speakers keep their speaker labels.
With preparation off, the UI requests speaker turns without transcript text.
Use the API example below to request text without exporting profiles.
Speakers without a usable profile cannot be
remembered; try longer speech without overlapping speakers. Duplicate names
are allowed: each save creates a separate registration, not a merged voice.
Changing the model or recording clears the current results and save dialog.
A save already sent to the server can still complete, but cannot rename turns
in a different recording.
The page requires the Audio Diarization permission and access to the selected model. Preparing profiles and
remembering speakers additionally require Voice Recognition. Users without
that permission can still run normal diarization. If the backend does not
support profiles, the page reports an error: choose a compatible model or
turn off Prepare speakers to remember. It does not silently retry without
profiles.
Warning
Remembered voices are shared globally on this server and are lost when it
restarts. Nothing is enrolled automatically. The browser stores only the new
registration’s ID, name, and registration time for the existing voice
management list, not its embedding or recording. That list is local to the
browser and is not a durable server registry.
Use Manage remembered voices, then the Enrollment tab, to see or
remove registrations saved in this browser. Clean-clip voice enrollment stays
available there and does not require diarization.
API example: install, export, and remember
This example uses the same complete gallery entry and requires curl and jq.
The commands assume a local server without authentication.
If authentication is enabled, add -H "Authorization: Bearer <key>" to every request using your authorized key.
Keep keys out of shared scripts, logs, and shell history; see Authentication.
Installation requires model-management access; inference and enrollment require the permissions described above.
Installation is asynchronous. Wait for successful completion in Operate → Activity before continuing.
API clients can query the returned job status URL; see the model gallery API.
Warning
Exported profiles contain biometric vectors. Obtain consent before enrollment.
Keep the recording, response, and registration files private. Do not log or share their contents.
Use a new private directory so existing files cannot retain broader permissions. Delete these files when no longer needed.
Export profiles and transcript text from your recording, keeping the complete JSON response:
Choose a usable raw speaker slot whose decimal string matches the intended segment label.
Listen to its intervals in the original recording before assigning a name.
Do not select by array position, normalized SPEAKER_NN, or display name.
If unavailable_reason indicates insufficient speech, try a longer recording without overlapping speakers.
Replace 0 below with your chosen raw slot. Zero is valid, but does not mean “the first array element.”
Keep the complete speaker_profiles object unchanged:
Matching speakers can now carry name, even though this request omits include_speaker_profiles.
Keep include_text=true and verbose_json when you want transcript text.
Recognition is not proof of identity. Registrations remain global and disappear on server restart.
See portable profile registration for encoder compatibility and validation rules.
Audio Transform
The audio-transform endpoints take audio in and emit audio out, optionally
conditioned on a second reference audio signal. The category is generic by
design - concrete operations include joint acoustic echo cancellation +
noise suppression + dereverberation (LocalVQE), voice conversion (reference
= target speaker), pitch shifting, audio super-resolution, and so on.
The first shipping backend is LocalVQE,
a 1.3 M-parameter GGML-based model that performs joint AEC + noise suppression
dereverberation on 16 kHz mono speech, ~9.6× realtime on a desktop CPU. It
is a derivative of the Microsoft DeepVQE paper.
Source separation and voice conversion are served by the
audio.cpp backend: its htdemucs and
mel_band_roformer families produce the named stems described below, and
seed_vc, vevo2 and miocodec do voice conversion against a reference
speaker.
The mental model
Every audio-transform request carries:
audio - the primary input file (required).
reference - an auxiliary signal whose meaning is backend-specific (optional).
For echo cancellation: the loopback / far-end signal played through the speakers.
For voice conversion: the target speaker’s reference clip.
For pitch / style transfer: a tonal or style reference.
When omitted, the backend treats it as silence and degrades gracefully (LocalVQE,
for example, does denoise + dereverb only when ref is empty).
params - a generic key=value map forwarded to the backend.
This shape mirrors WebRTC’s ProcessStream(near) / ProcessReverseStream(far)
APM API, NVIDIA Maxine’s NvAFX_Run paired-stream signature, and the ICASSP
AEC challenge 2-channel WAV convention.
Batch endpoint
POST /audio/transformations (alias POST /audio/transform) - multipart
form-data, returns audio bytes.
Field
Type
Required
Notes
model
string
yes
Audio-transform model id (e.g. localvqe-v1.3-4.8m)
audio
file
yes
Primary input audio
reference
file
no
Optional auxiliary signal
response_format
string
no
wav (default), mp3, ogg, flac
sample_rate
int
no
Desired output sample rate in Hz. Omit it for the backend’s own rate; otherwise it must be between 8000 and 192000, and a value outside that range is refused with a 400
params[<key>]
string
no
Repeated; forwarded to backend
params[stem]
string
no
Multi-output transforms only; picks which named output the body carries (see stems)
When reference is omitted, LocalVQE zero-fills the reference channel and
the operation reduces to noise suppression + dereverberation.
What LocalAI does to your upload before the backend sees it
By default, nothing: the file reaches the backend at its own sample rate and
its own channel count. A WAV already carrying plain 16-bit PCM is passed through
byte for byte; any other container or encoding is transcoded to 16-bit PCM WAV
with the rate and the channel layout kept.
The exception is a backend that declares it needs a fixed input shape.
LocalVQE does: its echo cancellation is trained on 16 kHz mono and needs the
primary input and the reference in the same shape, so uploads for it are folded
to 16 kHz mono s16 with ffmpeg. The declaration is
BackendCapability.AudioTransformInputMono16k in core/config, and localvqe
is currently the only backend that sets it.
This matters for anything that is not speech enhancement. Source separation
models refuse any sample rate but their checkpoint’s own (44.1 kHz for every
published htdemucs and mel_band_roformer checkpoint) and rely on the stereo
image to tell a centred vocal from a wide mix, so a 16 kHz mono downmix would
remove both the format they accept and the cue they work from.
Multi-output transforms (source separation stems)
Some transforms produce several named outputs from one run: htdemucs yields
drums, bass, other and vocals in a single pass. The response body can
carry only one file, so:
The backend runs once and writes every stem beside the main output.
params[stem]=<name> chooses which one the body carries. Without it the
default is vocals when the model has one, and the model’s first output
otherwise. An unknown stem name is refused with an error listing the real
ones, never silently substituted.
Every stem, including the one in the body, is named in the X-Audio-Stems
response header, a compact JSON array:
Fetch any of those URLs to get the other stems without paying for a second
separation. sample_rate and response_format are applied to the stems as well
as to the body, so the whole set stays in the shape you asked for. The header is
listed in Access-Control-Expose-Headers, so browser clients can read it.
Single-output transforms (echo cancellation, voice conversion) do not set the
header at all, and params[stem] against such a model is refused rather than
ignored.
# isolate the vocals (the default), then see where the other stems wentcurl -sS -D headers.txt -X POST http://localhost:8080/audio/transformations \
-F model=htdemucs -F audio=@song.wav -o vocals.wav
grep -i '^x-audio-stems' headers.txt
# or ask for a specific stem in the bodycurl -sS -X POST http://localhost:8080/audio/transformations \
-F model=htdemucs -F audio=@song.wav -F 'params[stem]=drums' -o drums.wav
The stems live in the generated-content directory beside the main output and are
served from /generated-audio/. Like every other generated artifact, they are
not swept automatically.
Text-conditioned transforms (speech to speech)
Most transforms are audio in, audio out. A few are not: a speech-to-speech
model resynthesises a line in another voice and needs to know what the line
says. /audio/transform has no text field, so the text travels as
params[text].
curl -sS -X POST http://localhost:8080/audio/transformations \
-F model=audio-cpp-vevo2-speech-to-speech \
-F audio=@source.wav \
-F reference=@target-speaker.wav \
-F 'params[text]=The quick brown fox jumps over the lazy dog.'\
-o converted.wav
For these models the text is required, not a hint: the run is refused without
it. params[target_text] is accepted as the same field, and
params[language] sets the language when the line is not English. A model that
does not take text ignores all three, so an ordinary separation or
noise-suppression request is unaffected.
Streaming endpoint
GET /audio/transformations/stream - bidirectional WebSocket. The first
client message is a JSON envelope; subsequent client messages are binary
PCM frames; server emits binary PCM frames at the same cadence.
This endpoint accepts models with the audio_transform use case. It does not
accept any-to-any models with the realtime_audio use case. For example,
a realtime any-to-any model uses the OpenAI Realtime API
instead.
sample_format is S16_LE (16-bit signed little-endian) or F32_LE (32-bit
float little-endian, [-1, 1]). frame_samples defaults to the backend’s
preferred hop length (256 = 16 ms for LocalVQE).
Client → server (binary frames, subsequent): interleaved stereo PCM,
channel 0 = audio (mic), channel 1 = reference. Frame size:
frame_samples × 2 channels × sample_size. For S16_LE at 256 samples that
is 1024 bytes per frame; for F32_LE it is 2048 bytes. If the reference is
silent (no auxiliary signal), send zeros on channel 1.
Server → client (binary frames): mono PCM in the same format,
frame_samples × sample_size bytes (512 bytes for S16_LE, 1024 for F32_LE).
Mid-stream control (text frame): another session.update resets the
streaming state when its reset field is true; a session.close text frame
ends the session cleanly.
Latency
LocalVQE has 16 ms algorithmic latency (one hop). At runtime the per-frame CPU
cost depends on the model: ~1.6 ms for the compact 1.3 M models (v1.1/v1.2,
~9.7× realtime) and ~3.3 ms for the wider v1.3 4.8 M model (~4.7× realtime) on
a 4-thread modern desktop, leaving the rest of the budget for network and
downstream playback.
Backend-specific tuning (LocalVQE)
params[<key>]
Type
Default
Effect
noise_gate
bool
false
Enable post-OLA RMS-based residual-echo gate
noise_gate_threshold_dbfs
float
-45.0
Gate threshold in dBFS; frames below are zeroed
The gate is most useful in far-end-only / silent-near-end stretches where the
model’s residual would otherwise sound like buffering or amplified noise floor.
A reasonable starting point is -50 dBFS.
Configuring a model
LocalVQE ships several weight releases in the gallery: localvqe-v1.3-4.8m
(current default - best quality), localvqe-v1.2-1.3m and localvqe-v1.1-1.3m
(compact, ~¼ the per-hop cost - good for low-core or power-constrained hosts).
All share the same backend and request API; only the model filename differs.
name:localvqebackend:localvqeparameters:model:localvqe-v1.3-4.8M-f32.gguf# Backend-specific defaults can be set in Options[]; per-request# params[*] form fields override.## `backend` and `device` route through the upstream localvqe options# builder so you can force a non-default GGML backend (e.g. `Vulkan`) or# pin to a specific GPU index. Leave both unset to keep the CPU default.options:- noise_gate=true- noise_gate_threshold_dbfs=-50# - backend=Vulkan# - device=0
Voice Activity Detection (VAD) identifies segments of speech in audio data. LocalAI provides a /v1/vad endpoint powered by the Silero VAD backend.
The audio.cpp backend also serves this endpoint, and ships the silero_vad and marblenet_vad assets inside its own package, so VAD works there with nothing to download (model: bundled:silero_vad plus the family:silero_vad option).
API
Method:POST
Endpoints:/v1/vad, /vad
Request
The request body is JSON with the following fields:
Parameter
Type
Required
Description
model
string
Yes
Model name (e.g. silero-vad)
audio
float32[]
Yes
Array of audio samples (16kHz PCM float)
Response
Returns a JSON object with detected speech segments:
Field
Type
Description
segments
array
List of detected speech segments
segments[].start
float
Start time in seconds
segments[].end
float
End time in seconds
Usage
Example request
The /v1/vad endpoint expects the audio field to be an array of raw
16kHz mono PCM samples as float32 values, so the request body is usually
built from a real audio file rather than typed by hand.
First convert any audio file to 16kHz mono with ffmpeg:
Then load the samples and POST them (this snippet needs
pip install soundfile numpy requests):
importsoundfileassfimportnumpyasnpimportrequestsaudio,sample_rate=sf.read("speech.wav")ifaudio.ndim>1:audio=audio.mean(axis=1)# downmix to monosamples=audio.astype(np.float32).tolist()response=requests.post("http://localhost:8080/v1/vad",json={"model":"silero-vad","audio":samples},)print(response.json())
Thresholds must be greater than 0 and less than 1. Durations must be nonnegative integers.
Malformed values, negative durations, and NaN thresholds are ignored; the default or last valid value remains in use.
Reload the model (or restart LocalAI) after changing these options.
parakeet-cpp backend
The parakeet-cpp backend serves the same endpoint. It runs one of two detectors:
Silero VAD from a GGUF file (gallery entry parakeet-cpp-silero-vad-f16, 1.3 MB). One probability per 32 ms.
The VAD head of a full Moondream Ultra or Redux model (gallery entries parakeet-cpp-vad-moondream-ultra-q8_0 and parakeet-cpp-vad-moondream-redux-packed). One probability per 80 ms. The packed Redux file runs on CPU only.
A VAD-only slice of that head (gallery entries parakeet-cpp-vad-moondream-redux, 9.9 MB, and parakeet-cpp-vad-moondream-ultra, 6.0 MB). The slice is cut out of the full model without retraining, so the segments are byte-identical to the full model’s head, and the speed is the same. Compared with loading the whole model (213 MB to 1.4 GB), the file is 6 to 10 MB, loads in a few milliseconds instead of 0.1 to 0.7 s, and needs about 245 MiB of peak memory for a 33 s clip instead of 0.6 to 1.6 GiB. A slice cannot transcribe, and it needs a parakeet.cpp build with VAD-only GGUF support (pin e53a253 or newer).
A bundle GGUF (gallery entries parakeet-cpp-bundle-small, parakeet-cpp-bundle-standard and parakeet-cpp-bundle-moondream-redux). The bundle holds a Silero component next to the ASR model, and the backend uses it for this endpoint with no option. See Bundle GGUF files.
The entry parakeet-cpp-vad installs Silero. The detectors differ and are not variants of one model, so install the entry of the VAD head by name if you want it (parakeet-cpp-vad-moondream-redux or parakeet-cpp-vad-moondream-ultra for the small files). The request is the same as above: audio is 16 kHz mono float32 PCM, and the response lists segments with start and end in seconds. An ASR model that has no VAD head fails the request with model has no VAD head.
All options are optional. An unset value keeps the default of the detector in use (the library defaults differ between Silero and the head):
Option
Unit
Silero default
Head default
Description
vad_threshold
0 to 1
0.5
0.5
Speech probability threshold
vad_min_pause
seconds
0.1
0.2
A silence this long separates two segments; shorter gaps merge
vad_min_speech
seconds
0.25
0.1
Shorter speech runs are dropped
vad_speech_pad
seconds
0.03
0
Padding added around each segment
vad_trim
seconds
0.3
0.3
Only for transcription with vad:true or vad_model: each piece shrinks to its speech plus this much. 0 keeps the whole cuts. The endpoint ignores it
Option names differ from the Silero backend above (min_silence_duration_ms and speech_pad_ms are in milliseconds there). The same options tune transcription with vad:true or vad_model; see audio to text. Requests on one loaded model run one at a time.
Detection Parameters
The Silero VAD backend uses the following internal defaults (overridable via options above):
Sample rate: 16kHz
Threshold: 0.5
Min silence duration: 100ms
Speech pad duration: 30ms
Error Responses
Status Code
Description
400
Missing or invalid model or audio field
500
Backend error during VAD processing
Voice Recognition
LocalAI supports voice (speaker) recognition: speaker verification
(1:1), speaker identification (1:N) against a built-in vector store,
speaker embedding, and demographic analysis (age / gender / emotion
from voice).
The audio analog to Face Recognition,
served over the same /v1/voice/* HTTP API by two backends:
voice-detect (recommended, default). A standalone C++/ggml
engine (voice-detect.cpp):
no Python, no onnxruntime, no torch runtime. Each gallery entry is a
single self-describing GGUF. This is the recommended option for new
deployments.
speaker-recognition (Python). The original SpeechBrain / ONNX
backend. Still supported; see the Python backend
below.
Both backends expose the identical wire format, so the API examples on
this page work with either - only the gallery entry name (the model
field) changes.
voice-detect (ggml) backend
The voice-detect backend reads the embedding (or analysis)
architecture (voicedetect.arch) directly from the GGUF metadata, so
installing a gallery entry is all that is needed to select an engine. It
drives the VoiceEmbed / VoiceVerify / VoiceAnalyze gRPC rpcs behind the
/v1/voice/{embed,verify,analyze,register,identify,forget} endpoints.
Gallery entries
Gallery entry
Model
Embedding dim
License
voice-detect-ecapa-tdnn
SpeechBrain ECAPA-TDNN (VoxCeleb)
192
Apache 2.0 - commercial-safe
voice-detect-wespeaker-resnet34
WeSpeaker ResNet34 (VoxCeleb)
256
CC-BY-4.0
voice-detect-eres2net
3D-Speaker ERes2Net (VoxCeleb)
192
Apache 2.0 - commercial-safe
voice-detect-campplus
3D-Speaker CAM++ (VoxCeleb)
192
Apache 2.0 - commercial-safe
voice-detect-emotion-wav2vec2
audEERING wav2vec2 (age / gender / emotion)
analyze head
CC-BY-NC-SA-4.0 - non-commercial
The four speaker-recognition entries drive verify / embed / identify.
voice-detect-emotion-wav2vec2 is the analysis head behind
/v1/voice/analyze (continuous age estimate plus gender and emotion
class scores) and is non-commercial / research use only.
Quickstart
Install the default entry (recommended for copy-paste):
local-ai models install voice-detect-ecapa-tdnn
Verify that two audio clips were spoken by the same person:
The 1:N register / identify / forget workflow and the rest of the API
are identical to the API reference below - just pass a
voice-detect-* model name. The default verify threshold is ~0.25 for
the ECAPA-TDNN / ERes2Net / CAM++ recognizers and ~0.30 for WeSpeaker
ResNet34.
speaker-recognition (Python) backend
The speaker-recognition backend follows the same two-engine pattern
under one image.
Engines
Gallery entry
Model
Size
License
speechbrain-ecapa-tdnn
ECAPA-TDNN on VoxCeleb (SpeechBrain)
~17 MB
Apache 2.0 - commercial-safe
wespeaker-resnet34
WeSpeaker ResNet34 ONNX
~26 MB
Apache 2.0 - commercial-safe
Both entries are commercial-safe Apache-2.0. SpeechBrain is the
default - it’s a lightweight pure-PyTorch checkpoint that auto-
downloads on first use. The wespeaker-resnet34 entry wires the
direct-ONNX path for CPU-only deployments that don’t want the torch
runtime.
Quickstart
Install the default backend and model:
local-ai models install speechbrain-ecapa-tdnn
Verify that two audio clips were spoken by the same person:
curl -sX POST http://localhost:8080/v1/voice/forget \
-d '{"id": "b2f..."}'# → 204 No Content
Warning
Storage caveat. The default vector store is in-memory. All
registered speakers are lost when LocalAI restarts. Persistent storage
(pgvector) is a tracked future enhancement shared with face
recognition - the voice-recognition HTTP API is designed to swap the
backing store without changing the wire format.
Voices from different encoders
Voices from encoders with different embedding sizes can be registered on the
same instance, for example 192-value ECAPA-TDNN voices next to 256-value
WeSpeaker ResNet34 voices. LocalAI keeps one in-memory vector store per
embedding size, so registering a voice of a new size no longer fails.
Identification compares the probe only with voices of the same size. Voices
from an encoder of another size are never candidates.
If no voice of the probe size is registered, /v1/voice/identify returns an
empty matches list and the realtime voice gate reports an unknown speaker.
Neither returns an error.
Two encoders can still give the same size (ECAPA and CAM++ both give 192
values). Those voices share a store and the encoder tag or identity checks
described below apply.
A name is not unique. One name can hold one voice per encoder, and each
registration has its own ID. /v1/voice/forget removes the voice with that
ID only, so forget each ID to remove a person from every encoder.
Naming in diarization and live transcription reads the registry as a whole
and uses the voices that match the loaded encoder.
A parakeet-cpp bundle as the embedding model
A parakeet-cpp model that has a speaker encoder can serve /v1/voice/embed,
/v1/voice/verify, /v1/voice/register and /v1/voice/identify, and the
voice_recognition stage of a realtime pipeline. That is every
bundle with a voice component
(parakeet-cpp-bundle-small and parakeet-cpp-bundle-standard), and any
parakeet-cpp config with a speaker_model: or speaker_component: option, such as
parakeet-cpp-realtime-scene-speakers. Declare speaker_recognition in the
known_usecases of the config; the gallery entries above already do. Then use the model
name as model:
The voice component holds the same weights as voice-detect-wespeaker-resnet34
(256 dimensions), so a voice registered with one model also matches embeddings from the
other. Use a distance threshold near 0.5 for this encoder, as for speaker_model:
naming below. The response model field is the sha256: identity of the encoder
weights.
/v1/voice/verify uses a distance threshold of 0.5 when the request has none. Set the
model option voice_verify_threshold:<distance> (a distance in (0, 2)) to change it.
Only embedding, identification and plain verification are available. There is no
anti-spoofing head, so a verify request with anti_spoofing: true is refused, and
/v1/voice/analyze is not served by parakeet-cpp. The backend needs a libparakeet.so
that exports parakeet_capi_speaker_embed_pcm. With an older library these calls fail
with an Unimplemented error that names the missing symbol, and a model without a
speaker encoder fails with a FailedPrecondition error.
Naming speakers in diarization and live transcription
The parakeet-cpp backend can put the names of registered voices on
diarization results and on live transcription speaker segments. Without
this, speakers only carry labels such as SPEAKER_00.
Register each voice with the WeSpeaker encoder. Install the model with
local-ai models install voice-detect-wespeaker-resnet34, then call
/v1/voice/register with "model": "voice-detect-wespeaker-resnet34"
(see the 1:N workflow).
Install one of the gallery models that loads the same encoder:
parakeet-cpp-nemotron-3-diarization-speakers (diarization),
parakeet-cpp-nemotron-3-diarization-asr-speakers (diarization with
include_text), parakeet-cpp-multilingual-diarization-speakers-sounds
(multilingual diarization with include_text, voice prints and sound events)
or parakeet-cpp-realtime-scene-speakers (live
transcription). Each one adds
speaker_model:voice-detect-wespeaker-resnet34.gguf to a
parakeet-cpp model config.
Call /v1/audio/diarization with that model. Matched segments gain a
name and a name_score, and the matching entry in speakers gains a
name. speaker stays SPEAKER_NN, and RTTM output is unchanged. See
Speaker Diarization for the
response.
Naming speakers from a bundle
A parakeet-cpp bundle file holds the speaker encoder as a component, so its
config has speaker_component:voice and no speaker_model: (the
parakeet-cpp-bundle-small and parakeet-cpp-bundle-standard gallery
entries are set up like this). LocalAI treats speaker_component: as the
speaker encoder of the model when speaker_model: is not set. A
speaker_model: entry always wins, including one that points at the bundle
file itself.
A bundle has no encoder file name, so LocalAI cannot compare file-name tags,
and it never guesses a tag from the bundle file name. For a bundle component
LocalAI sends the backend:
voices with an encoder fingerprint, whatever their
tag: the backend checks the fingerprint against the loaded component.
Voices enrolled from speaker_profiles are in this group. The WeSpeaker
component of the published bundles has the same weights as
voice-detect-wespeaker-resnet34, so a voice enrolled with one works with
the other;
voices with no tag (registered before tags existed);
voices whose tag equals the speaker_tag: option, if set.
Other voices are ignored. To use a voice that carries only a file-name tag,
set the same tag on the model config. For voices registered through the
voice-detect-wespeaker-resnet34 gallery model:
Use speaker_tag: only for voices made by the same weights as the bundle
component. The check by size alone cannot tell two encoders apart.
Which voices are used
LocalAI sends the backend only the registered voices made by the same
encoder as the model’s speaker_model: file. Each registered voice is
tagged with the name of the voice-detect model that made it, which by
default is the GGUF file name (voice-detect-wespeaker-resnet34.gguf for the
gallery entry). The tag must equal the base name of the speaker_model:
file. Voices made with another encoder are ignored, and LocalAI logs a
warning when that leaves no usable voice. Voices registered before the tag
existed have no tag: they are used when their embedding size matches the
tagged ones (or all of them, when no voice carries a matching tag). The
backend skips a voice whose embedding size does not match the speaker model’s,
with a warning in the LocalAI log. Naming then falls back to the remaining
voices, or to no names.
Encoder fingerprint
Two encoders can give embeddings of the same size (ECAPA and CAM++ both give
192 values), so a size match does not prove the voices and the speaker_model:
file share an embedding space. A voice enrolled from speaker_profiles (see
Speaker Diarization) is stored with the
encoder that made it: its weights (sha256: of the encoder file, kept in
the voice’s model field as before) and its family
(voicedetect:<arch>:<name>:<dim>, read from the encoder GGUF metadata and
stored as encoder_family). The parakeet-cpp backend builds the registry with
that fingerprint, and libparakeet checks it against the loaded speaker_model:
before it names anyone:
Registered voices
Result
Same family, same weights
names are assigned
Same family, other weights (for example another quantization)
names are assigned, the library logs a warning
Another family, and no other usable voice
the request fails, and the error names both families
Another family, with usable voices of the right family
the other voices are left out, with a warning
No fingerprint
used as before, with a warning that the encoder is unverified
A voice with only a weights identity takes the family of the loaded encoder
when the weights are the same file. A voice with a different weights hash and
no family is dropped, as before.
A voice registered from audio through the voice-detect backend (POST /v1/voice/register with audio) is fingerprinted too, when the libvoicedetect
in the backend can report its encoder (voice-detect.cpp from the pin that adds
voicedetect_capi_encoder_family). The backend reads the family from the
loaded GGUF, and hashes the model file once at load to get the weights. LocalAI
stores the family as encoder_family and the weights as encoder_weights; the
model field keeps the encoder name as before. If the voice-detect model is
not a plain file the backend cannot hash it and the weights stay empty, so the
family alone fingerprints the voice. When the family is known, LocalAI sends
the voice to the backend whatever its file name, so the family decides.
A voice-detect backend built against an older libvoicedetect cannot report
the family, but it still records the weights. Such a voice is treated as made
by the loaded speaker_model: when the weights are the same file, and stays
unfingerprinted when they differ.
Voices registered before this change have no fingerprint, and so do voices
from a backend that reports neither (the Python speaker-recognition backend).
They are used as described above, by file-name
tag. Such voices and fingerprinted voices cannot share one registry in the
library. When a request has any unfingerprinted voice, all of its voices are
used without the fingerprint check. Register those voices again to get
the check. With speaker_strict:true the backend ignores unfingerprinted
voices, and a request that has only those fails with the library’s message.
The family is also reported in the internal backend status next to the
identity. /v1/voice/identify compares the family of a stored voice with the
family of the probe when both have one, and falls back to the file-name tag
when either has none.
The family is built from the encoder GGUF metadata. For CAM++, WeSpeaker and
ERes2Net the GGUF general.name is the path the model was converted from, so
the same encoder converted again under another name has another family, and
voices registered with the first file are refused with the second. Two
fine-tunes that share an architecture, name and embedding size have the same
family; only the weights hash tells them apart, and a hash mismatch alone only
logs a warning.
Note
With a fingerprint, the model_name: option on the voice-detect model config
no longer breaks naming: the family decides, not the name. Voices registered
without a fingerprint still need the default name to match the
speaker_model: file.
Options
These go in the options: list of the parakeet-cpp model config (see
Audio to Text for the other parakeet-cpp
options).
Option
Default
Meaning
speaker_model:<path>
none
speaker encoder GGUF; needs a diarization model (the primary one, or diarization_model:)
speaker_component:<name>
none
speaker encoder component of a bundle file; used as the speaker encoder for naming when speaker_model: is not set (see Naming speakers from a bundle)
speaker_tag:<tag>
none
encoder tag that also counts as the loaded encoder, for voices that carry only a file-name tag; mainly for a bundle component
speaker_threshold:<float>
0.5
largest distance (1 minus cosine similarity, the unit /v1/voice/identify reports) at which a speaker is named; must be in (0, 2)
speaker_margin:<float>
0.05
the best match must beat the runner-up by this much, otherwise the speaker stays unnamed; must be in [0, 1)
speaker_strict:<bool>
false
ignore registered voices that carry no encoder fingerprint; needs a libparakeet that exports parakeet_capi_speaker_registry_set_strict
parakeet.cpp’s measured starting values for speaker_threshold are 0.5 for
WeSpeaker ResNet34 and CAM++, and 0.3 for ECAPA. A lower value names fewer
speakers and makes fewer mistakes.
Limits
The voice registry is in memory and global. Registered names disappear when
LocalAI restarts, and every user of the instance shares them.
Anyone who is allowed to call a model with speaker_model: or speaker_component: can learn which
registered names match their audio, and their audio is matched against voices
registered by any user, because the voice registry is global. Restrict such
models with the per-user model allowlist.
With include_text=true the names use the default threshold and margin:
speaker_threshold and speaker_margin only apply to diarization without
text.
In live transcription, a speaker segment that closes before its speaker
is identified has no name. Later segments of that speaker do.
Overlapping speech is not resolved.
Accuracy was measured on one fixture (two read-speech voices). Check the
threshold on your own audio.
The backend needs a libparakeet with C-API v10. With an older library a
model config that sets speaker_model: or speaker_component: fails to load.
A bundle does not serve /v1/voice/register, /v1/voice/identify or
/v1/voice/verify itself. Register voices with a voice-detect model (or
from speaker_profiles), then name them through the bundle.
API reference
POST /v1/voice/verify (1:1)
field
type
description
model
string
gallery entry name (e.g. speechbrain-ecapa-tdnn)
audio1, audio2
string
URL, base64, or data-URI of an audio file
threshold
float, optional
cosine-distance cutoff; default 0.25 for ECAPA-TDNN
anti_spoofing
bool, optional
reserved - unused in the current release
Returns verified, distance, threshold, confidence, model,
and processing_time_ms.
POST /v1/voice/analyze
Returns demographic attributes (age, gender, emotion) inferred from
speech:
field
type
description
model
string
gallery entry
audio
string
URL / base64 / data-URI
actions
string[]
subset of ["age","gender","emotion"]; empty = all supported
Emotion is inferred from the SUPERB emotion-recognition checkpoint
(superb/wav2vec2-base-superb-er, Apache 2.0) - 4-way categorical
neutral / happy / angry / sad. The model auto-downloads on the first
analyze call.
Age and gender are opt-in: no standard-transformers checkpoint
with a clean classifier head is shipped as the default. The
high-accuracy Audeering age/gender model uses a custom multi-task
head that AutoModelForAudioClassification doesn’t load safely
(the age weights are silently dropped and the classifier is
re-initialised with random values). To enable age/gender, set
age_gender_model:<repo> in the model YAML’s options: pointing at
a checkpoint with a vanilla Wav2Vec2ForSequenceClassification
head. Override the emotion default similarly via emotion_model:.
Set either to an empty string to disable that head.
If a head fails to load (offline, disk full, transformers
missing), the engine degrades gracefully: it still returns the
attributes it could compute. When nothing can be computed the backend
returns 501 Unimplemented.
Analyze is supported by both speechbrain-ecapa-tdnn and
wespeaker-resnet34 - the speaker recognizer and the analysis head
are independent.
POST /v1/voice/register (1:N enrollment)
field
type
description
model
string
voice recognition model
audio
string
speaker audio to enroll
name
string
human-readable label
labels
map[string]string, optional
arbitrary metadata
store
string, optional
vector store model; defaults to local-store
Returns {id, name, registered_at}. The id is an opaque UUID used
by /v1/voice/identify and /v1/voice/forget. The stored voice records the
encoder fingerprint when the backend reports it.
POST /v1/voice/identify (1:N recognition)
field
type
description
model
string
voice recognition model
audio
string
probe audio
top_k
int, optional
max matches to return; default 5
threshold
float, optional
cosine-distance cutoff; default 0.25
store
string, optional
vector store model
Returns a list of matches sorted by ascending distance, each with
id, name, labels, distance, confidence, and match
(distance ≤ threshold).
POST /v1/voice/forget
field
type
description
id
string
ID returned by /v1/voice/register
Returns 204 No Content on success, 404 Not Found if the ID is
unknown.
POST /v1/voice/embed
Returns the L2-normalized speaker embedding vector.
field
type
description
model
string
voice model
audio
string
URL / base64 / data-URI
Returns {embedding: float[], dim: int, model: string}. Dimension
depends on the recognizer: 192 for ECAPA-TDNN, 256 for WeSpeaker
ResNet34.
Note: the OpenAI-compatible /v1/embeddings endpoint is
intentionally text-only - it does nothing useful with audio input.
Use /v1/voice/embed for audio.
Audio input
Audio is materialised by the HTTP layer to a temporary WAV file
before the gRPC call. All audio fields accept:
The backend itself always receives a filesystem path - the same
convention the Whisper / Voxtral transcription backends use.
Threshold reference
Recognizer
Cosine-distance threshold
ECAPA-TDNN (SpeechBrain, VoxCeleb)
~0.25
WeSpeaker ResNet34
~0.30
3D-Speaker ERes2Net
~0.28
Pass threshold explicitly when switching recognizers - the per-model
default only applies when omitted.
The WebUI page
The page is the Recognition tab of the Voice add-on (Add-ons → Voice, /app/addons/voice/voice/recognition). Install the add-on from Browse add-ons and start it. Canonical links show the add-on shell when the installation is unavailable. The page calls the /v1/voice/* routes described on this page with your own session. The Voice page has four tabs. Recognition is this feature. Library is the Voice Library for text-to-speech, a different store with its own recordings and transcripts. Text to speech speaks text with a voice model. From a recording links to the diarization workspace, where a speaker can be named and remembered.
On the Recognition tab:
Who is this matches a clip against the people you enrolled (POST /v1/voice/identify). The answer is a sentence with the real distance and the cut-off, a word for how far inside the cut-off it sits (strong, likely, close call), and a scale with the cut-off drawn on it. The cut-off slider re-reads the answer in the browser; it does not call the server again. The page sends the cut-off in the request, 0.25 by default.
Same person? compares two clips (POST /v1/voice/verify) and uses the threshold the model returns. The word is not a probability, and the page says so.
Enrol a speaker opens a sheet: a recording, a name, optional labels, and a permission tick. An administrator can also keep the recording as a speech voice in the same step. Keeping a copy of the recording in the browser is off unless you tick it.
Known speakers is a list kept in the browser. The server has no list call, so the page cannot check it by itself. After a search it marks a saved person the server did not return as “not on the server” (only when the search asked for more people than it got back, so a short answer is never read as proof), and lists anyone the server returned that this browser has no record of. A server restart empties the server’s index; enrol again, or use Re-enrol from saved copy if you kept one.
Removing a person waits ten seconds behind an Undo toast. Nothing is sent to the server until the time ends; Undo cancels it.
If no speaker-recognition model is installed, the tool is replaced by a note that says so, with models from the gallery to install. Users without the Voice recognition permission see a page that says it is off for their account.
The clip you test with is sent to the model on the server and is not kept. Analyze (age, gender and emotion guesses, all off by default) and the raw embedding are under More tools.
Related features
Face Recognition - the image analog;
the two share a registry design.
Audio to Text - transcription (Whisper,
Voxtral, faster-whisper). Runs in addition to, not instead of,
voice recognition.
Stores - the generic vector store powering
both the face and voice 1:N recognition pipelines.
Embeddings - text-only OpenAI-compatible
embedding endpoint; for audio embeddings use /v1/voice/embed.
Portable profile registration
POST /v1/voice/register also accepts a JSON alternative to audio:
// result is the parsed diarization response; slot is a selected raw speaker slot.
constrequest={model:"parakeet-diarization",name:"Ada",labels:{team:"research"},speaker_slot:slot,speaker_profiles:result.speaker_profiles};// POST JSON.stringify(request) with Content-Type: application/json.
Copy the complete speaker_profiles object returned by diarization unchanged.
Select speaker_slot explicitly, including for slot zero. It is the raw numeric
slot whose decimal string matches the diarization label, not a normalized
SPEAKER_NN, array index, or display name. audio and speaker_profiles are
mutually exclusive. speaker_slot without profiles is also invalid. Audio-only
registration keeps its existing JSON shape and behavior.
The server loads the requested, authorized model and obtains encoder identity and
dimension from backend metadata. It validates the complete profile export and
selects the requested usable slot. Missing slots, unavailable speech, unsupported
versions, non-finite/zero/wrong-size vectors and encoder mismatch return 400.
A backend without trusted encoder metadata returns 501. Success returns the
existing {id, name, registered_at} response.
Portable registrations store the server-derived SHA-256 identity, not a
caller-provided filename tag. Offline/live recognition admits these registrations
only when the loaded encoder has the same identity and dimension. Legacy audio
registrations retain their filename-tag compatibility rules. /v1/voice/identify
filters incompatible matches; a backend unable to report trusted identity cannot
match portable registrations, even when vector dimensions agree. Filtering can
return fewer than top_k results. The parakeet diarization model need not support
the separate audio-only VoiceEmbed RPC used by /v1/voice/identify.
Each successful enrollment inserts a new registration with its own ID and vector.
Duplicate display names do not merge embeddings or update an earlier enrollment.
There is no automatic enrollment or sample aggregation.
The recognition registry is global, in-memory and per LocalAI instance;
registrations are lost on restart and are not synchronized across frontends.
This is not durable “remembering” and not a per-user private address book. The
persistent /api/voice-profiles TTS-cloning feature is unrelated. Export and
registration use the existing voice-recognition permission, with existing model
access restrictions; permission does not establish biometric consent.
API tracing excludes the entire exchange for /v1/audio/diarization, its
/audio/diarization alias, and /v1/voice/register before capturing bodies.
This also protects JSON base64 audio when profile export is off. These routes
produce no in-memory or persisted API trace; other routes keep their existing
tracing behavior. External proxies and client logs must apply the same privacy
policy. Existing trace files from older versions are not retroactively scrubbed.
For offline and live diarization replay, registry tags never determine the
encoder dimension. LocalAI orders candidates by registration ID (tagged first),
then uses loaded encoder metadata to filter dimensions. Portable registrations
require an exact SHA-256 identity match as well. Older backends without trusted
metadata reject portable candidates and retain their native legacy dimension
checks. Identification filters compatibility after the store’s top_k query;
incompatible results can crowd out compatible candidates within that window.
Images, video and 3D
Image understanding, detection, faces, image and video generation, 3D and motion. The Studio add-on makes and keeps images, video and 3D in one page, and the Face add-on is a page for face recognition.
LocalAI supports understanding images by using LLaVA, and implements the GPT Vision API from OpenAI.
Usage OpenAI docs: https://platform.openai.com/docs/guides/vision
First install a vision-capable model from the gallery (the examples below use moondream2-20250414, a small vision model):
local-ai run moondream2-20250414 To let LocalAI understand and reply with what sees in the image, use the /v1/chat/completions endpoint, for example with curl:
LocalAI supports object detection and image segmentation through various backends. This feature allows you to identify and locate objects within images with high accuracy and real-time performance. Available backends include RF-DETR (Python) and rf-detr.cpp (native C++/ggml) for object detection and segmentation, and sam3.cpp for image segmentation (SAM 3/2/EdgeTAM).
For detecting faces specifically, see the dedicated Face Recognition feature - its /v1/detection support is tuned for face bounding boxes and ships with commercially-safe model options.
LocalAI supports face recognition: face verification (1:1), face identification (1:N) against a built-in vector store, face embedding, face detection, demographic analysis (age / gender), and antispoofing / liveness detection.
The same /v1/face/* HTTP API is served by two backends:
LocalAI can generate videos from text prompts and optional image or audio conditioning via the /video endpoint. Supported backends include diffusers, stablediffusion (including MiniMax-H3, which generates video and audio together), vllm-omni, mlx-video on Apple Silicon, and the dedicated longcat-video backend.
MLX-Video on Apple Silicon Install the native Metal backend, then configure an LTX-2 repository:
LocalAI can generate textured 3D meshes from a single conditioning image via the /3d/generations endpoint, powered by the trellis2cpp backend — a C++/GGML port of Microsoft TRELLIS.2 (trellis2.cpp). The output is a binary glTF (.glb) asset with PBR materials.
Generation is image-conditioned only — there is no text-prompt path. Provide a photo or rendering of a single object (ideally on a plain background) and TRELLIS.2 reconstructs a full 3D mesh from it.
LocalAI supports text-to-motion with kimodo.cpp on CPU and Vulkan. In Studio → 3D, selecting an animation model replaces the image input with a motion prompt and the selected model’s animation controls.
The Studio preview plays at real-time speed using the GLB’s timestamps. Slow or delayed display frames skip ahead rather than slowing the animation. Pause and the timeline let you inspect individual poses; playback resumes from that point.
Kimodo exports an animated skeleton GLB: joint rotations and root movement, without a mesh or skin. SOMA models produce the compact 30-joint skeleton; G1 models produce 34 joints. These outputs are animation assets, not textured characters, and cannot use TRELLIS print remeshing.
LocalAI’s gemxcpp backend converts timestamped RGB frames into human poses using gem-x.cpp. It runs resident GEM-X, ViTPose and YOLOX models on CPU or Vulkan. Live inference does not need SAM3D Body. This initial integration is API-only: no Motion UI, offline clip export, body mesh or SONIC controller is included.
Install and configure Import https://huggingface.co/LocalAI-io/GEM-X-GGUF through the model importer. It selects gemxcpp and downloads three checksummed, revision-pinned assets. These are custom F32 GGUF architectures, not language models. Weight licenses are described in the source model card. Allow memory for all three models and execution buffers, beyond their roughly 4 GB combined download size.
Subsections of Images, video and 3D
Image understanding
LocalAI supports understanding images by using LLaVA, and implements the GPT Vision API from OpenAI.
First install a vision-capable model from the gallery (the examples below use moondream2-20250414, a small vision model):
local-ai run moondream2-20250414
To let LocalAI understand and reply with what sees in the image, use the /v1/chat/completions endpoint, for example with curl:
curl http://localhost:8080/v1/chat/completions -H "Content-Type: application/json" -d '{
     "model": "moondream2-20250414",
     "messages": [{"role": "user", "content": [{"type":"text", "text": "What is in the image?"}, {"type": "image_url", "image_url": {"url": "https://upload.wikimedia.org/wikipedia/commons/thumb/d/dd/Gfp-wisconsin-madison-the-nature-boardwalk.jpg/2560px-Gfp-wisconsin-madison-the-nature-boardwalk.jpg" }}], "temperature": 0.9}]}'
Grammars and function tools can be used as well in conjunction with vision APIs:
 curl http://localhost:8080/v1/chat/completions -H "Content-Type: application/json" -d '{
     "model": "moondream2-20250414", "grammar": "root ::= (\"yes\" | \"no\")",
     "messages": [{"role": "user", "content": [{"type":"text", "text": "Is there some grass in the image?"}, {"type": "image_url", "image_url": {"url": "https://upload.wikimedia.org/wikipedia/commons/thumb/d/dd/Gfp-wisconsin-madison-the-nature-boardwalk.jpg/2560px-Gfp-wisconsin-madison-the-nature-boardwalk.jpg" }}], "temperature": 0.9}]}'
Setup
Install a vision-capable model from the gallery, either from the Models page in the web UI or from the CLI:
local-ai run moondream2-20250414
Other vision models are available in the gallery (for example smolvlm-instruct and smolvlm2-2.2b-instruct). Browse them on the Models page or see the /docs/models/.
Object Detection
LocalAI supports object detection and image segmentation through various backends. This feature allows you to identify and locate objects within images with high accuracy and real-time performance. Available backends include RF-DETR (Python) and rf-detr.cpp (native C++/ggml) for object detection and segmentation, and sam3.cpp for image segmentation (SAM 3/2/EdgeTAM).
For detecting faces specifically, see the dedicated
Face Recognition feature - its
/v1/detection support is tuned for face bounding boxes and ships
with commercially-safe model options.
Overview
Object detection in LocalAI is implemented through dedicated backends that can identify and locate objects within images. Each backend provides different capabilities and model architectures.
Key Features:
Real-time object detection
High accuracy detection with bounding boxes
Image segmentation with binary masks (SAM backends)
Text-prompted, point-prompted, and box-prompted segmentation
Support for multiple hardware accelerators (CPU, NVIDIA GPU, Intel GPU, AMD GPU)
Structured detection results with confidence scores
Easy integration through the /v1/detection endpoint
Usage
Detection Endpoint
LocalAI provides a dedicated /v1/detection endpoint for object detection tasks. This endpoint is specifically designed for object detection and returns structured detection results with bounding boxes and confidence scores.
API Reference
To perform object detection, send a POST request to the /v1/detection endpoint:
The RF-DETR backend is implemented as a Python-based gRPC service that integrates seamlessly with LocalAI. It provides object detection capabilities using the RF-DETR model architecture and supports multiple hardware configurations:
CPU: Optimized for CPU inference
NVIDIA GPU: CUDA acceleration for NVIDIA GPUs
Intel GPU: Intel oneAPI optimization
AMD GPU: ROCm acceleration for AMD GPUs
NVIDIA Jetson: Optimized for ARM64 NVIDIA Jetson devices
Setup
Using the Model Gallery (Recommended)
The easiest way to get started is using the model gallery. The rfdetr-base model is available in the official LocalAI gallery:
# Install and run the rfdetr-base modellocal-ai run rfdetr-base
You can also install it through the web interface by navigating to the Models section and searching for “rfdetr-base”.
Manual Configuration
Create a model configuration file in your models directory:
Currently, the following model is available in the Model Gallery:
rfdetr-base: Base model with balanced performance and accuracy
You can browse and install this model through the LocalAI web interface or using the command line.
RF-DETR Native Backend (rfdetr-cpp)
The rfdetr-cpp backend is a native C++/ggml implementation of RF-DETR
inference based on rf-detr.cpp. It
runs as a Go gRPC service that dlopens a per-CPU-variant shared library, so
there is no Python runtime on the inference path - startup is fast and the
binary is self-contained.
Compared to the Python rfdetr backend, the native backend:
Has no Python or PyTorch dependency at inference time
Supports both detection and segmentation variants of RF-DETR
Returns segmentation masks as PNG bytes in Detection.mask
Setup
Install the backend
local-ai backends install rfdetr-cpp
Using the Model Gallery (Recommended)
The gallery ships ready-to-run entries for every published variant:
# Detection variantslocal-ai run rfdetr-cpp-nano
local-ai run rfdetr-cpp-small
local-ai run rfdetr-cpp-base
local-ai run rfdetr-cpp-medium
local-ai run rfdetr-cpp-large
# Segmentation variants (return per-instance PNG masks)local-ai run rfdetr-cpp-seg-nano
local-ai run rfdetr-cpp-seg-small
local-ai run rfdetr-cpp-seg-medium
local-ai run rfdetr-cpp-seg-large
local-ai run rfdetr-cpp-seg-xlarge
local-ai run rfdetr-cpp-seg-2xlarge
Pre-quantized GGUFs are published under
mudler/rfdetr-cpp-*
on Hugging Face. Each repo carries the F32/F16/Q8_0/Q4_K quants - F16 is
the recommended default (matches F32 accuracy, ~1.86x smaller).
Segmentation Output
When running a segmentation model (any rfdetr-cpp-seg-* variant), each
Detection in the response carries a mask field with a base64-encoded
PNG of the per-instance binary mask. The mask is sized to the original
image resolution and aligns with the corresponding bounding box.
SAM3 Backend (sam3-cpp)
The sam3-cpp backend provides image segmentation using sam3.cpp, a portable C++ implementation of Meta’s Segment Anything Model. It supports multiple model architectures:
SAM 3: Full model with text encoder for text-prompted detection and segmentation
SAM 2 / SAM 2.1: Hiera backbone models in multiple sizes
SAM 3 Visual-Only: Point/box segmentation without text encoder
EdgeTAM: Ultra-efficient mobile variant (~15MB quantized)
Setup
Manual Configuration
Create a model configuration file in your models directory:
Verify model compatibility with your backend version
Low Detection Accuracy
Ensure good image quality and lighting
Check if objects are clearly visible
Consider using a larger model for better accuracy
Slow Performance
Enable GPU acceleration if available
Use a smaller model for faster inference
Optimize image resolution
Debug Mode
Enable debug logging for troubleshooting:
local-ai run --debug rfdetr-base
Object Detection Category
LocalAI includes a dedicated object-detection category for models and backends that specialize in identifying and locating objects within images. This category currently includes:
LocalAI supports face recognition: face verification (1:1), face
identification (1:N) against a built-in vector store, face embedding,
face detection, demographic analysis (age / gender), and antispoofing /
liveness detection.
The same /v1/face/* HTTP API is served by two backends:
face-detect (recommended, default). A standalone C++/ggml
engine (face-detect.cpp):
no Python, no onnxruntime, no torch runtime. Each gallery entry is a
single self-describing GGUF. This is the recommended option for new
deployments.
insightface (Python). The original ONNX Runtime backend. Still
supported; see the Python backend below.
Both backends expose the identical wire format, so the API examples in
this page work with either - only the gallery entry name (the model
field) changes.
face-detect (ggml) backend
The face-detect backend reads the detector and recognizer architecture
(facedetect.arch) directly from the GGUF metadata, so installing a
gallery entry is all that is needed to select an engine. It drives the
Embeddings / Detect / FaceVerify / FaceAnalyze gRPC rpcs behind the
/v1/face/{embed,verify,analyze,detect,register,identify,forget}
endpoints.
Licensing - read this first
Gallery entry
Detector + recognizer
Embedding dim
License
face-detect-buffalo-l
SCRFD-10GF + ArcFace R50 + GenderAge
512
Non-commercial research only (upstream insightface weights)
face-detect-buffalo-m
SCRFD-2.5GF + ArcFace R50 + GenderAge
512
Non-commercial research only
face-detect-buffalo-s
SCRFD-500MF + MBF + GenderAge
512
Non-commercial research only
face-detect-yunet-sface
YuNet + SFace (OpenCV Zoo)
128
Apache 2.0 - commercial-safe
The insightface buffalo packs (buffalo_l / buffalo_m / buffalo_s) are
released by the upstream maintainers for non-commercial research use
only. Pick the face-detect-yunet-sface entry for production /
commercial deployments.
Quickstart
Install the commercial-safe entry (recommended for copy-paste):
The 1:N register / identify / forget workflow and the rest of the API
are identical to the API reference below - just pass a
face-detect-* model name. The per-engine verify thresholds are ~0.35
for the buffalo ArcFace/MBF recognizers and ~0.363 for SFace.
insightface (Python) backend
The insightface backend ships two interchangeable engines under
one image, each paired with a distinct gallery entry so users can pick
by license and accuracy needs.
Licensing - read this first
Gallery entry
Detector + recognizer
Size
License
insightface-buffalo-l
SCRFD-10GF + ArcFace R50 + GenderAge
~326 MB
Non-commercial research only (upstream insightface weights)
insightface-buffalo-s
SCRFD-500MF + MBF + GenderAge
~159 MB
Non-commercial research only
insightface-opencv
YuNet + SFace
~40 MB
Apache 2.0 - commercial-safe
The insightface Python library itself is MIT, but the pretrained model
packs (buffalo_l, buffalo_s, antelopev2) are released by the upstream
maintainers for non-commercial research use only. Pick the
insightface-opencv entry for production / commercial deployments.
Quickstart
Pull the commercial-safe backend (recommended for copy-paste):
The default identity store is in memory. Clients can keep an enrollment record
and replay it with POST /v1/face/register after a restart. Extract the embedding
once with /v1/face/embed, then save the exact returned vector, model, name,
labels, and enrollment timestamp. Submit embedding instead of img:
The vector above is abbreviated; send the complete embedding from the same
recognizer model. Provide exactly one of img or embedding. Vectors must be
finite and nonzero. registered_at is optional and defaults to the current time;
replay the original timestamp to preserve it.
The store upserts by exact vector. Registration now derives a stable ID from
that vector and the store namespace, so retries and replay after a restart
return the same ID without adding duplicate entries. Replaying updates the name
and labels. Images can produce slightly different embeddings across runs; keep
the original vector instead of embedding the photo again on each retry.
This does not make the server store persistent. Clients must retain and restore
the records themselves. With independent stores behind a load balancer, replay
into each store or use a shared store. Do not mix different recognizer models in
one store. IDs from older versions change on their first registration replay.
1:N identification workflow (register → identify → forget)
This is the primary “face recognition” flow. Under the hood it uses
LocalAI’s built-in in-memory vector store - no external database to
stand up.
curl -sX POST http://localhost:8080/v1/face/forget \
-d '{"id": "8b7..."}'# → 204 No Content
Warning
Storage caveat. The default vector store is in-memory. All
registered faces are lost when LocalAI restarts. Persistent storage
(pgvector) is a tracked future enhancement - the face-recognition HTTP
API is designed to swap the backing store without changing the wire
format.
API reference
POST /v1/face/verify (1:1)
field
type
description
model
string
gallery entry name (e.g. insightface-buffalo-l)
img1, img2
string
URL, base64, or data-URI
threshold
float, optional
cosine-distance cutoff; default depends on engine
anti_spoofing
bool, optional
also run MiniFASNet liveness on each image - see Antispoofing
Returns verified, distance, threshold, confidence, model,
img1_area, img2_area, and processing_time_ms. When
anti_spoofing is set, the response also carries per-image liveness
fields: img1_is_real, img1_antispoof_score, img2_is_real,
img2_antispoof_score. A failed liveness check on either image forces
verified=false regardless of similarity.
POST /v1/face/analyze
Returns demographic attributes for every detected face:
field
type
description
model
string
gallery entry
img
string
URL / base64 / data-URI
actions
string[]
subset of ["age","gender","emotion","race"]; empty = all supported
Only insightface-buffalo-l / insightface-buffalo-s populate age and
gender (genderage head). insightface-opencv returns face regions with
empty attributes - SFace has no demographic classifier. Emotion and
race are always empty in the current release.
POST /v1/face/register (1:N enrollment)
field
type
description
model
string
face recognition model
img
string
face to enroll
name
string
human-readable label
labels
map[string]string, optional
arbitrary metadata
store
string, optional
vector store model; defaults to local-store
Returns {id, name, registered_at}. The id is an opaque UUID used by
/v1/face/identify and /v1/face/forget.
POST /v1/face/identify (1:N recognition)
field
type
description
model
string
face recognition model
img
string
probe image
top_k
int, optional
max matches to return; default 5
threshold
float, optional
cosine-distance cutoff; default 0.35 (ArcFace)
store
string, optional
vector store model; defaults to local-store
Returns a list of matches sorted by ascending distance, each with id,
name, labels, distance, confidence, and match
(distance ≤ threshold).
POST /v1/face/forget
field
type
description
id
string
ID returned by /v1/face/register
Returns 204 No Content on success, 404 Not Found if the ID is
unknown.
POST /v1/face/embed
Returns the L2-normalized face embedding vector for the detected face.
field
type
description
model
string
face model
img
string
URL / base64 / data-URI
Returns {embedding: float[], dim: int, model: string}. Dimension is
512 for the insightface ArcFace/MBF recognizers and 128 for OpenCV’s
SFace.
Note: the OpenAI-compatible /v1/embeddings endpoint is
intentionally text-only by contract (input is a string or list of
strings of TEXT to embed) - passing an image data-URI there does
nothing useful. Use /v1/face/embed for image inputs.
Reused endpoint
POST /v1/detection - returns face bounding boxes with
class_name: "face"; works for both engines.
Antispoofing (liveness detection)
All gallery entries ship the Silent-Face-Anti-Spoofing
MiniFASNetV2 + MiniFASNetV1SE ensemble (Apache 2.0, ~4 MB total, CPU-only)
alongside the face recognition weights. Set anti_spoofing: true on
/v1/face/verify or /v1/face/analyze to run liveness on each detected
face. The two models look at different crop scales and their softmax
outputs are averaged before argmax - the upstream-recommended setup.
If either image fails liveness (is_real=false), verified is forced
to false - similarity alone is not enough.
/v1/face/analyze reports per-face is_real and antispoof_score
when the flag is set.
Fail-loud semantics. If anti_spoofing: true is sent against a
model installed without the MiniFASNet files (e.g. a custom entry that
only listed the face recognition weights), the request returns a gRPC
FAILED_PRECONDITION error - the endpoint will never silently return
is_real=false. Re-install the gallery entry or point the backend at a
model that bundles the MiniFASNet ONNX files.
Info
The MiniFASNet score is best at catching printed photos and screen
replays. Deepfake videos and high-quality prosthetics are out of
scope - liveness here is a low-cost first line of defence, not a
guarantee. For higher assurance, combine with challenge-response (e.g.
ask the user to turn their head).
Choosing an engine
Need
Entry
Commercial product
insightface-opencv
Highest accuracy (research / demos)
insightface-buffalo-l
Edge / low-memory / research
insightface-buffalo-s
The recommended default threshold for /v1/face/verify and
/v1/face/identify depends on the recognizer:
Recognizer
Cosine-distance threshold
ArcFace R50 (buffalo_l)
~0.35
MBF (buffalo_s)
~0.40
SFace (opencv)
~0.50
Pass threshold explicitly when switching engines - the per-engine
default only fires when the field is omitted.
The WebUI page
The page is the Recognition page of the Face add-on (Add-ons → Face, /app/addons/face/recognition). Install the add-on from Browse add-ons and start it. Canonical links show the add-on shell when the installation is unavailable. The page calls the /v1/face/* routes described on this page with your own session. It follows the same layout as the Voice add-on’s Recognition page. Who is this looks up a photo against the people you enrolled (POST /v1/face/identify, cut-off 0.35 by default, adjustable on the scale). Same person? compares two photos (POST /v1/face/verify), optionally with the liveness check, and draws the face the model found in each photo. Enrol a person takes a photo, a name, optional labels and a permission tick; a copy of the photo stays in the browser only if you tick it.
The people list is kept in the browser because the server has no list call. After a search, a saved person the server did not return is marked “not on the server”, and a server restart empties the server’s index. Removing a person waits ten seconds behind an Undo toast before POST /v1/face/forget is sent. The server matches one face per photo. Detecting faces, attribute guesses (off by default, often wrong) and the raw embedding are under More tools. With no face model installed the page says what is missing and offers gallery models to install.
Related features
Object Detection - generic bounding-box
detection; /v1/detection works with the insightface backend too.
Embeddings - raw vector extraction; face
embeddings live in the same endpoint under the hood.
Stores - the generic vector store powering the
1:N recognition pipeline.
Image Generation
LocalAI supports generating images with Stable diffusion, running on CPU using C++ and Python implementations.
Available additional parameters: mode, step, negative_prompt.
To set a negative prompt you can either pass a separate negative_prompt field or split the prompt with |, e.g. a cute baby sea otter|malformed. When both are present they are joined with a comma (negative_prompt first, then the |-suffixed tags), so a global negative prompt can live in negative_prompt while per-image negatives are appended after |.
curl http://localhost:8080/v1/images/generations -H "Content-Type: application/json" -d '{
"prompt": "floating hair, portrait, ((loli)), ((one girl)), cute face, hidden hands, asymmetrical bangs, beautiful detailed eyes, eye shadow, hair ornament, ribbons, bowties, buttons, pleated skirt, (((masterpiece))), ((best quality)), colorful|((part of the head)), ((((mutated hands and fingers)))), deformed, blurry, bad anatomy, disfigured, poorly drawn face, mutation, mutated, extra limb, ugly, poorly drawn hands, missing limb, blurry, floating limbs, disconnected limbs, malformed hands, blur, out of focus, long neck, long body, Octane renderer, lowres, bad anatomy, bad hands, text",
"size": "256x256"
}'
Backends
stablediffusion-ggml
This backend is based on stable-diffusion.cpp. Every model supported by that backend is supported indeed with LocalAI.
Setup
There are already several models in the gallery that are available to install and get up and running with this backend, you can for example run flux by searching it in the Model gallery (flux.1-dev-ggml) or start LocalAI with run:
local-ai run flux.1-dev-ggml
To use a custom model, you can follow these steps:
Create a model file stablediffusion.yaml in the models folder:
Download the required assets to the models repository
Start LocalAI
Memory and device placement options
When a model does not fit entirely in VRAM, the following options: control where weights and computation are placed. They map directly to the upstream stable-diffusion.cpp options.
Option
Example
Description
backend
backend:clip=cpu,vae=cuda0,diffusion=vulkan0
Runtime (compute) backend assignment per component. Use cpu to place a component’s compute on the CPU. Component keys include te (text encoder / CLIP), vae, diffusion, controlnet.
params_backend
params_backend:diffusion=disk,clip=cpu
Where parameters (weights) are stored. Supports cpu, disk (mmap weights from disk to save RAM/VRAM), or per-component specs.
max_vram
max_vram:8 or max_vram:-1
Optional per-device VRAM budget (in GiB) for managed weights and automatic graph-cut execution. 0 uses live free VRAM without an explicit cap; a negative value reserves that many GiB of free VRAM. Also accepts per-backend budgets.
stream_layers
stream_layers:true
Deprecated compatibility option. Segmented weight streaming is now selected automatically, so this value is ignored.
rpc_servers
rpc_servers:localhost:50052,192.168.1.3:50052
Comma-separated list of host:port RPC servers to offload compute to.
pulid_weights_path
pulid_weights_path:pulid.safetensors
Path to PuLID-Flux weights for identity injection.
The following convenience booleans are still accepted and are translated into the backend / params_backend specs above:
Option
Equivalent spec
offload_params_to_cpu:true
params_backend += *=cpu
keep_clip_on_cpu:true
backend += te=cpu
keep_vae_on_cpu:true
backend += vae=cpu
keep_control_net_on_cpu:true
backend += controlnet=cpu
For example, to mmap the diffusion weights from disk while keeping the text encoder on the CPU:
vae_decode_only is still accepted for backwards compatibility but is now a no-op: upstream removed the flag and the model decides automatically.
VAE tiling
Sampling runs in a small latent space, but the final VAE decode expands it to full resolution and needs one large compute buffer. At 1024x1024 that buffer can exceed 8 GB, which is enough to fail on a GPU that has plenty of memory overall:
ggml_vulkan: Requested buffer size exceeds device buffer size limit: ErrorOutOfDeviceMemory
[ERROR] vae: failed to allocate the compute buffer
[ERROR] stable-diffusion.cpp - decode_first_stage failed for latent 1
Tiling decodes the latent in overlapping tiles, so peak memory scales with the tile instead of the image. It costs a little time and can leave faint seams, so it is off unless you ask for it.
Option
Example
Description
vae_tiling
vae_tiling:true
Enable tiled VAE decoding. The bare form vae_tiling also works.
vae_tile_size
vae_tile_size:512 or vae_tile_size:512x384
Tile dimensions in pixels. One number means a square tile. Omit to use the upstream default.
vae_tile_overlap
vae_tile_overlap:0.25
Overlap between neighbouring tiles. More overlap hides seams better and costs more time. Omit to use the upstream default.
Reach for this when the decode fails but sampling completed, which the backend log shows as sampling completed followed by a VAE allocation error. Two cases hit it: cards without the VRAM for a full-frame decode, and drivers that cap a single allocation regardless of free memory (Mesa RADV reports a 4 GiB maxMemoryAllocationSize, so a large decode fails there even with tens of GB free). Lowering the output resolution avoids it too, at the cost of the resolution.
ESRGAN image upscaling
The stablediffusion-ggml backend supports standalone ESRGAN upscaling through
POST /v1/images/upscale. This is a separate, upscale-only model, not a diffusion
pipeline. Image generation does not automatically upscale its results.
For manual installation, download that checkpoint into your models directory and
save the following as realesrgan-x4plus-anime-6b.yaml alongside it (the gallery
installer configures these settings for you):
upscale_scale and upscale_tile_size are backend options, expressed as
key:value strings in options, not root-level configuration fields.
upscale_scale must be a positive integer. Keep known_usecases explicitly
set to [upscale]: do not add image or diffusion_model options to this
configuration. Options are forwarded unchanged; the backend rejects invalid
or duplicate recognized settings.
The multipart fields model, image, and scale are required. The HTTP
endpoint accepts only integer scales from 1 through 16, rejecting missing,
malformed, zero, negative, or larger values with HTTP 400. This range is not a
promise that each model supports every scale: for ESRGAN, the configured
upscale_scale, the loaded model’s detected native scale, and the request’s
scale must all match exactly. Mismatches fail rather than silently resizing or
running multiple passes. For this model, always request scale=4.
The response follows the image-generation response format, with the output URL
in data[0].url under /generated-images. A successful 4x upscale multiplies
both width and height by four.
upscale_tile_size controls ESRGAN tiling in pixels: omit it or set it to
0 for stable-diffusion.cpp full-frame processing; set a positive value (such
as the gallery entry’s 128) to enable tiling. Smaller tiles reduce working
memory at the cost of more tile work. Full-frame processing can use much more
memory. upscale_direct is a separate convolution-algorithm flag, not a tile
control. Tile settings apply to ESRGAN, not the diffusion model’s separate VAE
tiling settings.
In Studio, open an existing image, choose Upscale, select an installed
upscaler, and submit. The scale is read-only and comes from the selected model’s
configured scale. A successful result becomes an Upscale child node of the
source image, leaving the original intact. Open that child to continue the
workflow with the available image actions, including another upscale or image
editing; each upscale is an explicit operation, not a post-generation default.
Unlike the Diffusers upscaling described below, this path uses ESRGAN inference
and does not fall back to Lanczos resizing.
Distributed inference (RPC workers)
The stablediffusion-ggml backend can offload computation to remote ggml RPC workers, sharding a model that does not fit on a single machine. It reuses the same backend-agnostic rpc-server workers as the llama.cpp backend, so one worker pool can serve both.
Manual: point the model at running workers with the rpc_servers option:
Automatic (peer-to-peer): when LocalAI runs in p2p worker mode, discovered workers are published in the LLAMACPP_GRPC_SERVERS environment variable. The image-generation backend reads that variable automatically (when rpc_servers is not set), so the same local-ai worker p2p-llama-cpp-rpc workers used for text generation also accelerate image generation - no per-model configuration needed.
By default the RPC devices join the pool and participate in placement; combine with the backend / params_backend options above to pin specific components to them (e.g. backend:diffusion=rpc0).
Diffusers
Diffusers is the go-to library for state-of-the-art pretrained diffusion models for generating images, audio, and even 3D structures of molecules. LocalAI has a diffusers backend which allows image generation using the diffusers library.
Image upscaling
The Diffusers backend can upscale an uploaded image through
POST /v1/images/upscale. The multipart scale field is required and must be an
integer from 1 through 16 at the HTTP boundary; actual scaling behavior depends
on the selected pipeline. Install the included Stable Diffusion x4 upscaler
gallery model first:
The response uses the same format as image generation and returns the generated
image under /generated-images. The diffusers backend uses a loaded
StableDiffusionUpscalePipeline or StableDiffusionLatentUpscalePipeline when
configured. Other diffusers pipelines fall back to Lanczos resizing. Upscale
routes select models with known_usecases: [upscale], not ordinary image
generation models. If you installed the x4 upscaler before it declared this
usecase, update its model YAML to known_usecases: [upscale] or reinstall the
gallery entry. Custom Diffusers configurations intended for upscaling should
also explicitly declare the upscale usecase.
Model setup
The models will be downloaded the first time you use the backend from huggingface automatically.
Create a model configuration file in the models directory, for instance to use Linaqruf/animagine-xl with CPU:
name:animagine-xlparameters:model:Linaqruf/animagine-xlbackend:diffusersf16:falsediffusers:cuda:false# Enable for GPU usage (CUDA)scheduler_type:euler_a
Dependencies
This is an extra backend - in the container is already available and there is nothing to do for the setup. Do not use core images (ending with -core). If you are building manually, see the build instructions.
Model setup
The models will be downloaded the first time you use the backend from huggingface automatically.
Create a model configuration file in the models directory, for instance to use Linaqruf/animagine-xl with CPU:
The following parameters are available in the configuration file:
Parameter
Description
Default
f16
Force the usage of float16 instead of float32
false
step
Number of steps to run the model for
30
cuda
Enable CUDA acceleration
false
enable_parameters
Parameters to enable for the model
negative_prompt,num_inference_steps,clip_skip
scheduler_type
Scheduler type
k_dpp_sde
cfg_scale
Configuration scale
8
clip_skip
Clip skip
None
pipeline_type
Pipeline type
AutoPipelineForText2Image
lora_adapters
A list of lora adapters (file names relative to model directory) to apply
None
lora_scales
A list of lora scales (floats) to apply
None
There are available several types of schedulers:
Scheduler
Description
ddim
DDIM
pndm
PNDM
heun
Heun
unipc
UniPC
euler
Euler
euler_a
Euler a
lms
LMS
k_lms
LMS Karras
dpm_2
DPM2
k_dpm_2
DPM2 Karras
dpm_2_a
DPM2 a
k_dpm_2_a
DPM2 a Karras
dpmpp_2m
DPM++ 2M
k_dpmpp_2m
DPM++ 2M Karras
dpmpp_sde
DPM++ SDE
k_dpmpp_sde
DPM++ SDE Karras
dpmpp_2m_sde
DPM++ 2M SDE
k_dpmpp_2m_sde
DPM++ 2M SDE Karras
Pipelines types available:
Pipeline type
Description
StableDiffusionPipeline
Stable diffusion pipeline
StableDiffusionImg2ImgPipeline
Stable diffusion image to image pipeline
StableDiffusionDepth2ImgPipeline
Stable diffusion depth to image pipeline
DiffusionPipeline
Diffusion pipeline
StableDiffusionXLPipeline
Stable diffusion XL pipeline
StableVideoDiffusionPipeline
Stable video diffusion pipeline
AutoPipelineForText2Image
Automatic detection pipeline for text to image
VideoDiffusionPipeline
Video diffusion pipeline
StableDiffusion3Pipeline
Stable diffusion 3 pipeline
FluxPipeline
Flux pipeline
FluxTransformer2DModel
Flux transformer 2D model
SanaPipeline
Sana pipeline
Advanced: Additional parameters
Additional arbitrary parameters can be specified in the option field in key/value separated by ::
name:animagine-xloptions:- "cfg_scale:6"
Note: There is no complete parameter list. Any parameter can be passed arbitrarily and is passed to the model directly as argument to the pipeline. Different pipelines/implementations support different parameters.
The example above, will result in the following python code when generating images:
pipe(prompt="A cute baby sea otter",# Options passed via APIsize="256x256",# Options passed via APIcfg_scale=6# Additional parameter passed via configuration file)
Usage
Text to Image
Use the image generation endpoint with the model name from the configuration file:
LocalAI can generate videos from text prompts and optional image or audio conditioning via the /video endpoint. Supported backends include diffusers, stablediffusion (including MiniMax-H3, which generates video and audio together), vllm-omni, mlx-video on Apple Silicon, and the dedicated longcat-video backend.
MLX-Video on Apple Silicon
Install the native Metal backend, then configure an LTX-2 repository:
The backend accepts text-to-video and start-image conditioning through /video.
LTX-2 also accepts an end_image. Converted Wan2.1/Wan2.2 checkpoints must be
configured as a local model directory and do not support end_image. Useful
backend-specific params include pipeline and tiling for LTX-2, and
scheduler, shift, and tiling for Wan.
API
Method:POST
Endpoint:/video
Request
The request body is JSON with the following fields:
Parameter
Type
Required
Default
Description
model
string
Yes
Model name to use
prompt
string
Yes
Text description of the video to generate
negative_prompt
string
No
What to exclude from the generated video
start_image
string
No
Starting image as base64 string or URL
end_image
string
No
Ending image for guided generation
audio
string
No
Audio conditioning as base64, a data URI, or URL
ref_images
string[]
No
Reference images as base64, data URIs or URLs. Cannot be combined with start_image or end_image
ref_videos
object[]
No
Reference videos: {"frames": [...], "fps": 24, "audio": "..."}. frames is an ordered list of images, fps and audio are optional
ref_audios
string[]
No
Reference audio clips. The stablediffusion backend reads WAV only
width
int
No
backend
Video width in pixels; omit it to get the model’s own default canvas
height
int
No
backend
Video height in pixels; omit it to get the model’s own default canvas
num_frames
int
No
Number of frames
fps
int
No
Frames per second
seconds
string
No
Duration in seconds
size
string
No
Size specification (alternative to width/height)
input_reference
string
No
Input reference for the generation
seed
int
No
Random seed for reproducibility
cfg_scale
float
No
Classifier-free guidance scale
step
int
No
Number of inference steps
response_format
string
No
url
url to return a file URL, b64_json for base64 output
params
object
No
Backend-specific string parameters
Response
Returns an OpenAI-compatible JSON response:
Field
Type
Description
created
int
Unix timestamp of generation
id
string
Unique identifier (UUID)
data
array
Array of generated video items
data[].url
string
URL path to video file (if response_format is url)
data[].b64_json
string
Base64-encoded video (if response_format is b64_json)
Usage
First install a video-generation model from the gallery (the examples below use longcat-video):
local-ai run longcat-video
Generate a video from a text prompt
curl http://localhost:8080/video \
-H "Content-Type: application/json"\
-d '{
"model": "longcat-video",
"prompt": "A cat playing in a garden on a sunny day",
"width": 512,
"height": 512,
"num_frames": 16,
"fps": 8
}'
curl http://localhost:8080/video \
-H "Content-Type: application/json"\
-d '{
"model": "longcat-video",
"prompt": "Ocean waves on a beach",
"response_format": "b64_json"
}'
LongCat-Video and Avatar 1.5
LocalAI’s longcat-video backend serves Meituan’s official LongCat video-generation models through the /video API and the Studio Video page.
Gallery model
Upstream checkpoint
Inputs
Output
longcat-video
meituan-longcat/LongCat-Video
text, optional start image
video
longcat-video-avatar-1.5
meituan-longcat/LongCat-Video-Avatar-1.5
text, audio, optional portrait
video with the source audio
The base checkpoint supports text-to-video and image-to-video. Avatar 1.5 adds audio-driven character animation, optional portrait conditioning, and continuation segments for longer speech.
Warning
LongCat is a large, CUDA-only model family. LocalAI publishes this backend for Linux with NVIDIA CUDA 12 or CUDA 13 on x86_64 and CUDA 13 on ARM64. CPU, ROCm, and macOS images are not available. Avatar 1.5 also loads components from the base checkpoint, so reserve substantial disk and GPU or unified memory.
Install from the Model Gallery
Install one or both recipes from Models in the web UI, or use the CLI:
You can also import either official Hugging Face URL. The importer recognizes the two repositories and writes a longcat-video model config with the appropriate use case and input/output modalities.
The required OCI backend is installed automatically when LocalAI first loads the model. The hardware detector selects the CUDA 12, CUDA 13, or CUDA 13 ARM64 variant.
DGX Spark and NVIDIA ARM64
Use a LocalAI CUDA 13 ARM64 image as described in GPU acceleration. The backend defaults to PyTorch SDPA, avoiding the FlashAttention dependency that is commonly unavailable on Blackwell ARM64 systems.
For unified-memory systems, start with BF16 (use_int8:false, the default). INT8 lowers steady-state DiT memory but can have a higher load-time peak because the full model is materialized before the quantized weights are applied.
Generate in Studio
Open Studio, then choose Video.
Select longcat-video or longcat-video-avatar-1.5.
Enter a prompt and choose 832x480 or 1280x720.
Expand Reference media to upload a start image. For Avatar 1.5, upload or record the speech under Avatar audio.
Select Generate.
The base model can run without a reference image for text-to-video. Avatar 1.5 requires audio; the portrait is optional.
LongCat API examples
Text-to-video
curl http://localhost:8080/video \
-H "Content-Type: application/json"\
-d '{
"model": "longcat-video",
"prompt": "A cinematic tracking shot through a misty redwood forest",
"width": 832,
"height": 480,
"num_frames": 93,
"fps": 15
}'
Image-to-video
start_image accepts raw base64, a browser-style data URI, or a public HTTP(S) URL:
curl http://localhost:8080/video \
-H "Content-Type: application/json"\
-d "{
\"model\": \"longcat-video\",
\"prompt\": \"The subject turns toward the camera as leaves move in the breeze\",
\"start_image\": \"$(base64 --wrap=0 portrait.png)\",
\"params\": {
\"resolution\": \"480p\"
}
}"
Avatar from speech and a portrait
audio accepts raw base64, a data URI, or a public HTTP(S) URL. Each staged image or audio input is limited to 128 MiB.
Avatar output is generated at 25 FPS and is muxed with the submitted audio. When neither num_frames nor params.num_segments is provided, LocalAI derives the continuation count from the audio duration, up to the model’s max_segments setting.
LongCat model configuration
The gallery and importer make each model self-describing. A manual Avatar 1.5 config looks like this:
The explicit modality declarations are used by GET /v1/models/capabilities and attachment-aware clients. They avoid inferring model behavior from backend or checkpoint names.
Load options
Model load options use key:value entries in options:
Option
Default
Description
attention_backend
sdpa
sdpa, auto, flash2, flash3, or xformers; packaged images guarantee sdpa
use_distill
Avatar: true; base: false
Use the checkpoint’s accelerated distillation path
use_int8
false
Use Avatar 1.5’s INT8 DiT; unsupported by the base model
base_model
meituan-longcat/LongCat-Video
Base tokenizer, text encoder, and VAE used by Avatar 1.5
max_segments
8
Maximum continuation segments accepted for one request
resolution
480p
Default image-conditioned resolution: 480p or 720p
The initial backend supports one GPU per process. Tensor or context parallel sizes above one are rejected.
Per-request parameters
The /video request’s params object accepts string values:
Parameter
Description
num_segments
Explicit number of Avatar continuation segments
audio_guidance_scale
Audio classifier-free guidance when distillation is disabled
offload_kv_cache
Offload continuation KV cache (true or false)
ref_img_index
Reference-frame index used during continuation
mask_frame_range
Number of frames blended around continuation boundaries
resolution
Per-request image-conditioned resolution (480p or 720p)
With distillation enabled, Avatar uses eight inference steps and fixed text/audio guidance of 1.0. Disable use_distill in the model config before tuning step, cfg_scale, or audio_guidance_scale.
LongCat troubleshooting
HTTP 400, audio is required: Avatar 1.5 was selected without audio.
HTTP 400, request needs too many segments: trim the audio or raise max_segments in the model options.
HTTP 412: the installed LocalAI runtime cannot select a compatible NVIDIA backend image.
Out of memory while loading: use BF16 on unified-memory hardware, close other GPU workloads, or reduce model concurrency. INT8 is not guaranteed to reduce peak load memory.
Slow first request: the backend and checkpoints are downloaded and loaded on demand; subsequent requests reuse the loaded pipeline.
MiniMax-H3
MiniMax-H3 generates video and audio jointly. The clip comes back as an MP4 with a real AAC track rather than a silent render. It runs on the stablediffusion-ggml backend (stable-diffusion.cpp), through the -ggml gallery entries:
The vllm-cpp backend has no MiniMax-H3 gallery entries. Its H3 path did not finish a clip in a practical time, so use the -ggml entries above.
This is a large model. The weight files total tens of gigabytes, so use a CUDA host and plan for a long-running HTTP call.
Ask for the sound
The model generates picture and sound from the same prompt, so a prompt that only describes what is seen produces room tone and ambience. To get speech, say that the character talks and put the words in the prompt:
It is TALKING to the camera: its mouth moves clearly in sync with its speech,
in a dry, deadpan tone.
It says, clearly and audibly: "Michael scheduled another all-hands.
It is about the printer. Again."
Audio: a single clear voice, close-miked, with quiet room tone underneath.
Geometry and clip length
MiniMax-H3 renders at 24 fps. The width and height are rounded up to a multiple of 32, and the frame count is rounded up to the 17n+5 grid (…, 90, 107, 124, 141, …). The trained clip range is roughly 124 to 362 frames (about 5 to 15 seconds).
Text-to-video with sound
curl http://localhost:8080/video \
-H "Content-Type: application/json"\
-d '{
"model": "minimax-h3-fl2va-pruned-q4-ggml",
"prompt": "A cyan llama mascot in a grey office chair, talking to the camera. It says, clearly and audibly: \"the printer is down again\". Audio: one clear close-miked voice.",
"num_frames": 124,
"seed": 42
}'
First-frame conditioning
start_image pins the supplied image as frame 0 (H3’s fl2va task); end_image pins the last frame.
curl http://localhost:8080/video \
-H "Content-Type: application/json"\
-d "{
\"model\": \"minimax-h3-fl2va-pruned-q4-ggml\",
\"prompt\": \"the subject turns toward the camera and starts speaking\",
\"start_image\": \"$(base64 --wrap=0 portrait.png)\"
}"
Partitions: what each checkpoint will and will not do
MiniMax-H3 ships as two DiT partitions. The FL2VA entries serve t2va (text only) and fl2va (first/last frame). Reference conditioning (a whole reference image, a reference clip, or reference audio) belongs to the Ref2VA entry. The FL2VA entries refuse reference inputs up front, naming the partition. The partition is declared in the model config (video_partition) rather than detected.
ffmpeg is required on the host
Muxing the finished frames and audio into an MP4 needs ffmpeg on the host.
negative_prompt, cfg_scale and fps have no MiniMax-H3 equivalent: H3 has no negative prompt or CFG scale, and it renders at a fixed frame rate that the audio track is synchronised to.
Reference inputs
A MiniMax-H3 Ref2VA checkpoint (minimax-h3-ref2va-pruned-q4-ggml) takes several reference images, reference videos (each with an fps and an optional paired audio clip) and reference audio clips through ref_images, ref_videos and ref_audios. The single audio field counts as one more reference audio. Reference inputs need the Ref2VA checkpoint and cannot be mixed with start_image or end_image. A request accepts at most 16 entries of each kind and at most 512 frames per reference video. Reference audio must be WAV.
MiniMax-H3 troubleshooting
ffmpeg not found: install ffmpeg on the host. The frames and audio are already rendered; only the mux failed.
A reference image, clip or audio is refused by an FL2VA entry: use start_image for first-frame conditioning, or install the Ref2VA entry.
Text inside the frame comes out malformed: this is the model’s weakest area. Composite logos and signage in afterwards.
Error Responses
Status Code
Description
400
Missing or invalid model or request parameters
412
The selected backend cannot run on the available hardware
500
Backend error during video generation
3D Generation
LocalAI can generate textured 3D meshes from a single conditioning image via the /3d/generations endpoint, powered by the trellis2cpp backend — a C++/GGML port of Microsoft TRELLIS.2 (trellis2.cpp). The output is a binary glTF (.glb) asset with PBR materials.
Generation is image-conditioned only — there is no text-prompt path. Provide a photo or rendering of a single object (ideally on a plain background) and TRELLIS.2 reconstructs a full 3D mesh from it.
For text-conditioned animated skeletons, see 3D Animation. Both workflows appear under 3D in Studio; selecting a model changes the inputs and generation options.
Setup
Install a model from the gallery:
local-ai run trellis2-4b # full pipeline: 1024³ cascade + PBR textures (~18 GB)# orlocal-ai run trellis2-4b-geometry # 512³ untextured geometry only (~7 GB)
The backend detects which component GGUFs are present and degrades gracefully: without the texture models it produces untextured geometry, and without the fine-flow models it falls back to a coarse marching-cubes preview.
API
Method:POST
Endpoint:/3d/generations
Request
The request body is JSON with the following fields:
Parameter
Type
Required
Default
Description
model
string
Yes
Model name to use
image
string
Yes
Conditioning image as base64, a data URI, or a public URL
quality
string
No
auto
Mesh pipeline: auto, coarse, 512, or 1024
background
string
No
auto
Background handling: auto, keep, black, or white
step
int
No
12
Flow sampling steps for the shape
texture_steps
int
No
12
Flow sampling steps for the PBR material
cfg_scale
float
No
7.5
Classifier-free guidance scale
seed
int
No
random
Random seed for reproducibility
response_format
string
No
url
url to return a file URL, b64_json for base64 output
quality selects the mesh resolution: coarse is a fast marching-cubes preview, 512 the fine dual-grid mesh, 1024 the high-resolution cascade (slow — several minutes, roughly 10 GB VRAM), and auto picks the best pipeline the installed model set supports.
background controls solid-background removal on the conditioning image before generation: auto detects border-connected near-black/near-white, keep preserves the image alpha exactly, and black/white force removal of that colour.
Backend-specific params: texture_size (UV-atlas resolution hint when atlas baking is enabled) and components (tiny removes small islands, largest keeps only the biggest connected component, all — the default — keeps everything).
Response
Returns a JSON response using LocalAI’s OpenAI-style generation envelope:
Field
Type
Description
created
int
Unix timestamp of generation
id
string
Unique identifier (UUID)
data
array
Array with the generated asset
data[].url
string
URL path to the .glb under /generated-3d (if url)
data[].b64_json
string
Base64-encoded GLB (if response_format is b64_json)
Watertight print remeshing
POST /3d/remesh applies the same post-generation CGAL Alpha Wrap workflow as the trellis2.cpp demo. It accepts multipart/form-data and returns the remeshed GLB directly as model/gltf-binary:
Field
Type
Required
Default
Description
model
string
Yes
Installed TRELLIS.2 model name
mesh
file
Yes
Source GLB produced by TRELLIS.2
detail
float
No
0.5
Smallest preserved detail as a percentage of the source bounding-box diagonal (0.35–2.5)
There is intentionally no independent offset control. The enclosing offset follows the trellis2.cpp demo and is derived as detail / 30; independent tuning tends to produce puffy or degenerate wraps. Lower detail percentages retain finer features but take longer and generally produce more triangles. The output is watertight, oriented, intersection-free, and 2-manifold. For textured sources, LocalAI unwraps the replacement mesh and reprojects its PBR material onto a new UV atlas.
Source GLBs may be up to 512 MiB. This route uses its own upload limit because fine TRELLIS.2 meshes commonly exceed LocalAI’s default --upload-limit.
The response contains a URL such as /generated-3d/b64123456789.glb; fetch it from the same server. The GLB is standard glTF 2.0 and opens in Blender, three.js, <model-viewer>, and most engines.
The React UI includes a 3D tab in the Studio (and a /3d page) with an interactive PBR viewer: upload or paste an image from the clipboard, pick the quality, and preview the generated mesh with orbit/pan/zoom and a wireframe toggle. Past generations are kept in the browser (IndexedDB). After generation, a single Detail slider and Apply remeshing button replace the preview with the exact watertight model that the GLB download exports; Show original switches back without regenerating.
Notes
The 512³ pipeline takes roughly two minutes on a modern GPU; the 1024³ cascade takes around five minutes and needs about 10 GB VRAM plus a temporary host-RAM spike.
TRELLIS2_DEVICE=cpu forces CPU inference (slow; mainly for debugging).
The generated mesh has unoriented winding (faithful to TRELLIS.2) and is exported Y-up with vertex-PBR materials; a UV-atlas texture bake can be enabled in the backend via the T2GLB_XATLAS environment variable.
3D Animation
LocalAI supports text-to-motion with kimodo.cpp on CPU and Vulkan. In
Studio → 3D, selecting an animation model replaces the image input with a
motion prompt and the selected model’s animation controls.
The Studio preview plays at real-time speed using the GLB’s timestamps. Slow or
delayed display frames skip ahead rather than slowing the animation. Pause and
the timeline let you inspect individual poses; playback resumes from that point.
Kimodo exports an animated skeleton GLB: joint rotations and root movement,
without a mesh or skin. SOMA models produce the compact 30-joint skeleton;
G1 models produce 34 joints. These outputs are animation assets, not textured
characters, and cannot use TRELLIS print remeshing.
Setup and runtime options
Install kimodo-soma-rp, kimodo-soma-seed, kimodo-g1-rp, or
kimodo-g1-seed from the model gallery. For example:
local-ai run kimodo-soma-rp
Importing the corresponding LocalAI-io/Kimodo-*-GGML Hugging Face repository
also installs the motion weights and the shared Llama-3-Kimodo text bundle.
Each installation needs three files: the motion GGUF, a monolithic text-encoder
GGUF, and tokenizer.gguf. Text weights and the tokenizer are shared under
kimodo/text; SOMA and G1 do not download separate copies of the same encoder.
SMPL-X weights are not included
in the gallery because their redistribution terms differ.
The default entries use Q8_0, matching upstream’s performance default.
Other text-encoder quantizations are available through the -q6_k, -q5_k,
-q4_k_m, -q4_k, and -bf16 gallery entries, for example
kimodo-g1-rp-q4_k_m. Quantization affects the text encoder, not the F32 motion
weights. Lower-bit encoders reduce memory use but can change the generated motion.
These are explicit choices, not automatically ranked alternatives to Q8_0.
The model importer also accepts a text_quantization preference with q8_0
(default), q6_k, q5_k, q4_k_m, q4_k, or bf16. To change an existing
installation manually, download the selected encoder beside tokenizer.gguf
and update text_bundle to its GGUF path.
Linux has CPU and Vulkan builds on amd64 and arm64. Apple Silicon uses the
CPU build; this upstream engine does not implement Metal. Linux x86 CPU
packages select AVX2/FMA/F16C/BMI2 where supported, with a portable fallback.
Containers must expose the host GPU’s Vulkan ICD and driver libraries, not just
CUDA compute devices. On NVIDIA, enable graphics driver capabilities alongside
compute; on NixOS CDI installations, check that the NVIDIA Vulkan manifest is
also mounted inside the container.
An installed model can override the defaults in its YAML configuration:
device accepts auto, cpu, or vulkan; explicitly requesting unavailable
Vulkan fails rather than silently using CPU. threads applies to both the text
encoder and motion model. text_layer_chunk accepts 1–32 and defaults to 32:
all text-encoder layers stay resident across requests for maximum throughput.
Set it to 8 (or another smaller value) to load fewer layers at a time when
memory is limited. Full residency still executes bounded eight-layer graphs;
resident weight count and execution graph size are separate concerns.
The backend keeps one native session loaded and serializes generation. It
reuses text and motion weights, packed attention/LoRA paths, and upstream’s
cached motion execution graphs instead of reloading and rebuilding per request.
The graph cache is bounded to the most recent batch/frame shape. Cold loading
therefore takes longer than subsequent generations.
Allow memory for motion weights and execution buffers as well as the encoder.
BF16 text weights alone are about 14.1 GiB and should use a smaller
text_layer_chunk on a 16 GiB GPU. Each loaded motion model has its own native
session and resident memory, even when model files are shared on disk.
Upstream’s optional KIMODO_TEXT_RESIDENT_LIMIT_MIB environment variable can
also impose a residency ceiling; above it, a request for 32 layers uses streaming.
Existing text_bundle directory paths remain supported for legacy layer-file
installations. They also adopt the new 32-layer default unless explicitly
configured otherwise. Switching to monolithic weights does not delete the old
files; remove them only after confirming no model configuration still uses them.
API
POST /3d/animate accepts named, typed conditioning inputs and model-specific
parameters. Query /v1/models/capabilities and inspect three_d_operations
for the selected model’s supported inputs, controls, and defaults. Animation
does not universally require text: other backends may declare video or a
combination of mesh and text inputs.
{"model":"kimodo-soma-rp","inputs":{"prompt":{"type":"text","data":"A person walks forward and waves."}},"params":{"frames":"150","steps":"100","text_guidance":"2","seed":"42"},"response_format":"url"}
The response contains data[0].url for the generated .glb, or
data[0].b64_json when response_format is b64_json. The endpoint uses the
existing 3D Generation permission and the selected model’s access controls.
/3d/generations and /3d/remesh retain their existing mesh workflows.
Kimodo accepts one prompt with 60–150 frames at 30 FPS. The reference defaults
are 150 frames, 100 sampling steps, and text guidance 2. Parameters are strings;
unsupported inputs and parameters are rejected. Multi-prompt transitions and
mesh retargeting are not currently exposed by this adapter.
Request traces
With tracing enabled, POST /3d/animate appears on the
Traces page in both API and backend history. API traces include the JSON
request, response, HTTP status, duration, and any returned error. Sensitive
headers are redacted and body capture follows the configured size limit.
The backend trace includes the model and backend, text prompt, requested
parameters, model-loading time (load_ms), slot-waiting time (queue_ms),
inference time (inference_ms), output file size (output_bytes), and returned
metadata, including the usage breakdown. Parameters describe request overrides;
metadata.usage.details reports the effective frames and sampling steps.
Non-text inputs record their type and presence, without copying asset contents.
Trace strings follow the existing backend trace size limit.
A running backend entry appears before model loading begins. Completed entries
contain the details above; failures include the error and the stage that failed.
Total backend duration includes loading, waiting, and inference. Requests rejected
by endpoint validation have an API trace but no animation backend trace.
Usage accounting
Kimodo reports one set of usage measurements through generic backend metadata.
The gRPC Result has a metadata bytes field containing a JSON object; there is
no separate gRPC usage field or model-specific usage message.
Backend metadata
The JSON stored in Result.metadata looks like this:
usage is an application convention inside the generic metadata object.
Other metadata keys and model-specific details can be added without changing
the gRPC definitions or database schema.
For kimodo, input units are the tokens produced by its text encoder’s tokenizer,
including the beginning-of-sequence (BOS) token. Output units are actual generated
frames multiplied by effective sampling steps, after applying model defaults and
request overrides. In the example, 150 frames × 100 steps = 15,000 output units.
HTTP response and recorded usage
For POST /3d/animate, LocalAI returns the backend object under metadata.
Usage appears only at metadata.usage; there is no top-level usage summary.
The following is an excerpt from either a url or b64_json response:
Internal accounting reads metadata.usage directly and records each successful
request once. The existing token-named database columns store the unit counts:
Response metadata
Usage record column
metadata.usage.input_units
PromptTokens
metadata.usage.output_units
CompletionTokens
Sum of input and output units
TotalTokens
The record’s single Metadata column retains the complete backend JSON,
including the rule and frame/step breakdown. With statistics disabled, response
metadata is still returned but no usage record is created.
Both unit counts must be present, nonnegative integers whose sum fits a Go int.
Explicit zero counts are valid. If metadata is absent, the response omits
metadata. Metadata without a usage member is returned, but creates no usage
record. Malformed metadata or invalid usage counts cause metadata to be omitted
and a warning to be logged; the generated asset is still returned. Failed
generations produce no usage record. Counts are never estimated for backends
that do not report them.
Pricing units
Kimodo’s output units are frame-steps, not text tokens. They approximate
computational work rather than runtime or hardware cost. A price per million
output tokens therefore means dollars per million frame-steps for this model:
This describes how to interpret the existing token-based pricing dimensions;
it does not set a price or charge money automatically.
Motion Capture
LocalAI’s gemxcpp backend converts timestamped RGB frames into human poses
using gem-x.cpp. It runs resident
GEM-X, ViTPose and YOLOX models on CPU or Vulkan. Live inference does not need
SAM3D Body. This initial integration is API-only: no Motion UI, offline clip
export, body mesh or SONIC controller is included.
Install and configure
Import https://huggingface.co/LocalAI-io/GEM-X-GGUF through the model importer.
It selects gemxcpp and downloads three checksummed, revision-pinned assets.
These are custom F32 GGUF architectures, not language models. Weight licenses
are described in the source model card. Allow memory for all three models and
execution buffers, beyond their roughly 4 GB combined download size.
Equivalent configuration with existing local files:
Additional options: device:cpu or device:vulkan, and device_index:0.
Without device, the package selects CPU or Vulkan according to its build.
Darwin uses CPU; Metal inference is not supported. Explicit unavailable devices
fail rather than silently falling back. Threads are capped at eight.
window accepts 2–120 observations; detector_interval accepts 1–30 processed
frames. Larger detector intervals reuse the previous crop and may miss movement
or person loss until the next detection. selection:continuity conservatively
associates one unique box; loss/ambiguity clears history. selection:parity
uses upstream’s largest detection/full-image fallback and makes no identity
continuity guarantee. Neither mode is person re-identification.
precision:strict is the default. The launcher fixes GGML Vulkan precision
flags before initialization. precision:backend_default opts out of strict
validation, without promising a faster path. The same F32 model files are used.
Sessions
All endpoints use standard LocalAI authentication, the Motion Capture feature
permission and model access controls. Sessions belong to their creating user.
When authentication is disabled, sessions share the unauthenticated principal.
Legacy admin keys have the existing shared legacy-admin identity.
The response is HTTP 201 with id, model, profile, time_origin and counters.
profile defaults to soma77; time_origin is required (1–128 characters).
A session owns its model’s native temporal state. Only one session per model
is admitted, with up to 16 sessions per frontend and one duplex connection per
session. Additional model configurations consume independent model memory.
Endpoint
Purpose
POST /api/motion/sessions
Create and load a session
GET /api/motion/sessions/{id}
Read frame/pose/drop counters
DELETE /api/motion/sessions/{id}
Cancel and release a session
GET /api/motion/sessions/{id}/poses
Exchange frames and poses over a duplex WebSocket
POST /api/motion/sessions/{id}/tickets
Issue a single-use browser WebSocket ticket
Sessions expire after two minutes without frame activity. Inference also
has a two-minute timeout; initial model loading has a five-minute stream wait
limit, subject to the loader’s own cancellation behavior. Native inference is
synchronous and cannot be interrupted mid-call. Closing stops new work and
discards late results; native cleanup completes after the current call returns.
Session state lives in one frontend process. Use sticky routing for all session
requests in multi-frontend deployments. Backend streaming uses the existing
model loader and keeps its selected gRPC connection for the session. There is
no session migration or recovery after frontend/backend restart.
Duplex frame transport (v2)
The browser negotiates localai.motion.v2 on the existing ticket-authenticated
/poses socket. It sends uncompressed binary protobuf Input.frame and receives
binary Output messages. HTTP remains for discovery, session creation, tickets
and deletion. There is no HTTP frame fallback. The protobuf package remains v1;
the v2 name versions the duplex transport and flow protocol.
Definition precedes a JSON flow hello. Each flow message has type: "flow",
version: 2, a consecutive integer id, release containing decimal sequence
strings, window_frames, max_pending_bytes, max_frame_bytes,
processing_ewma_ms, recommended_fps, queued_frames, queued_bytes,
oldest_age_ms, pressure and cumulative dropped_frames. A completed frame
also has completed_sequence and completed_kind (pose or event). Its binary
output is written before its release; discarded inputs have release only.
While connected, every completed or dropped capture is retired once, and pose identity retains source time.
The initial window is two frames, with zero recommended FPS meaning camera-paced
subject to credits. After a service sample the window is eight. Service EWMA uses
alpha 0.2 and a 1ms floor; normal offered rate is 1.05/service, pressure rate is
0.9/service. Clients should gate capture before canvas/RGB allocation on credits,
outstanding bytes, pacing and prospective WebSocket upload backlog. A recommended
upload backlog limit is two frame sizes or 2MiB, whichever is smaller. Prefer fresh
camera callbacks over a fixed capture timer or a local RGB FIFO. Camera/upload
speed can limit the achieved rate. These are recommendations for external clients;
LocalAI does not include a browser capture client or enforce client-side pacing.
LocalAI uses one reader, one inference worker and one writer. Pending input is
bounded to eight frames/8MiB with a 2MiB encoded frame limit. At six frames or
6MiB, thinning retains half the pending frames nearest evenly spaced source-time
targets across oldest/newest (earlier ties; one survivor means newest). Active
inference is never thinned. Inputs older than 250ms since server admission expire
before enqueue/dispatch. Pressure clears once pending depth is at most two.
The 8MiB pending limit is not a total process-memory claim: encoded/decoded
active and reader payloads add up to approximately another 6MiB, excluding runtime,
protobuf and transport overhead. The writer queue holds at most eight messages;
writes time out at five seconds. External clients should also detect stalled
feedback; a five-second timeout is recommended.
A connection exclusively owns ingress: a second connection receives HTTP 409.
Only localai.motion.v2 is accepted; missing or read-only subprotocols receive HTTP 400. The socket accepts
frames only; reset/camera/model changes require a new session. Disconnect cancels
transport, discards pending input and joins workers before releasing ownership;
this does not preempt an executing native GPU kernel. Only processed frames enter
existing motion_frames_v1 accounting; dropped frames are not billed. Session
summaries expose upload accepted/dropped counts; ingress metrics distinguish
accepted, thinned and expired outcomes. Upload drop counts exclude pending/active
inputs disposed by disconnect; disconnect clears all browser credits. No per-frame content or credentials are logged.
Frame schema and authentication
The authoritative schema is pkg/motion/proto/motion.proto in the LocalAI
repository, package localai.motion.v1. Generate client bindings from that file;
clients do not need LocalAI’s internal backend protocol. Numeric arrays are
packed float32, joint-major then component. JavaScript clients must retain
64-bit sequence/timestamp fields as BigInt or their Protobuf library’s integer
representation, not lossy JavaScript numbers for arbitrarily large values.
Create the session through HTTP JSON.
Connect to /api/motion/sessions/{id}/poses over ws:// or wss://,
requesting subprotocol localai.motion.v2. Native clients can use Bearer
authentication; browsers use their authenticated same-origin session cookie.
Successfully validated Authorization, x-api-key or xi-api-key header
credentials bypass the WebSocket origin check. Invalid or unvalidated headers
do not; cookie-only authentication still follows the origin policy. Standard
browser WebSocket APIs cannot set these headers, so browser clients using
cookies need an explicit CORS policy: set LOCALAI_CORS=true
and LOCALAI_CORS_ALLOW_ORIGINS=https://consumer.example,http://localhost:3000.
This explicit origin policy also permits cross-site session creation, tickets
and deletion through CSRF protection. Authentication and permissions
still apply. Allowed origins use the HTTP CORS matching rules, including explicitly
configured wildcards. Without an explicit policy or validated header credentials,
sockets remain same-origin even though HTTP uses a permissive default. Native clients without an Origin
header are supported. Origin approval does not bypass authentication or session
ownership; browser cookie availability still depends on cookie and browser
policies. Credentials are not URL parameters.
Read the first binary message as Output.definition. It declares joint order,
parents, rest transforms, coordinate conventions, profile and available channels.
The definition is sent once per session connection. A disconnect ends the session;
create a new session before reconnecting.
Send serialized Input.frame messages as binary WebSocket messages, following
the flow credits described above. A frame contains tightly packed RGB8
bytes, width/height, sequence, source microseconds and optional subject box/ID.
Subject boxes use inclusive source pixel XYXY coordinates, bounded by
[0, width-1] and [0, height-1]. Frames must be at least 8 pixels per side, at most 32766 per side and at most
16 million pixels. RGB byte length must equal width × height × 3. The stricter
2MiB encoded-message limit also applies to every upload.
Read Output.pose or Output.event, followed by the JSON completion release.
The first usable observation produces warmup; at least two are needed for a pose.
Invalid frames, replayed sequences and non-increasing timestamps close the
connection without submitting that input to the backend. Source timestamps are
nonnegative microseconds relative to the declared origin and must strictly
increase, as must sequence numbers. Gaps in sequence numbers are allowed.
Create a new session before seeking backward, explicitly resetting or changing
cameras. Long source gaps, changed dimensions or a changed caller-selected
subject reset native context; poses/events carry the new epoch and reset flag.
Intrinsics follow upstream’s image-centre/max-dimension approximation;
calibrated cameras are not supported by this ABI.
The model uses accepted-frame indices, not time-aware irregular sampling. Source
timestamps are preserved, not replaced by receive times or an invented FPS.
Consumers own resampling and clock alignment. Local processing durations do not
measure capture-to-consumer latency.
Pose and lifecycle outputs are delivered in order through the bounded writer
queue. A stalled reader eventually causes a write timeout and session closure;
outputs are not replaced by newer poses. WebSocket uses TCP, so already-buffered
bytes cannot be retracted. Reconnecting requires a new session; there is no
history replay.
Browser WebSocket tickets
Browsers cannot set Authorization on a native WebSocket constructor. After
creating a motion session, exchange your normal credentials for a ticket:
Cookie-authenticated clients can use credentials: "include" instead of the
Authorization header, subject to browser cookie policy. The ticket endpoint uses
normal authentication, Motion feature permission, model access and session
ownership checks. Its JSON response is HTTP 201 with ticket and expires_at,
and Cache-Control: no-store. When auth is disabled, tickets retain the existing
anonymous access policy; they do not create a user or grant additional access.
Tickets expire after 30 seconds, are single use, and are bound to the
exact browser origin and session’s pose WebSocket path. If the HTTP request has
an Origin header, it must match the requested origin. A reconnect requires a new
session and ticket. Redemption consumes the ticket before authentication/upgrade; even a
failed matching upgrade requires a fresh ticket. The original credentials are
revalidated, so revoked keys or sessions cannot redeem outstanding tickets.
Feature, model and ownership permissions are checked again. Successfully redeemed
tickets authorize the bound origin without requiring browser cookie delivery.
The server selects only localai.motion.v2; it never echoes the ticket protocol.
Tickets belong in the protocol list, not in the URL or query string. LocalAI
strips them before upgrade and redacts the protocol header from API traces.
Configure external proxies and request loggers to redact Sec-WebSocket-Protocol
as well. Ticket responses must not be cached or logged.
There are at most 32 outstanding tickets per user (shared for anonymous/legacy
identities) and 4096 per frontend; issuance returns 429 at capacity. Closing a
session revokes its outstanding tickets. The in-memory store is shared by ticket
issuance and upgrade on one frontend; both requests need sticky routing. Restart
invalidates all outstanding tickets. Ticket expiry limits the handshake window,
not the lifetime of an established connection. Ticket requests do not add frame
usage. This first integration supports motion; other WebSocket endpoints do not
yet issue tickets.
Output profiles
soma77: 77 joints, metres, right-handed native SOMA Y-up. Positions have pelvis
translation removed only; root rotation is retained. Local rotations are XYZW;
local translations vary with the emitted frame’s identity/scale. Root axis-angle
is in radians. Root translation is zero: this is not a continuous world trajectory.
smpl24: upstream-validated SOMA-to-SMPL mapping; 24 joint positions with pelvis
translation and anchor rotation removed. The separate anchor is a unit WXYZ
quaternion in the upstream Z-up/base-rotation convention. It reconstructs the
mapped, gravity-aligned points from root-local positions. No SMPL joint rotations,
mesh parameters, physical-base alignment or robot wrist commands are fabricated.
Definitions distinguish neutral reference transforms from per-frame shape.
Quaternions use upstream’s canonical nonnegative-w policy, not temporal sign
smoothing; consumers interpolating rotations should handle equivalent signs.
Events include warmup, lost, ambiguous and reset. Frame flags identify
reset (1), reused crop (2), full-image fallback (4), detector execution (8) and
caller box (16). Track epochs mark acquisitions; automatic parity mode uses
track epoch zero without asserting identity continuity. No 3D confidence is
advertised. Consumers must detect stale streams and choose their own hold,
interpolation or stop behavior.
An external SONIC consumer can request SMPL-24, buffer timed poses and construct
its policy-specific reference windows. LocalAI does not execute that policy,
align references to physical robot state, or run physics.
Observability
With metrics enabled, the existing /metrics exporter includes:
localai_motion_sessions: active sessions.
localai_motion_frames: processed frame outcomes.
localai_motion_uploads: accepted, thinned and expired input frames.
localai_motion_resets: explicit or native context resets.
localai_motion_stage_duration_seconds: detector, ViTPose, GEM and skeleton
construction stage durations from the native pipeline.
Prometheus may append standard counter/unit suffixes. Labels use model/backend,
finite outcome names and fixed stage names, never session IDs or person IDs.
Frame/pose/drop totals are also available through session status.
Frame submissions also use the shared usage accounting pipeline, like animation
requests. Each successfully processed frame records input_units: 1; a pose
records output_units: 1, while warmup, lost and ambiguous outcomes record zero
output units. Records retain accounting_rule: "motion_frames_v1" in their usage
metadata. The existing usage dashboard, storage and billing metrics expose these
units through their legacy prompt/completion/total token fields; they represent
frames, not text tokens. Configure any model pricing in those units.
Accounting happens once per successfully processed WebSocket frame, before
socket delivery. Rejected or dropped inputs and failed inference do not record
usage. Session creation/status/deletion, tickets and WebSocket upgrades do not
record usage either. Shared statistics can be disabled through the existing
statistics configuration.
With backend tracing enabled, a motion trace spans the session and records its
profile, duration, termination reason and counts. Model-load failures use the
existing model-load traces. Logs record lifecycle changes. Images, pose arrays,
credentials and private model paths are not included in motion session traces.
Webcam pose overlays
GEM-X pose messages optionally include image_positions (Protobuf field 13):
packed source-image pixel XY pairs in Definition.joint_names order (48 values for
SMPL24, 154 for SOMA77). The definition advertises the channel and convention
source-pixel xy, joint_names order, top-left origin, unmirrored. Coordinates
reference the exact submitted RGB Frame identified by the pose sequence/timestamp;
use that frame’s width/height, then scale/letterbox with the displayed image. They
are neither normalized crop coordinates nor confidence scores. No image mirroring
is applied. Pixels can fall outside the source image; clients should clip drawing.
The backend projects GEM-X’s emitted camera-space skeleton plus its camera
translation using the native live API’s actual intrinsics: focal length
max(width,height) and image-centre principal point. SMPL uses the mapping from
that native definition, not a hard-coded substitute skeleton. If a joint has
nonpositive depth or projection is nonfinite the optional channel is empty; root
local control data remains separate. Older servers may omit the channel. Do not
invent an image-aligned overlay from root-local positions, anchor or bounding box.
Optional live root displacement
The GEM-X SMPL stream advertises root_displacement only when its native library
supports channel 14. It contains three metres-per-interval components in the
end pose’s anchor-local basis, not velocity or absolute world position. Rotate
by the end pose’s WXYZ anchor for gravity-aligned Z-up displacement. The closed
interval is [displacement_start_time_us, source_time_us], between consecutive
frames actually processed by GEM-X (including its warmup observation).
This uses the last two decoded world translations inside one rolling window;
it does not subtract absolute translations from separate windows. The current
frame’s unobserved next-interval prediction is not emitted. root_translation
remains zero for compatibility. Older native libraries omit the new channel.
Consumers must establish a baseline after an epoch/track change, reset, missing
interval or reconnect; they must not add a delta across those boundaries. A
dropped input changes the model’s accepted-frame spacing: these estimates are
not time-normalized or contact-refined, and integration can drift. Robot/world
placement is a separate consumer-owned transform and need not reset on tracking
loss. Model-backed checks cover interval boundaries and coordinate-basis
consistency; they do not establish trajectory accuracy against ground truth.